YAK – Yet Another Kernel
YAK is a small x86-64 operating system written from scratch in Rust, for learning how a kernel works by reading, running, testing and changing one. It runs in QEMU (BIOS and UEFI).
Where to start
- Get it running – the quick start in the README: host packages,
make run,make check. - Follow one thing through the kernel – the walkthroughs trace a boot, a key press, a pipeline and a page fault through the code, with links to every function involved.
- Change something and watch what happens – the experiments, each with a measured result.
- Build on it – adding a syscall, a program, a test.
The learning notes explain every subsystem in the order it was built; the design notes give the reasons behind each decision, and the bug log tells what went wrong and how it was found.
The course
YAK is turning into a course in which you rebuild the kernel chapter by chapter, each chapter a runnable, tested state of its own. The first chapters are being written; the plan is in the roadmap.
About
YAK is free software under the GNU General Public License v3 or later (LICENSE), developed by FreakySneaky787 together with an AI assistant. Source code and issues: github.com/FreakySneaky787/yak-kernel.
The course: build a kernel, chapter by chapter
In this course you write an x86-64 kernel in Rust from nothing, the same way YAK was built: one small, working step at a time. Every chapter ends with a kernel that boots in QEMU and passes its own tests.
How it works
- Each chapter has a page here (what we build, why, the code with explanations) and a folder in the
repository,
course/:course/01-boot/,course/02-tests/, … Each folder is a complete project – the state of the kernel at the end of that chapter. - Follow along: start with an empty directory and type the code from the chapter pages. When you are stuck, compare with the chapter's folder.
- Or jump in anywhere: copy a chapter folder and continue from there. Every folder builds on its own.
- In every folder,
make runboots the kernel in a QEMU window andmake testboots it headless and checks its output – the same check the project's CI runs on every chapter. - The finished kernel of the project (the "reference kernel") is much bigger than the course so far; the walkthroughs explain it as it is today.
What you need
- The host tools from the quick start (QEMU, xorriso, make, gcc, git, python3; from
chapter 17 on also dosfstools and mtools, which make the test disks) and Rust via rustup. Each chapter folder contains a
rust-toolchain.toml; rustup installs the exact compiler version. - Some Rust: ownership,
struct/impl, traits, modules. No previous kernel or assembly knowledge – the chapters explain what the hardware expects.
Chapters
| # | Chapter | You end up with |
|---|---|---|
| 1 | Booting with Limine | a kernel that boots and prints to the serial port |
| 2 | Testing without an operating system | make test running unit tests inside the kernel |
| 3 | Text on the screen | a framebuffer console with its own font renderer |
| 4 | GDT and TSS | our own segments and a safe stack for double faults |
| 5 | Interrupts and exceptions | exception handlers – a page fault reports itself, a double fault survives a broken stack |
| 6 | Hardware interrupts and the timer | the PIC moved to vector 32, a 100 Hz timer, sleep_ms that waits in hlt |
| 7 | The keyboard | keys from the PS/2 keyboard on the screen – IRQ 1, a ring buffer, a scancode decoder; the end of part I |
| 8 | Physical memory | Limine's memory map and a bitmap frame allocator, reached through the higher-half direct map |
| 9 | Paging | translate, map and unmap on the live page tables, and kernel stacks whose overflow hits a guard page |
| 10 | The heap | a free-list allocator behind #[global_allocator] on pages mapped with map – Box, Vec and String in the kernel; the end of part II |
| 11 | A first shell | a prompt, a line editor, words with quotes and a table of commands – the kernel answers what you type; part III |
| 12 | ACPI and the APIC | the MADT read from the ACPI tables, the I/O APIC routing timer and keyboard, and the local APIC timer measured against the PIT; part IV |
| 13 | Threads and a scheduler | kernel threads with their own stacks, a context switch in assembly, preemption by the APIC timer, and waiting that blocks instead of spinning |
| 14 | The other CPUs | the other cores started through a real-mode trampoline (INIT/STARTUP IPIs), each with its own GDT, TSS and stack, running jobs sent with run_on |
| 15 | One scheduler for all CPUs | every CPU runs threads from one queue: a timer and an idle thread per CPU, the scheduler lock held through the switch, waiting that cannot lose a wake-up; the end of part IV |
| 16 | PCI and a SATA disk | every PCI device listed at boot, and an AHCI driver that reads sectors from a SATA disk by DMA; part V |
| 17 | Reading FAT32 | files and directories from a FAT32 volume made by mkfs.fat and mtools: cluster chains, long names, ls and cat |
| 18 | Writing FAT32 | new files, appended data, directories and removal, written in a safe order – fsck.fat finds nothing, mtools reads what the kernel wrote |
| 19 | A block cache, and the disk's interrupt | a write-through sector cache (394 disk commands for a file become 196, then 0) and MSI from the SATA controller, so disk commands sleep in wait_for; the end of part V |
| 20 | Ring 3 and the first system call | code in ring 3 that can only compute and ask: user segments, RSP0 per thread, USER pages, iretq, int 0x80 with write and exit, faults that end the program, not the kernel; part VI |
For now the course ends with chapter 20 (my decision of 2026-11-06; the plan for chapters 21–36 is in
docs/ROADMAP.md). The pilot (chapters 1–4) gets a round of feedback from readers, and the chapters
after it change with what they report. If you get stuck, use the issue form
I got stuck in a course chapter;
if something was unclear even though it worked, use
Feedback on the course.
That is exactly the feedback the pilot is for – CONTRIBUTING.md says more.
1 – Booting with Limine
Goal: a kernel that a real bootloader starts in 64-bit mode and that greets us on the serial port.
You end up with: make run shows Hello from YAK! in your terminal; make test checks it automatically.
Code: course/01-boot/
Background: who starts a kernel?
When a PC starts, the firmware (BIOS or UEFI) runs first. It knows nothing about our kernel; it loads a bootloader from a disk or CD. The bootloader's job is to load the kernel file into memory, put the CPU into the mode the kernel expects and jump to the kernel's first instruction.
x86-64 CPUs start in 16-bit real mode, like a PC from 1981. Getting to 64-bit long mode needs a descriptor table, page tables and several mode switches – interesting, but not where we want to begin. We use Limine, a modern bootloader that does all of this and then jumps into our kernel with:
- the CPU in 64-bit long mode, paging on, interrupts off,
- our kernel loaded at the address its ELF file asks for,
- a stack to run on,
- answers to requests our kernel left for it (we use one in this chapter).
The kernel is an ordinary ELF file – the format Linux uses for programs – built by Rust and linked by GNU ld.
Step 1: a Rust project without an operating system
Every chapter folder pins the Rust compiler in rust-toolchain.toml; rustup installs it on the first build. We
need a nightly compiler for features later chapters use, plus the x86_64-unknown-none target: x86-64 code that
expects no operating system underneath.
kernel/Cargo.toml names our only dependency, the Rust definitions of the Limine protocol:
[dependencies]
# Rust definitions of the Limine boot protocol (the only crate besides `spin` in the whole project)
limine = "0.6.5"
and makes a panic stop the kernel instead of trying to unwind the stack – there is no runtime that could do that:
[profile.dev]
panic = "abort"
kernel/.cargo/config.toml sets the target and tells the linker how to build a kernel:
[build]
# A target without an operating system underneath: no std, no libc, no default linker script
target = "x86_64-unknown-none"
The rustflags there choose GNU ld, our own linker script, and the kernel code model: the code lives in the top
2 GiB of the 64-bit address space, at 0xffffffff80000000 – the higher half. Programs will later get the
lower half; the kernel stays out of their way.
Step 2: the memory layout – linker.ld
The linker script decides where every part of the kernel lands:
ENTRY(kmain)
kmain is the function Limine jumps to. Then the address of everything that follows:
    . = 0xffffffff80000000;

    .limine_requests : {
        KEEP(*(.limine_requests_start))
        KEEP(*(.limine_requests))
        KEEP(*(.limine_requests_end))
    } :limine_requests
The Limine requests come first, in their own section, between a start and an end marker – that is where Limine
looks for them. KEEP stops the linker from throwing them away (no code refers to them). After that come code
(.text), constants (.rodata) and variables (.data, .bss), each starting on a new page so that later we can
give them different permissions (code executable but read-only, data writable but not executable).
Step 3: talking to Limine
kernel/src/main.rs starts with two attributes that switch off what a normal Rust program takes for granted:
#![allow(unused)]
#![no_std] // no standard library: it needs an operating system, and we are writing one
#![no_main] // no `main`: nobody calls it - Limine jumps to `kmain` (see linker.ld: ENTRY(kmain))
fn main() {
}
Without std we still have core: integers, Option, iterators, fmt – everything that needs no operating
system.
The one request we make is the base revision – which version of the boot protocol we speak:
#![allow(unused)]
fn main() {
/// Which version of the boot protocol we speak. Limine sets a field in it to 0 if it supports it.
#[used]
#[unsafe(link_section = ".limine_requests")]
static BASE_REVISION: BaseRevision = BaseRevision::new();
}
#[used] keeps the static in the binary, link_section puts it where the linker script collects requests. The two
markers REQUESTS_START and REQUESTS_END are declared the same way. Limine reads the magic numbers inside these
structures directly from the kernel file before it starts the kernel.
Step 4: the serial port
The screen needs a driver (chapter 3). The serial port needs about 20 lines, and QEMU connects it to our terminal – so it is the first thing a kernel uses to talk, and later the channel all our tests run over.
The 16550 UART of COM1 sits at I/O port 0x3F8. x86 has a separate small address space for devices, reached
with the instructions in and out; Rust has no word for them, so we use inline assembly:
#![allow(unused)]
fn main() {
/// Writes `value` to an I/O port (the x86 `out` instruction).
unsafe fn outb(port: u16, value: u8) {
    unsafe { core::arch::asm!("out dx, al", in("dx") port, in("al") value) };
}
}
Sending a byte means waiting until the UART can take it, then writing it to its data register:
#![allow(unused)]
fn main() {
fn send(byte: u8) {
    // Line status register, bit 5: the transmit register is empty and takes the next byte
    while unsafe { inb(COM1 + 5) } & 0x20 == 0 {
        core::hint::spin_loop();
    }
    unsafe { outb(COM1, byte) };
}
}
To get format!-style output for free, we implement core::fmt::Write for a zero-sized Serial type and wrap
writeln! in a macro, serial_println!. (init sets the speed and the data format; the comments in
serial.rs explain each register.)
Step 5: the entry point
#![allow(unused)]
fn main() {
/// Limine jumps here: 64-bit long mode, paging on, interrupts off, on a stack Limine set up.
#[unsafe(no_mangle)]
extern "C" fn kmain() -> ! {
    serial::init();
    serial_println!("Hello from YAK!");
    if !BASE_REVISION.is_supported() {
        serial_println!("Limine does not support our base revision");
        halt();
    }
    serial_println!("Limine base revision {} is supported.", BaseRevision::MAX_SUPPORTED);
    halt()
}
}
#[unsafe(no_mangle)]keeps the namekmainin the ELF file, soENTRY(kmain)finds it.extern "C"uses the C calling convention, which Limine expects.-> !means "never returns": there is nothing to return to.
When the kernel is done, it halts: cli switches interrupts off, hlt stops the CPU until the next interrupt –
which never comes. The loop is there because some events (NMIs) can still wake the CPU.
The panic handler is required in no_std: Rust calls it on panic!, failed assert!s, out-of-range indexing.
Ours prints the message and halts.
Step 6: a bootable CD image
run-qemu.sh packs the kernel and Limine's files into an ISO image with xorriso – one image that boots with BIOS
and with UEFI – and starts QEMU with it. limine.conf on the image tells Limine which file to boot and with which
protocol. -no-reboot on the QEMU command line turns a reset of the machine into the end of QEMU, so a crashing
kernel stops instead of booting again and again.
These files – run-qemu.sh, limine.conf, the Makefile and rust-toolchain.toml – are tooling, not kernel code.
Copy them from the chapter folder instead of typing them; each one starts with a comment that explains it.
Run it
cd course/01-boot
make run
The first make downloads Limine and builds the kernel. QEMU opens a window (empty – we do not draw anything yet)
and your terminal shows:
Hello from YAK!
Limine base revision 6 is supported.
Close the QEMU window to stop it.
The test
make test boots the same image without a window, writes the serial output to build/serial.log and passes when
every line of expected.txt appears in it within 30 seconds. Remove the Hello line from kmain and the test
fails with both the expected and the actual output – try it. This is the pattern for the whole course: every
chapter has a test that fails without the chapter's code.
What can go wrong
- Nothing on the terminal, QEMU just sits there: usually the kernel was not found or not started. Check that
the ISO contains
boot/kerneland thatlimine.confpoints to it (path: boot():/boot/kernel). error: linking with ld.bfd failed: GNU ld (packagebinutils) is missing.- "relocation truncated to fit": code built for a different code model than the linker script expects; the
code-model=kernelflag in.cargo/config.tomlbelongs to the higher-half address inlinker.ld. - QEMU closes by itself right after the start: a triple fault – the CPU hit an error while handling an
error and reset the machine, which
-no-rebootturns into the end of QEMU. Add-d int,cpu_reset -D qemu.logto the QEMU command inrun-qemu.shand read the last exception in the log. (We will set up proper exception handlers in a later chapter.)
Experiments
- Request a revision Limine does not know:
BaseRevision::with_revision(99). What does the kernel print now? - Remove
#[used]fromBASE_REVISION. Does the kernel still say the revision is supported? Look at the ELF withobjdump -h kernel/target/x86_64-unknown-none/debug/kernelbefore and after. - Panic on purpose: put
panic!("on purpose")after the greeting. Where does the message come from?
2 – Testing without an operating system
Goal: unit tests that run inside the kernel, started with a plain cargo test.
You end up with: make test builds a test kernel, boots it in QEMU, runs every test and reports PASS or FAIL
through QEMU's exit status – no human has to look at the output.
Code: course/02-tests/ (chapter 1 plus
testing.rs, qemu.rs and a new run-qemu.sh)
What changed: diff -ru course/01-boot course/02-tests (in the repository) shows every line this chapter adds.
Why this comes so early
Everything later – memory management, the scheduler, the file system – is easier to get right with tests, and much harder to debug without them. A kernel bug often shows up far from its cause. The reference kernel has over 200 such tests; every one of them uses what this chapter builds.
Background: the problem
cargo test normally builds a program that contains your tests and the standard test harness, and runs it on your
machine. Neither works for us: the harness needs std, and our code only runs on bare metal. Rust has an unstable
feature for exactly this case, custom test frameworks: the compiler still finds all tests, but hands them to a
function we write.
Step 1: let the compiler collect the tests
Three lines at the top of main.rs:
#![allow(unused)]
#![feature(custom_test_frameworks)]
#![test_runner(crate::testing::runner)]
#![reexport_test_harness_main = "test_main"]
fn main() {
}
- Tests are marked
#[test_case](not#[test]). - In a test build, the compiler generates a function that calls
testing::runnerwith a slice of all of them, and names ittest_main, so that we can call it.
The test build needs its own entry point – it should run the tests, not greet us:
#![allow(unused)]
fn main() {
/// The entry point of the test build (`cargo test`): run every `#[test_case]`.
#[cfg(test)]
#[unsafe(no_mangle)]
extern "C" fn kmain() -> ! {
    serial::init();
    test_main();
    halt() // not reached: the runner ends QEMU
}
}
The normal kmain gets #[cfg(not(test))], so exactly one of the two exists in each build. In Cargo.toml the
[[bin]] section no longer says test = false – otherwise cargo test would skip our crate.
Step 2: the runner
testing.rs turns every test into something that prints its own name:
#![allow(unused)]
fn main() {
impl<T: Fn()> Testable for T {
    fn run(&self) {
        serial_print!("{} ... ", core::any::type_name::<T>());
        self();
        serial_println!("[ok]");
    }
}
}
core::any::type_name gives the full path of the function, for example kernel::testing::trivial_assertion. The
runner runs them one after another:
#![allow(unused)]
fn main() {
pub fn runner(tests: &[&dyn Testable]) -> ! {
    serial_println!("Running {} tests", tests.len());
    for test in tests {
        test.run();
    }
    serial_println!("All tests passed.");
    qemu::exit(ExitCode::Success)
}
}
A failing assert! panics – so in a test build, the panic handler is where a test fails. It prints the message
and ends QEMU with the failure code:
#![allow(unused)]
fn main() {
pub fn panic_handler(info: &PanicInfo) -> ! {
    serial_println!("[failed]\n");
    serial_println!("Error: {}", info);
    qemu::exit(ExitCode::Failed)
}
}
(serial_print! is new in serial.rs: serial_println! without the line break.)
Step 3: telling the outside world – isa-debug-exit
A test that only prints its result still needs someone to read it. QEMU has a tiny device for this: isa-debug-exit. Writing a number to its I/O port ends QEMU immediately, with an exit status derived from the number:
#![allow(unused)]
fn main() {
#[derive(Clone, Copy)]
#[repr(u32)]
pub enum ExitCode {
    Success = 0x10, // QEMU exits with 33
    Failed = 0x11,  // QEMU exits with 35
}
}
QEMU exits with (value << 1) | 1 – always odd, so a status can never be confused with QEMU's own 0 (normal
end) or 1 (error). We picked 0x10 and 0x11; any two values work. The device only exists when QEMU is started
with -device isa-debug-exit,iobase=0xf4,iosize=0x04.
Step 4: cargo test boots QEMU
Cargo can hand a built program to a runner instead of executing it. In kernel/.cargo/config.toml:
# `cargo run` and `cargo test` hand the built kernel to this script, which boots it in QEMU
runner = "../run-qemu.sh"
run-qemu.sh now has to know whether it got the normal kernel (cargo run) or a test kernel (cargo test). Cargo
names test binaries kernel- followed by a 16-digit hash, so the script looks at the file name:
if [[ -z "${KERNEL_MODE:-}" ]]; then
    if [[ "$(basename "$ELF")" =~ -[0-9a-f]{16}$ ]]; then KERNEL_MODE=test; else KERNEL_MODE=run; fi
fi
In test mode it starts QEMU without a window, with a timeout, and translates the exit status:
    case $code in
        33)  echo "[test] PASS"; exit 0 ;;  # 0x10: all tests passed
        124) echo "[test] FAIL: timeout after ${TIMEOUT}s - a test hangs?"; exit 1 ;;
        *)   echo "[test] FAIL: QEMU exit status $code"; exit 1 ;;  # 35 = 0x11: a test failed
    esac
The timeout matters: a test that hangs must fail too, or nobody notices. The check from chapter 1 (the normal
kernel prints the lines of expected.txt) is still there as KERNEL_MODE=check.
Run it
cd course/02-tests
make test
Running 3 tests
kernel::limine_supports_our_base_revision ... [ok]
kernel::serial::long_lines_are_sent_completely ... 0123456789abcdef0123456789abcdef…
[ok]
kernel::testing::trivial_assertion ... [ok]
All tests passed.
[test] PASS
[check] PASS - the serial output contains every line of expected.txt
Now break a test – change assert_eq!(1 + 1, 2) in testing.rs to 3:
kernel::testing::trivial_assertion ... [failed]

Error: panicked at src/testing.rs:41:5:
assertion `left == right` failed
  left: 2
 right: 3
[test] FAIL: QEMU exit status 35
and make stops with an error – exactly what a CI system needs.
The tests of this chapter
trivial_assertion– the framework itself works.limine_supports_our_base_revision– the boot protocol handshake from chapter 1.long_lines_are_sent_completely– 128 bytes in a row, more than the UART's 16-byte buffer:sendmust wait for the hardware instead of losing bytes.
What can go wrong
cargo testsays "running 0 tests" and passes immediately, without QEMU: the binary hastest = falseinCargo.toml, or the tests are marked#[test]instead of#[test_case].- Test mode is never detected, the test kernel opens a window: the file-name rule did not match. The reference kernel had exactly this bug when a new Cargo version moved the test binaries to another directory (bug #1 in the bug log) – which is why the rule looks at the name, not the path.
- QEMU exits with status 1 instead of 33/35: the
-device isa-debug-exit,…option is missing. - A test hangs forever: without the timeout in
run-qemu.shnothing would ever end it.
Experiments
- Add a test that loops forever (
loop {}). How long until it fails, and what does the script print? - Call
qemu::exit(qemu::ExitCode::Success)at the end of the normalkmain(remove the#[cfg(test)]in front ofmod qemufirst). What happens tomake run– and to the window? - Make the panic in a test happen inside
serial_println!(format something that panics in itsDisplayimplementation). Is the error still reported? Why might a panic handler that prints be dangerous?
3 – Text on the screen
Goal: println! that writes to the screen – with our own font renderer, character by character, pixel by pixel.
You end up with:
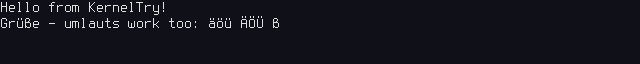
Code: course/03-console/ (chapter 2
plus font.rs, console.rs, the font file and the spin crate)
What changed: diff -ru course/02-tests course/03-console (in the repository) shows every line this chapter adds.
Background: a framebuffer
Old PCs had a text mode: write a character code to address 0xB8000 and the graphics card draws it. UEFI
machines no longer have it. What every machine has is a framebuffer – a region of memory in which every pixel
of the screen is a few bytes. Write 0x00FF0000 into the right place and that pixel turns red. Everything else –
letters, lines, windows – is software.
Limine sets a graphics mode for us and tells us where the framebuffer is, if we ask:
#![allow(unused)]
fn main() {
/// A framebuffer: memory whose bytes are the pixels on the screen. Limine sets up a graphics mode for us.
#[used]
#[unsafe(link_section = ".limine_requests")]
static FRAMEBUFFER: FramebufferRequest = FramebufferRequest::new();
}
The answer has five numbers we need: the address, width and height in pixels, bpp (bits per pixel;
we only handle 32: one u32 per pixel, 0x00RRGGBB) and the pitch – the number of bytes from one row of
pixels to the next. The pitch can be larger than width × 4; graphics hardware likes rows aligned to round
numbers. Forgetting the pitch gives a slanted, garbled picture.
Step 1: a font – PSF2
To draw a letter we need its shape. We use the console font of Linux, Terminus 8×16, in the PSF2 format: every
glyph is 16 bytes, one byte per pixel row, the highest bit is the leftmost pixel. An A looks like this
(# = bit set):
........
...##...
..#..#..
.#....#.
.#....#.
.######.
.#....#.
.#....#.
(the real glyph is 16 rows; this is a sketch). The file is built into the kernel – there is no file system yet:
#![allow(unused)]
fn main() {
/// The font built into the kernel: Terminus 8x16 (SIL Open Font License, see assets/README.md).
pub static TERMINUS: &[u8] = include_bytes!("../assets/terminus-8x16.psf");
}
Font::parse checks the magic number 0x864ab572, reads the glyph size from the header and builds a table from
characters to glyph numbers. The table is needed because glyph 65 is not necessarily A: after the glyphs, the
file lists for each glyph which Unicode characters it shows (read_unicode_table). We keep characters below 256 –
enough for English and German. Everything else is drawn as ?:
#![allow(unused)]
fn main() {
    /// The pixel rows of the glyph for `c` (one byte per row); characters the font lacks become '?'.
    pub fn glyph(&self, c: char) -> &[u8] {
        let index = self.index_of(c).or_else(|| self.index_of('?')).unwrap_or(0);
        let start = self.glyph_offset + index * self.height;
        &self.data[start..start + self.height]
    }
}
Step 2: drawing a character
The console divides the screen into cells of 8×16 pixels – on QEMU's 1280×800 screen that is 160 × 50 characters. Drawing a character means: for every row of its glyph, for every bit, one pixel:
#![allow(unused)]
fn main() {
    /// Draws the glyph of `c` into the cell at `column`, `row`: every font bit becomes one pixel.
    fn draw(&mut self, c: char, column: usize, row: usize) {
        let (x0, y0) = (column * self.font.width, row * self.font.height);
        for (dy, bits) in self.font.glyph(c).iter().enumerate() {
            let line = (y0 + dy) * self.stride + x0;
            for dx in 0..self.font.width {
                let on = bits & (0x80 >> dx) != 0; // the highest bit is the leftmost pixel
                self.pixels[line + dx] = if on { FOREGROUND } else { BACKGROUND };
            }
        }
    }
}
stride is the pitch in pixels (pitch / 4). Note that the console does not draw to "the screen" but into
pixels: &mut [u32] – any piece of memory. That is what makes it testable (step 5).
Step 3: lines, wrapping, scrolling
put_char keeps a cursor (column, row). \n moves to the next line; a full line wraps; and when the cursor
falls off the bottom, everything moves up by one text row:
#![allow(unused)]
fn main() {
    /// Moves every text row up by one (copying pixels) and clears the bottom one.
    fn scroll(&mut self) {
        let row_pixels = self.font.height * self.stride; // one row of text, in pixels
        let used = self.rows * row_pixels;
        self.pixels.copy_within(row_pixels..used, 0);
        self.pixels[used - row_pixels..used].fill(BACKGROUND);
    }
}
That is a copy of almost 4 MB per scrolled line – slow, but simple and correct. (The reference kernel keeps the characters in a grid as well and redraws from it; that is an optimisation for later.)
Step 4: a global console and println!
Code everywhere in the kernel should be able to print, so the console is a global. A global that changes needs
protection against two users at once; with only one CPU and no interrupts yet that cannot happen, but Rust does not
know that and insists – rightly: interrupts come in a later chapter, and then a second user can appear any time. We use a spin lock from the spin crate:
#![allow(unused)]
fn main() {
/// The console on the screen - `None` until `init` found a framebuffer.
pub static CONSOLE: Mutex<Option<Console<'static>>> = Mutex::new(None);
}
init turns Limine's answer into a Console – the one unsafe step, creating a slice from the framebuffer
address, is where we promise Rust that this memory really is ours. print! and println! write to the console
and the serial port, so the tests from chapter 2 still see everything.
In main.rs, mod console; and mod font; join the module list, spin = "0.12.3" joins the dependencies in
Cargo.toml, and kmain sets up the console once the base revision is checked – from then on println! works:
#![allow(unused)]
fn main() {
    console::init();
    println!("Hello from YAK!");
    match console::CONSOLE.lock().as_ref() {
        Some(c) => serial_println!("Console: {} x {} characters", c.size().0, c.size().1),
        None => serial_println!("No 32-bit framebuffer - text goes to the serial port only"),
    }
}
The test kmain calls console::init() too, after serial::init(): the test on the real framebuffer needs it.
Step 5: testing a picture
How do you test drawing without looking at a screen? Draw into a tiny screen in memory – 10 × 3 characters, with a stride of 88 pixels for an 80-pixel-wide picture, so that a pitch mistake shows up – and check the pixels:
#![allow(unused)]
fn main() {
    #[test_case]
    fn a_full_screen_scrolls_up() {
        let mut pixels = [0u32; STRIDE * H];
        let mut c = console(&mut pixels);
        write!(c, "a\nb\nc\nd").unwrap(); // 4 lines on a 3-row screen: "a" scrolls away
        assert!(shows(&pixels, 0, 0, 'b') && shows(&pixels, 0, 1, 'c') && shows(&pixels, 0, 2, 'd'));
    }
}
shows compares a cell with the font's glyph, pixel by pixel. Together with tests for placement, wrapping, the
padding right of the picture and the font parser, make test now runs 12 tests. One of them works on the real
framebuffer: the console must cover the whole screen Limine gave us.
Run it
cd course/03-console
make run
The QEMU window shows the two lines from the picture above; the terminal shows them too (serial port), plus the console size:
Hello from YAK!
Console: 160 x 50 characters
Grüße - umlauts work too: äöü ÄÖÜ ß
What can go wrong
- Slanted or torn text: the pitch was ignored (
widthused instead ofstride). The test with the 88-pixel stride catches exactly this. - Some characters show up as
?: they are not in our Latin-1 table – for example–(U+2013, a dash) or€. That is the fallback working, not a bug. - Nothing on the screen, but the serial port works: Limine gave no 32-bit framebuffer (
bpp != 32), andinitleftCONSOLEatNone. - The kernel hangs in
println!: a spin lock taken twice – for example a panic while the console is locked, if the panic handler prints to the console. Our panic handler only uses the serial port, and ourSerialhas no lock (it has no state to protect). (The reference kernel's panic handler usestry_lockfor the console – seepanic_reportinkernel/src/lib.rs.)
Experiments
- Swap
FOREGROUNDandBACKGROUND. Then try0x00FF0000– which colour, and why is the byte orderRRGGBB? - Print 60 lines in a loop and watch it scroll. How long does it take (count with the serial output)?
- Draw every pixel of a glyph twice as wide and twice as high (a 16×32 console). What has to change?
4 – GDT and TSS
Goal: our own Global Descriptor Table and Task State Segment – the CPU structures every x86-64 kernel
needs before it can handle exceptions safely.
You end up with: the kernel runs on segments we defined, and a separate, known-good stack is ready for the day
the normal stack breaks (used in the next chapter).
Code: course/04-gdt/ (chapter 3 plus
gdt.rs)
What changed: diff -ru course/03-console course/04-gdt (in the repository) shows every line this chapter adds.
Background: segments, then and now
On the 8086, memory was addressed as segment:offset. Later CPUs turned segments into entries of a table – the GDT – with a base address, a size limit and permissions. In 64-bit mode almost all of that is switched off: base and limit are ignored, memory protection is done by page tables. What is left:
- the code segment (register CS) still tells the CPU two things: this is 64-bit code (the L bit) and this is the kernel (privilege level 0 – user programs will run at level 3);
- a data segment for the stack segment register SS;
- the TSS, which is no longer about "tasks" but holds stacks the CPU switches to by itself – for interrupts from user programs (a later chapter) and for chosen exceptions: the Interrupt Stack Table.
Limine already loaded a GDT before it started us (cs was 0x28, ss was 0x30 when we measured). We replace it
because it lives in memory that belongs to the bootloader, because it has no TSS – and because we want to know
exactly what our kernel runs on.
Step 1: the descriptors
A descriptor is 8 bytes with the bits spread over the word for historic reasons. For a 64-bit kernel only a few matter, so the two we need are constants:
#![allow(unused)]
fn main() {
const KERNEL_CODE: u64 = 0x00AF_9A00_0000_FFFF; // P | DPL0 | S | E | RW, L = 1, G = 1
const KERNEL_DATA: u64 = 0x00CF_9200_0000_FFFF; // P | DPL0 | S | RW, D/B = 1, G = 1
}
Read 0x9A as: present, privilege level 0, a code/data (not system) segment, executable, readable. The flags
nibble after it, 0xA, sets G (limit counted in 4 KiB pages – irrelevant in 64-bit mode) and L – 64-bit code. Entry 0 must be the null descriptor; a selector is simply the byte offset
of an entry, so our segments are 0x08 (code) and 0x10 (data).
Step 2: the TSS
The 64-bit TSS is a 104-byte structure; Rust must lay it out exactly as the CPU expects:
#![allow(unused)]
fn main() {
/// The 64-bit TSS (Intel SDM Vol. 3A, section 8.7): 104 bytes, some of its fields not 8-byte aligned.
#[repr(C, packed(4))]
pub struct TaskStateSegment {
}
repr(C) keeps the field order, packed(4) stops Rust from inserting padding before the 8-byte fields that start
at offset 4. A compile-time assertion makes sure we got it right:
#![allow(unused)]
fn main() {
const _: () = assert!(size_of::<TaskStateSegment>() == 104);
}
The interesting field is interrupt_stacks – seven stack pointers, IST1 to IST7. We put the top of a 20 KiB
double fault stack into IST1. Why a separate stack? Imagine the kernel's stack overflows: the CPU tries to push
the exception frame for the resulting page fault – onto the broken stack – and fails again. That second failure is
a double fault. If the double fault handler also used the broken stack, a third failure would follow: a triple
fault, and the machine resets. With IST1 the CPU switches to a fresh stack before pushing anything. (The handler
itself comes in chapter 5; today we only prepare the stack.)
Step 3: a TSS descriptor
The GDT points to the TSS with a system descriptor of 16 bytes – two entries – with the 64-bit address cut into four pieces:
#![allow(unused)]
fn main() {
fn tss_descriptor(base: u64) -> (u64, u64) {
    let limit = (size_of::<TaskStateSegment>() - 1) as u64;
    let mut low = limit & 0xFFFF;
    low |= (base & 0xFF_FFFF) << 16; // base bits 0..24
    low |= 0x89 << 40; // P = 1, DPL 0, type 0x9 = available 64-bit TSS
    low |= ((limit >> 16) & 0xF) << 48;
    low |= ((base >> 24) & 0xFF) << 56; // base bits 24..32
    (low, base >> 32) // the second entry holds base bits 32..64
}
}
So the table is: null, kernel code, kernel data, TSS low, TSS high – the TSS selector is 0x18.
Step 4: loading everything
Three instructions make the CPU use our structures:
lgdtloads the address and size of the new table. Nothing changes yet – the CPU still uses the old, cached segments.- The segment registers are reloaded. Data segments are easy (
mov ss, …), but CS cannot be written withmov. The trick is a far return: push the new CS and a return address, thenretfq"returns" to the very next instruction – with our code segment:
#![allow(unused)]
fn main() {
        asm!(
            "push {selector}",
            "lea {tmp}, [rip + 2f]",
            "push {tmp}",
            "retfq",
            "2:",
            selector = in(reg) KERNEL_CODE_SELECTOR as u64,
            tmp = lateout(reg) _,
            options(preserves_flags),
        );
}
ltrloads the task register with the TSS selector.
GDT and TSS must live as long as the kernel – the CPU keeps using them – so they are statics, built once at
init with spin::Once.
Step 5: calling it
main.rs gets mod gdt; next to the other modules, and both entry points call gdt::init() right after the
console – the normal kmain and the test kmain, because the tests check the loaded segments:
#![allow(unused)]
fn main() {
    console::init();
    gdt::init();
    println!("Hello from YAK!");
}
At the end, the normal kmain reports what it loaded:
#![allow(unused)]
fn main() {
    println!(
        "GDT loaded: code segment {:#x}, TSS {:#x}, double fault stack top {:#x}",
        gdt::KERNEL_CODE_SELECTOR,
        gdt::TSS_SELECTOR,
        gdt::double_fault_stack_top()
    );
}
The tests
make test now runs 16 tests; four are new:
our_segments_are_loaded– CS is0x08, SS is0x10, the task register is0x18;gdtr_points_to_our_table–sgdt(the opposite oflgdt) returns our table's address and size;tss_descriptor_scatters_the_base– the bit puzzle of step 3 with a known address;the_double_fault_stack_is_in_the_tss– IST1 is the top of our stack, 16-byte aligned.
Without the call to gdt::init() in the test kmain, the GDT test fails – try it.
Run it
cd course/04-gdt
make run
GDT loaded: code segment 0x8, TSS 0x18, double fault stack top 0xffffffff8…
(the exact address depends on where the linker put the stack.)
What can go wrong
- The machine resets right after
lgdt: a wrong descriptor – most often the code segment without the L bit. The CPU then believes it runs 32-bit code and the next instruction is garbage.-d int,cpu_reseton the QEMU command line shows the exception that started it. - General protection fault at
ltr: the TSS descriptor is wrong (type not0x9, or not present), orltrwas run twice – a loaded TSS is marked busy, and loading a busy TSS faults. - The TSS is 112 bytes instead of 104:
repr(C)alone adds padding; the assertion catches it at compile time. - A double fault still resets the machine (chapter 5): an IST stack pointer to the bottom instead of the top of the stack – stacks grow downwards.
Experiments
- Remove the L bit from
KERNEL_CODE(0x00AF…→0x008F…). What happens, and what does-d int,cpu_reset -D qemu.logsay? - Call
gdt::init()twice. Which instruction fails the second time, and why? - Print Limine's selectors before
gdt::init()(mov {0:x}, cs). What does Limine's GDT probably contain in entries 1–4?
5 – Interrupts and exceptions
Goal: an Interrupt Descriptor Table with handlers for the CPU's exceptions – so that a bug in the kernel
reports what happened instead of resetting the machine.
You end up with: a breakpoint (int3) that is handled and returns; a page fault that names the address and the
cause; and a double fault that survives a broken stack, on the stack we prepared in chapter 4.
Code: course/05-interrupts/
(chapter 4 plus idt.rs, interrupts.rs, a kernel command line and two more checks in make test)
What changed: diff -ru course/04-gdt course/05-interrupts (in the repository) shows every line this chapter adds.
Background: when the CPU interrupts itself
So far, any mistake in our kernel ended the same way: the machine reset, and QEMU (started with -no-reboot)
closed. That is because the CPU has a fixed reaction to errors – it raises an exception – and we never told it
what to do then.
An exception is the CPU stopping the current instruction and calling a function instead: division by zero (vector 0), an unknown instruction (6), access to memory no page table maps – a page fault (14), a broken segment or privilege rule – a general protection fault (13). Each kind has a number, the vector. Vectors 0–31 belong to the CPU; 32–255 are free for hardware interrupts (keyboard, timer – the next chapters) and software.
The IDT says, for each vector, where that function is. Before calling it the CPU pushes five values onto the
stack – where the interrupted code was (RIP, CS), its flags (RFLAGS), its stack (RSP, SS) – and for some exceptions
an error code on top. A handler that returns must pop all of it with iretq instead of ret.
If the CPU fails while calling a handler – the gate is missing, or pushing the five values faults – it raises a double fault (vector 8). If calling the double fault handler fails too, there is nothing left to try: a triple fault, and the CPU resets. That is what we have seen until now.
Step 1: a gate
Each IDT entry – a gate – is 16 bytes. Like the TSS descriptor of chapter 4, it scatters the handler's address over three fields:
#![allow(unused)]
fn main() {
pub struct Entry {
    offset_low: u16,
    selector: u16,
    /// Bits 0..3: which IST stack to switch to, 1..=7 (0 = stay on the current stack).
    ist: u8,
    /// P | DPL | 0 | type; 0xE = interrupt gate: the CPU turns interrupts off while the handler runs.
    type_attr: u8,
    offset_mid: u16,
    offset_high: u32,
    _reserved: u32,
}
}
selector is the code segment the handler runs in – our 0x08 from chapter 4. Filling a gate means cutting the
address into pieces and marking it present:
#![allow(unused)]
fn main() {
    fn set_address(&mut self, address: u64) -> &mut Entry {
        self.offset_low = address as u16;
        self.offset_mid = (address >> 16) as u16;
        self.offset_high = (address >> 32) as u32;
        self.selector = KERNEL_CODE_SELECTOR;
        self.type_attr = PRESENT_INTERRUPT_GATE;
        self
    }
}
The table is 256 of them, starting out all missing (all zeros). It is loaded with lidt – the twin of lgdt,
with the same 10-byte pointer of size and address.
Step 2: a function the CPU can call
A handler is not a normal function. The CPU jumps into it in the middle of other code, so it must save every
register it touches, find the pushed values on the stack and end with iretq. Rust's nightly compiler can generate
all of that: the x86-interrupt calling convention (feature abi_x86_interrupt in main.rs). The stack frame
becomes the first parameter:
#![allow(unused)]
fn main() {
pub struct InterruptStackFrame {
    /// Where the interrupted code was - for most faults the instruction that failed, so returning retries it.
    pub rip: u64,
    pub cs: u64,
    pub rflags: u64,
    pub rsp: u64,
    pub ss: u64,
}
}
and the error code, for the exceptions that have one, the second. There are three shapes of handler, and the IDT only accepts the right one for each kind:
#![allow(unused)]
fn main() {
pub type Handler = extern "x86-interrupt" fn(InterruptStackFrame);
pub type HandlerWithErrorCode = extern "x86-interrupt" fn(InterruptStackFrame, u64);
pub type DivergingHandlerWithErrorCode = extern "x86-interrupt" fn(InterruptStackFrame, u64) -> !;
}
Step 3: the handlers
The breakpoint is the friendly exception: int3 raises it on purpose (debuggers place it in code). Our handler
counts it, prints, and returns – the CPU continues after the int3, because for a breakpoint the pushed RIP already
points to the next instruction:
#![allow(unused)]
fn main() {
extern "x86-interrupt" fn breakpoint(frame: InterruptStackFrame) {
    BREAKPOINT_COUNT.fetch_add(1, Ordering::Relaxed);
    serial_println!("EXCEPTION: BREAKPOINT at {:#x}", frame.rip);
}
}
Every other exception in our kernel is a bug, so the handlers report and panic. The page fault has the most to say: control register CR2 holds the address the code tried to use, and the error code tells why it failed – bit 0 "the page exists but forbids this", bit 1 "it was a write", bit 2 "user mode", bit 4 "fetching an instruction":
#![allow(unused)]
fn main() {
extern "x86-interrupt" fn page_fault(frame: InterruptStackFrame, error_code: u64) {
    panic!(
        "EXCEPTION: PAGE FAULT at address {:#018x}\n  cause: {}\n{:?}",
        read_cr2(),
        PageFaultError(error_code),
        frame
    );
}
}
(PageFaultError turns those bits into words.) The handlers print to the serial port only, not with println!:
an exception can hit code that holds the console's lock, and a handler waiting for that lock would wait forever.
Step 4: the double fault, on its own stack
Now the reason for chapter 4's TSS. Imagine the stack pointer points to memory that is not there – a stack overflow
does exactly that. The next push page-faults. To call the page fault handler the CPU must push the five values –
onto the same broken stack – and faults again: a double fault. If its handler used that stack too, a third failure
would reset the machine.
So the double fault gate gets an IST index: before pushing anything, the CPU loads RSP from the TSS's
interrupt_stacks[0] – the 20 KiB stack we prepared:
#![allow(unused)]
fn main() {
        // the one handler that must not use the current stack: it may be what broke
        idt.set_diverging_with_error_code(DOUBLE_FAULT, double_fault)
            .set_ist(DOUBLE_FAULT_IST);
}
The handler is diverging (-> !): a double fault cannot be returned from, because the CPU does not say how far
the first exception got. Ours checks its own stack pointer – is it really on the double fault stack? – and panics
with what it knows:
#![allow(unused)]
fn main() {
extern "x86-interrupt" fn double_fault(frame: InterruptStackFrame, error_code: u64) -> ! {
    let rsp: u64;
    unsafe { asm!("mov {}, rsp", out(reg) rsp, options(nomem, nostack, preserves_flags)) };
    let on_ist = if gdt::on_double_fault_stack(rsp) { "yes" } else { "no" };
    serial_println!("running on the double fault stack: {} (rsp={:#x})", on_ist, rsp);
}
interrupts::init builds the table once (spin::Once, like the GDT) with six handlers – vectors 0, 3, 6, 8, 13 and
14 – and loads it. Both entry points in main.rs call it right after gdt::init(); it needs our code segment and
our TSS:
#![allow(unused)]
fn main() {
    console::init();
    gdt::init();
    interrupts::init();
    println!("Hello from YAK!");
}
Step 5: crashing on purpose
A handler for a crash is only proven by a crash. The normal kmain now ends with a breakpoint – it must come back –
and then, if asked, a real fault:
#![allow(unused)]
fn main() {
    unsafe { core::arch::asm!("int3") };
    println!("Back from the breakpoint handler - the kernel carries on.");
    match requested_fault() {
        Some("page") => interrupts::provoke_page_fault(),
        Some("stack") => interrupts::provoke_double_fault(),
}
Who asks? The kernel command line: a cmdline: line in limine.conf, which Limine hands to the kernel when we
ask with an ExecutableCmdlineRequest (one more request next to the framebuffer). run-qemu.sh adds that line when
the variable KERNEL_CMDLINE is set. fault=page writes to address 0xdeadbeef, which no page table maps;
fault=stack points the stack there and pushes:
#![allow(unused)]
fn main() {
pub fn provoke_double_fault() -> ! {
    unsafe { asm!("mov rsp, {}", "push rax", in(reg) UNMAPPED & !0xF, options(noreturn)) }
}
}
The tests
make test now runs 22 tests in the kernel; six are new:
a_gate_scatters_the_handler_address– the bit puzzle of step 1 with a known address;idtr_points_to_our_table–sidtreturns our table, 256 × 16 bytes;breakpoints_return– twoint3, the counter goes up by two, and the test goes on;the_double_fault_gate_switches_to_ist1– present, IST 1, and pointing at our handler;only_the_exceptions_we_handle_are_present– all 256 gates, so a forgotten or extra one shows up;the_page_fault_error_code_in_words– error code0b10reads "page not present, write, kernel mode".
Then it boots the normal kernel three times: without a command line (expected.txt, which includes the breakpoint
and the line after it), with fault=page (expected-page-fault.txt) and with fault=stack
(expected-double-fault.txt, which demands "running on the double fault stack: yes"). Remove .set_ist(…) and
the last check fails within a second: QEMU ends by itself – a triple fault – and run-qemu.sh says so. Without
interrupts::init() in the test kmain, idtr_points_to_our_table fails.
Run it
cd course/05-interrupts
make run
GDT loaded: code segment 0x8, TSS 0x18, double fault stack top 0xffffffff8001a150
IDT loaded: exceptions 0, 3, 6, 8 (on IST1), 13, 14
EXCEPTION: BREAKPOINT at 0xffffffff800097ae
Back from the breakpoint handler - the kernel carries on.
(after the lines of chapter 4; the addresses depend on your build.) Then crash it:
KERNEL_CMDLINE=fault=page make run
KERNEL PANIC: panicked at src/interrupts.rs:76:5:
EXCEPTION: PAGE FAULT at address 0x00000000deadbeef
  cause: page not present, write, kernel mode
rip=0xffffffff800055be cs=0x8 rflags=0x10086 rsp=0xffff800007f8edc0 ss=0x10
KERNEL_CMDLINE=fault=stack make run
running on the double fault stack: yes (rsp=0xffffffff80019fd0)
KERNEL PANIC: panicked at src/interrupts.rs:90:5:
EXCEPTION: DOUBLE FAULT (code 0x0), last page fault at 0xdeadbed8
rip=0xffffffff80005629 cs=0x8 rflags=0x2 rsp=0x00000000deadbee0 ss=0x10
Read the double fault's frame: RSP was 0xdeadbee0 – the broken stack – and the page fault was at 0xdeadbed8, the
8 bytes the push wanted to write. The handler itself ran 20 KiB higher, on its own stack.
What can go wrong
- A double fault still resets the machine: the gate has no IST index, or the TSS holds the bottom of the
stack instead of the top (chapter 4).
-d int,cpu_reset -D qemu.logon the QEMU command line shows the chain:v=0e e=0002(page fault on a write),v=08(double fault), thenTriple faultand a CPU reset. - A general protection fault with error code
0x102: bit 1 says "an IDT entry",0x102 >> 3 = 0x20says which – vector 32, which has no gate. The reference kernel hit exactly this when a test loaded its own IDT without the timer's vector while interrupts were on (bug #10). In this chapter interrupts stay off; the next chapter turns them on. - Garbage in the frame, then a crash on return: a handler declared without the error code for an exception
that pushes one (8, 10–14, 17, 21, 29, 30), or the other way round. Every field is read one place off – RIP shows the error
code – and
iretqjumps to it. The three handler types inidt.rsexist so the compiler catches the obvious case. - The kernel hangs inside a handler: the handler printed with
println!while the interrupted code held the console's lock. Use the serial port in handlers. error[E0658]: the extern "x86-interrupt" ABI is experimental and subject to change: the#![feature(abi_x86_interrupt)]line inmain.rsis missing, or you are not on the pinned nightly compiler (rust-toolchain.toml).
Experiments
- Remove
.set_ist(DOUBLE_FAULT_IST)and run withfault=stack– once plain, once with-d int,cpu_reset -D qemu.logadded to the QEMU command inrun-qemu.sh. Which vectors does the log show, in which order? - Divide by zero:
asm!("xor edx, edx", "xor eax, eax", "div eax"). Then remove the divide error gate and try again – which exception do you get now, with which error code? - Write to
0xdeadbeefonce more, but read first (read_volatile). Which bit of the error code changes? Then try executing it:asm!("call {}", in(reg) 0xdeadbeefu64).
6 – Hardware interrupts and the timer
Goal: the first interrupt that does not come from our own code – a timer, 100 times per second – and on top of
it a clock and sleep_ms.
You end up with: sleep_ms(1000) waits a second while the CPU sleeps in hlt; make test proves the ticks
arrive and that a sleep never ends early.
Code: course/06-timer/ (chapter 5
plus port.rs, pic.rs, pit.rs, time.rs, three IRQ handlers and a CPU without local APIC in run-qemu.sh)
What changed: diff -ru course/05-interrupts course/06-timer (in the repository) shows every line this chapter adds.
Background: IRQs and the PIC
In chapter 5 the CPU interrupted itself. Devices need the same thing: the keyboard has a key, the disk has data, the timer's time is up – and the CPU should not have to ask them every microsecond. So a device raises an interrupt request (IRQ) line, and the CPU calls a handler through the IDT, exactly as for an exception.
Between the devices and the CPU sits an interrupt controller. The classic one, still emulated by every PC and by QEMU, is the 8259 PIC: two chips of 8 lines each, IRQ 0–15, the second chained to line 2 of the first. Line 0 is the timer, line 1 the keyboard (next chapter). The PIC turns a line into a vector – its offset plus the line number – and it has two habits we must handle:
- Its offset starts at 8. IRQ 0, the timer, would arrive as vector 8 – the double fault. That was a design mistake of the original PC; every x86 kernel starts by moving the PIC elsewhere. We move it to 32–47.
- It waits for an answer. After delivering an IRQ the PIC holds back further IRQs of that priority until the handler sends an end of interrupt (EOI).
The timer itself is the PIT, a counter running at 1.193182 MHz that counts down from a number we choose and raises IRQ 0 each time it reaches zero.
Step 1: I/O ports, shared
PIC and PIT live in the I/O port address space, like the serial port of chapter 1. The two little functions
inb/outb that were private to serial.rs move into port.rs, and serial.rs imports them:
#![allow(unused)]
fn main() {
use crate::port::{inb, outb};
}
Step 2: moving the PIC
The PIC is programmed with four initialization command words in a fixed order. The second one is the offset:
#![allow(unused)]
fn main() {
    let commands = [
        (MASTER_COMMAND, 0x11),       // ICW1 master: start initialization, ICW4 follows
        (SLAVE_COMMAND, 0x11),        // ICW1 slave
        (MASTER_DATA, MASTER_OFFSET), // ICW2: the vector of IRQ 0
        (SLAVE_DATA, SLAVE_OFFSET),   //       the vector of IRQ 8
        (MASTER_DATA, 1 << 2),        // ICW3 master: a slave hangs on line 2
        (SLAVE_DATA, 2),              // ICW3 slave: you hang on line 2
        (MASTER_DATA, 0x01),          // ICW4: 8086 mode
        (SLAVE_DATA, 0x01),
    ];
}
After that every line is masked (a set bit in the mask register blocks it), and unmask opens single lines. The
answer to an IRQ is one byte, 0x20, to the command port – to both chips if the IRQ came through the second:
#![allow(unused)]
fn main() {
pub fn end_of_interrupt(irq: u8) {
    unsafe {
        if irq >= 8 {
            outb(SLAVE_COMMAND, END_OF_INTERRUPT);
        }
        outb(MASTER_COMMAND, END_OF_INTERRUPT);
    }
}
}
Step 3: a CPU without local APIC
Every x86 core since the late 1990s has a newer interrupt controller of its own, the local APIC, and the PIC's signal enters it on a pin called LINT0. Limine leaves that pin masked. With an APIC, our PIC could ring forever – nothing would arrive.
The APIC can be switched off (bit 11 of the register IA32_APIC_BASE), and the reference kernel did exactly that
in its milestone M6 (bug #2). For the course it is not enough: QEMU 8.2 – the version of Ubuntu 24.04
– still routes the PIC through the masked pin when the APIC is off and drops every interrupt; QEMU 10.2 delivers
them (bug #25).
Unmasking the pin needs the APIC's registers, and those are memory-mapped at an address Limine does not map – we
cannot reach them before we have our own page tables (part II).
So from this chapter on, run-qemu.sh starts QEMU with a CPU without local APIC:
# -cpu qemu64,-apic: a CPU without local APIC, so the PIC's interrupts go straight to the CPU (chapter 6)
QEMU=(qemu-system-x86_64 -M q35 -cpu qemu64,-apic -m 128M -cdrom "$ISO" -boot d -no-reboot
The PIC is then wired straight to the CPU's interrupt pin, as on a PC of 1990. The APIC comes back in part IV, where the reference kernel uses it for the timer and for several CPUs. A test checks the CPU model really is the one we asked for – CPUID leaf 1, EDX bit 9 says whether there is an APIC:
#![allow(unused)]
fn main() {
    edx & (1 << 9) != 0
}
Step 4: the timer
For 100 interrupts per second the PIT counts down from 1193182 / 100 = 11931. One command byte selects channel 0 and the mode, then the number goes in, low byte first:
#![allow(unused)]
fn main() {
pub fn init(hz: u32) {
    let divisor = divisor(hz);
    unsafe {
        // channel 0, low byte then high byte, mode 3 (square wave: reload and repeat), binary counting
        outb(COMMAND, 0b0011_0110);
        outb(CHANNEL0, divisor as u8);
        outb(CHANNEL0, (divisor >> 8) as u8);
    }
}
}
The handler on vector 32 counts the tick and answers the PIC:
#![allow(unused)]
fn main() {
extern "x86-interrupt" fn timer(_frame: InterruptStackFrame) {
    time::tick();
    // without it, the PIC would never send the next tick
    pic::end_of_interrupt(TIMER_IRQ);
}
}
The counter is an AtomicU64: the handler writes it in the middle of whatever the kernel is doing, and the rest of
the kernel reads it – an atomic guarantees nobody ever sees half a value. Two more small handlers sit on vectors 39
and 47 for spurious IRQs – the PIC reports line 7 or 15 when a signal vanished before it could deliver it, and
then it must not get an EOI (interrupts.rs explains the rule).
Everything is started in one place, in an order that matters – the gates first (chapter 5's interrupts::init),
then the hardware, and only at the end sti, which lets interrupts in:
#![allow(unused)]
fn main() {
pub fn start_timer() {
    pic::init();
    pit::init(time::TICKS_PER_SECOND);
    pic::unmask(TIMER_IRQ);
    unsafe { asm!("sti", options(nomem, nostack)) };
}
}
Both entry points in main.rs call interrupts::start_timer() after interrupts::init(): the normal kmain
after the breakpoint test, the test kmain before test_main().
Step 5: time and sleep
With a tick every 10 ms, uptime is ticks × 10. Sleeping means: compute the tick to wake at, then hlt until it
has come – hlt stops the CPU until the next interrupt, so the kernel waits without doing any work:
#![allow(unused)]
fn main() {
pub fn ticks_for(ms: u64) -> u64 {
    ms.div_ceil(MS_PER_TICK) + 1
}
}
Why the + 1? The tick counter says which tick it is, not how far into it we are. A sleep that starts just
before a tick ends would count that tick fully and wake up almost 10 ms early. The reference kernel had exactly
this bug (bug #18); with one tick more a sleep lasts at least ms and at most ms + 10.
#![allow(unused)]
fn main() {
pub fn sleep_ms(ms: u64) {
    let deadline = ticks() + ticks_for(ms);
    while ticks() < deadline {
        unsafe { core::arch::asm!("hlt", options(nomem, nostack)) };
    }
}
}
kmain now starts the timer and sleeps one second:
#![allow(unused)]
fn main() {
    let before = time::uptime_ms();
    time::sleep_ms(1000);
    let slept = time::uptime_ms() - before;
    let enough = if slept >= 1000 { "yes" } else { "NO" };
}
The tests
make test now runs 29 tests in the kernel; seven are new:
the_cpu_has_no_local_apic– CPUID says there is none, asrun-qemu.shasked;only_the_timer_is_let_through– the masks are0b1111_1110and0b1111_1111;irqs_start_after_the_exceptions– IRQ 0 is vector 32, IRQ 15 vector 47;the_divisor_for_100_hz– 11931, and the slowest the 16-bit counter can do;ticks_advance_while_the_cpu_halts– five ticks arrive while the test sits inhlt;a_deadline_rounds_up_and_adds_one–ticks_forfor 0, 1, 10, 11 and 1000 ms;sleep_never_ends_early– five sleeps of 30 ms, each at least 4 ticks.
(only_the_vectors_we_handle_are_present from chapter 5 now expects the gates 32, 39 and 47 too.) Then the three
boot checks of chapter 5 run again; the normal one now needs "at least 1000: yes". The tests measure only lower
bounds for time: how late an emulated machine wakes up depends on the host, and the reference kernel learned that
an upper bound makes a test flaky (bug #24).
Remove -apic from run-qemu.sh and the kernel stops after the "Timer" line – the tick never comes and
sleep_ms waits forever; without the EOI exactly one tick arrives and the tick test runs into the time limit.
Run it
cd course/06-timer
make run
After the lines of chapter 5, and a second of nothing:
Timer: IRQ 0 on vector 32, 100 Hz
sleep_ms(1000) took 1010 ms (at least 1000: yes), the CPU waited in hlt
1010, not 1000: the one extra tick from step 5.
What can go wrong
-
The kernel hangs in the first
sleep_ms: no tick arrives. In order of likelihood: interrupts are off (nosti), the line is masked, the CPU has a local APIC (-cpu … ,-apicmissing – the APIC test says so first), or the PIT was not programmed. The QEMU monitor shows the PIC's view:info piclistsirr(requested),imr(masked) andirq_base(the offset). -
Exactly one tick, then silence: the handler does not send the EOI.
-
A "double fault" with a nonsense frame as soon as interrupts are on: the PIC was not moved, and IRQ 0 arrived on vector 8. A real double fault pushes an error code, an IRQ does not – so the handler reads everything one place off. Removing
pic::init()fromstart_timergives exactly this (with BIOS):EXCEPTION: DOUBLE FAULT (code 0xffffffff800056c6), last page fault at 0x0 rip=0x0000000000000008 cs=0x282 rflags=0xffff800007f8ed08 rsp=0x0000000000000010 ss=0x0The "error code" is the interrupted RIP, "rip" is the code segment
0x8, "cs" is RFLAGS, and so on. -
A general protection fault with error code
0x102right aftersti: bit 1 says "an IDT entry",0x102 >> 3 = 32says which – the timer's line is open but its gate is missing (remove theidt.setforTIMER_IRQand you get exactly this). The same holds for any IRQ: unmask only the lines you have a handler for. -
The kernel hangs in
println!from a handler: the interrupted code held the console's lock (chapter 5). The timer handler prints nothing for this reason.
Experiments
- Set
TICKS_PER_SECONDto 1000. Doessleep_ms(1000)still take about a second? What doesticks_forcompute now – and isMS_PER_TICKstill right? - Remove the
+ 1inticks_for. Which test fails – always, or only sometimes? Why? - Count how often the loop in
sleep_msruns duringsleep_ms(1000). What does that say abouthlt? - Replace
hltinsleep_msbycore::hint::spin_loop()and watch your host's CPU load whilemake runsleeps.
7 – The keyboard
Goal: keys typed in the QEMU window appear on the screen. The keyboard raises IRQ 1, a handler stores the byte,
and the kernel decodes it outside the handler.
You end up with: a kernel that echoes what you type, with Shift, Caps Lock, Enter and Backspace. make test
types "Hi YAK!" on the emulated keyboard and checks that it arrives. This ends part I.
Code: course/07-keyboard/ (chapter
6 plus ringbuf.rs, scancode.rs, keyboard.rs, one more IRQ handler, Backspace in the console, and typing in
run-qemu.sh)
What changed: diff -ru course/06-timer course/07-keyboard (in the repository) shows every line this chapter adds.
Background: scancodes
Behind the keyboard sits the PS/2 controller, an old chip that QEMU emulates like the PIC. On every key event
it puts one byte at I/O port 0x60 and raises IRQ 1. The byte is a scancode. The firmware sets the controller
up to translate everything into set 1, the oldest code set:
- Press and release: pressing a key sends its code (the make). Releasing it sends the same code with bit 7 set
(the break). The H key sends
0x23and then0xA3. Holding a key repeats the make. - A code names a position, not a letter.
0x15is the key right of T. That key is a Y on a US keyboard and a Z on a German one. What a position means is the layout, and the kernel has to know it. Ours is US. QEMU'ssendkeynames keys by their US position too. - Shift has no letters of its own. Shift, Ctrl and Caps Lock send codes like any other key. Whether H gives
horHis something the kernel works out, by remembering which modifier keys are down. - Prefixes. Keys that came after the first PC keyboards (the arrows, right Ctrl, …) send
0xE0and then one byte. Without the prefix, the up arrow (E0 48) would look like the 8 of the number pad.
Step 1: a ring buffer
The handler must be quick, so it only stores the byte; the rest of the kernel takes it out later. In between sits a ring buffer: a fixed array with a read position and a length. A fixed size is the only kind we can have, because there is no heap yet (that comes in part II). When the buffer is full, a new byte is dropped. An interrupt handler cannot wait for somebody to make room.
#![allow(unused)]
fn main() {
    /// Adds `byte` at the end; `false` if the buffer is full - then the byte is dropped.
    pub fn push(&mut self, byte: u8) -> bool {
        if self.len == N {
            return false;
        }
        self.bytes[(self.head + self.len) % N] = byte;
        self.len += 1;
        true
    }
}
The % N is the "ring": past the last place, the buffer goes on at the first one.
Step 2: the handler
The handler on vector 33 reads the byte and answers the PIC, exactly like the timer:
#![allow(unused)]
fn main() {
pub fn handle_interrupt() {
    let byte = unsafe { inb(DATA_PORT) };
    SCANCODES.lock().push(byte);
}
}
#![allow(unused)]
fn main() {
extern "x86-interrupt" fn keyboard(_frame: InterruptStackFrame) {
    keyboard::handle_interrupt();
    pic::end_of_interrupt(KEYBOARD_IRQ);
}
}
The inb is not optional. Until the byte is read, the controller keeps it and sends nothing new.
The same holds at the start. A byte that waits from before, such as a key pressed during boot, has to go too
before IRQ 1 is unmasked. Otherwise nobody reads it and the keyboard stays silent. keyboard::init empties the
controller, and interrupts::start_keyboard then opens the line:
#![allow(unused)]
fn main() {
pub fn start_keyboard() {
    keyboard::init();
    pic::unmask(KEYBOARD_IRQ);
}
}
In interrupts::init the gate joins the others:
idt.set(pic::vector(KEYBOARD_IRQ), keyboard);.
Step 3: from bytes to keys
scancode.rs has no hardware in it at all. A Decoder takes one byte at a time and sometimes gives a key back. It
remembers three things: both Shift keys and Caps Lock. A fourth flag says whether the last byte was a prefix, in
which case the next byte is skipped:
#![allow(unused)]
fn main() {
        let pressed = byte & RELEASED == 0;
        match byte & !RELEASED {
            LEFT_SHIFT => self.left_shift = pressed,
            RIGHT_SHIFT => self.right_shift = pressed,
            CAPS_LOCK if pressed => self.caps_lock = !self.caps_lock,
            _ if !pressed => {}
            ENTER => return Some(Key::Enter),
            BACKSPACE => return Some(Key::Backspace),
            code => return self.character(code).map(Key::Char),
        }
}
The layout is a table. The codes of one keyboard row follow each other (Q is 0x10, W 0x11, …), so the table
holds each row as a string, once without and once with Shift. It looks like the keyboard itself:
#![allow(unused)]
fn main() {
const ROWS: [(u8, &str, &str); 5] = [
    (0x02, "1234567890-=", "!@#$%^&*()_+"),
    (0x10, "qwertyuiop[]", "QWERTYUIOP{}"),
    (0x1E, "asdfghjkl;'`", "ASDFGHJKL:\"~"),
    (0x2B, "\\zxcvbnm,./", "|ZXCVBNM<>?"),
    (0x39, " ", " "),
];
}
Caps Lock has one subtlety. It makes letters capitals and leaves digits alone, so Caps Lock and 1 still gives 1.
Caps Lock together with Shift gives small letters again:
#![allow(unused)]
fn main() {
        let upper = if normal.as_bytes()[i].is_ascii_alphabetic() {
            shift != self.caps_lock
        } else {
            shift
        };
}
Step 4: waiting for a key
read_key takes bytes out of the buffer until one gives a key. When the buffer is empty, it sleeps in hlt like
sleep_ms. Two details make this harder than it looks:
#![allow(unused)]
fn main() {
        unsafe { asm!("cli", options(nomem, nostack)) };
        let byte = SCANCODES.lock().pop(); // a statement of its own: the lock is free again before `hlt`
        match byte {
            // `sti` lets interrupts in only after the next instruction - nothing can slip in before `hlt`
            None => unsafe { asm!("sti", "hlt", options(nomem, nostack)) },
}
- The lock. The handler and
read_keyshare the buffer's spin lock. Suppose the handler interruptsread_keywhileread_keyholds the lock. The handler then waits for a lock that will never be released, because its holder cannot run until the handler is done. Soread_keytakes the lock only with interrupts off (cli). It also lets go of the lock beforehlt. A temporary in amatchlives until the end of thematch, somatch SCANCODES.lock().pop() { … }would still hold the lock while the CPU sleeps. That is why thepopis a statement of its own. - The lost wake-up. "Buffer empty? Then
hlt" has a gap between the check and thehlt. A key that arrives inside the gap lands in the buffer, but the CPU goes to sleep after it, and only the next interrupt wakes it. Our timer ticks every 10 ms, so here the gap costs at most 10 ms. A kernel without a steady tick would sit on the key until the next one. The fix costs nothing: interrupts stay off from the check to thehlt.stienables them only after the following instruction, sosti; hltleaves no gap.
Step 5: echo
kmain starts the keyboard after the timer and echoes what comes in. The test kmain calls
interrupts::start_keyboard() too, after start_timer():
#![allow(unused)]
fn main() {
    loop {
        match keyboard::read_key() {
            Key::Char(c) => print!("{}", c),
            Key::Enter => println!(),
            Key::Backspace => print!("\x08 \x08"),
        }
    }
}
"\x08 \x08" is how terminals erase: back one cell, a space over the character, back again. The serial terminal
already understands it. The console learns \x08 (one cell back) in put_char:
#![allow(unused)]
fn main() {
            '\x08' => self.column = self.column.saturating_sub(1),
}
kmain no longer ends in halt(); it waits for keys forever.
Step 6: typing in the check
A test has nobody to press keys, so run-qemu.sh types itself. QEMU has a monitor, a command line for the
emulator, and its command sendkey shift-h presses Shift+H on the emulated keyboard. In check mode the monitor
reads its commands from a FIFO, a named pipe in build/. Once the serial output contains the line in
KEYS_AFTER, the script writes one sendkey per key in KEYS:
    type_keys() {
        for key in $KEYS; do
            echo "sendkey $key" >&3
            sleep 0.2 # sendkey holds a key down for 100 ms
        done
    }
The Makefile names what to type: "Hi YAK!" with Shift and Caps Lock, then Enter.
TYPED := shift-h i spc caps_lock y a k caps_lock shift-1 ret
The kernel has to print that line back, so Hi YAK! is the last line of expected.txt. Before
type something appears, the keyboard is not ready yet; that is what KEYS_AFTER waits for.
The tests
make test now runs 36 tests in the kernel. Seven are new:
first_in_first_out_and_full_is_full: the ring buffer keeps the order, drops when full, and wraps around;a_key_types_when_pressed_not_when_released: letters, digits, space, Enter, Backspace, and nothing on release;shift_counts_while_it_is_held:Hand!while Shift is down,hagain after its break, and the right Shift works too;caps_lock_toggles_letters_only:Abut1; Caps Lock with Shift givesa; a second Caps Lock turns it off;prefixed_keys_are_skipped: a "fake shift" (E0 2A, sent with some keys) makes no capitals, the up arrow gives nothing, and neither do the six bytes of Pause;bytes_in_the_buffer_become_keys: bytes put into the real buffer come out ofread_keyasH,i, Enter;backspace_space_backspace_erases:"ab\x08 \x08c"leavesacon the screen.
Two older tests change. The PIC masks are now 0b1111_1100 (only_the_timer_and_the_keyboard_are_let_through),
and the IDT test expects gate 33 too. The boot checks follow: the normal one types and waits for Hi YAK!, and the
two fault checks stay as in chapter 5.
Run it
cd course/07-keyboard
make run
After the timer line, the kernel waits:
Keyboard: IRQ 1 on vector 33 - type something (US layout)
Click into the QEMU window and type. The characters appear on the screen and in the terminal. On a German keyboard
Y and Z are swapped, and ü gives [. QEMU passes on the key's position, and our table reads positions the US way.
Experiment 1 fixes that.
What can go wrong
- Nothing appears when you type: the QEMU window does not have the keyboard (click into it), or one of the things the timer chapter lists: IRQ 1 masked, or interrupts off.
- The first key arrives, then nothing: either the handler does not read port
0x60, so the controller keeps the byte and sends no new one, or it does not send the EOI, so the PIC holds back the next IRQ 1. Both look the same. Without theinbthe check shows oneh; without the EOI, typingh ishows oneh. The check's own first key is Shift, so there it shows nothing at all. - Everything stops at the first key, the timer too: the buffer's lock was held when the interrupt came. A
match SCANCODES.lock().pop()inread_keydoes exactly this, because the lock is still taken duringhlt. The handler then spins for the lock with interrupts off, forever. - Capitals after Print Screen or Home: some keys send a "fake shift" (
E0 2A). Without the prefix rule the2Awould count as the left Shift.prefixed_keys_are_skippedfails if the rule is missing.
Experiments
- Write a German (QWERTZ) layout:
zandyswap, andü,ö,ä,ßcome in. Those are no longer one byte each, soas_bytes()[i]will not do. What doeschars().nth(i)cost instead? - Print each scancode in hex instead of decoding it (
print!("{:02x} ", byte)inread_key). Press and release a key, hold a key, press an arrow, press Pause. - Make the ring buffer 4 bytes long and type
KEYS="a b c d e f g h"into a kernel that sleeps a second before everyread_key. Which keys arrive? - Remember Ctrl as well (
0x1D, andE0 1Dfor the right one, which the prefix rule skips for now) and make Ctrl+L clear the screen.
Part I ends here. The kernel boots, tests itself, writes to the screen, survives its own crashes, keeps time and reads the keyboard. All of it runs without a single allocation. Part II gives it memory: a frame allocator, its own page tables, and a heap.
8 – Physical memory
Goal: know which RAM the kernel may use, and hand it out in 4 KiB pieces – the first thing part II builds
everything else on.
You end up with: the kernel prints Limine's memory map, builds a frame allocator on it, takes a frame, writes to
it through the higher-half direct map and gives it back; make test takes every frame there is and checks each one.
Code: course/08-frames/ (chapter 7
plus mem.rs, pmm.rs and two Limine requests)
What changed: diff -ru course/07-keyboard course/08-frames (in the repository) shows every line this chapter adds.
Background: physical and virtual
Every address our code has used so far was virtual: the kernel at 0xffffffff80000000, the stack at
0xffff8000…. Paging – which Limine switched on before our first instruction – translates each one into a
physical address, a place in the actual RAM chips. Both sides are cut into 4 KiB pieces: a page of virtual
memory is backed by a frame of physical memory. Chapter 9 builds that translation ourselves; this chapter manages
the frames.
Which physical memory is RAM at all, and which of it is free? Only the firmware knows, and Limine passes it on as the memory map: a list of ranges, each with a type. On QEMU with 128 MiB it looks like this (the kernel of this chapter prints it; shortened):
Memory map (20 entries):
  0x0000001000 - 0x0000061000      384 KiB  Limine (page tables, our stack, the answers)
  0x0000061000 - 0x000009f000      248 KiB  usable
  0x000009fc00 - 0x00000a0000        1 KiB  reserved
  ...
  0x0000100000 - 0x0007dea000   127912 KiB  usable
  0x0007dea000 - 0x0007dec000        8 KiB  Limine (page tables, our stack, the answers)
  0x0007dec000 - 0x0007e0e000      136 KiB  our kernel
  ...
  0x00fd000000 - 0x00fd3e8000     4000 KiB  framebuffer
Only usable ranges are ours. "Limine" ranges (bootloader reclaimable) are free later, but right now they hold the page tables the CPU is using, the stack we are running on, and Limine's answers to our requests – this memory map included. The reference kernel takes them back once it has its own tables and stack; the course leaves them alone.
To reach a physical address, the kernel needs a virtual one that maps to it. Limine maps all of physical memory once
more at a fixed offset in the higher half – the higher-half direct map (HHDM): physical p is at virtual
p + offset.
Step 1: two more requests
The memory map and the HHDM offset are answers to requests, like the framebuffer of chapter 3:
#![allow(unused)]
fn main() {
/// Where Limine mapped all of physical memory (the higher-half direct map, see mem.rs).
#[used]
#[unsafe(link_section = ".limine_requests")]
static HHDM: HhdmRequest = HhdmRequest::new();
}
MEMMAP: MemmapRequest follows the same pattern.
Step 2: physical addresses get a type
A physical address is a number, and a number can be turned into a pointer by mistake – which writes to whatever virtual address it happens to be. So it gets a type of its own, and the only way to a pointer goes through the HHDM:
#![allow(unused)]
fn main() {
    /// The virtual address at which this physical address is visible, through the HHDM.
    pub fn to_virt(self) -> u64 {
        self.0 + hhdm_offset()
    }
}
mem::init reads the offset from Limine, then builds the frame allocator. The normal kmain calls it after the
one-second sleep, the test kmain after interrupts::start_keyboard().
Step 3: a bitmap of frames
128 MiB are 32768 frames. The simplest bookkeeping that works is one bit per frame: 1 = used, 0 = free – 4 KiB for the whole machine. A new bitmap starts with every frame used and frees those that lie wholly in a usable range; a range that starts in the middle of a frame does not own that frame:
#![allow(unused)]
fn main() {
            // a frame half inside the region is not ours: round the start up and the end down
            let start = align_up(region.base, PAGE_SIZE) / PAGE_SIZE;
            let end = align_down(region.base + region.length, PAGE_SIZE) / PAGE_SIZE;
}
Frame 0 always stays used: a physical address of 0 is too easy to confuse with "nothing".
Allocating means finding a 0 bit. Instead of testing 32768 bits one by one, alloc looks at 64 at once: a u64
that is not all ones has a free frame, and trailing_ones says which:
#![allow(unused)]
fn main() {
            let frame = word * 64 + self.bits[word].trailing_ones() as usize;
}
next_word remembers where the full words end, so the next search does not start at the beginning again; free
moves it back if a lower frame becomes free. free also refuses nonsense – an address in the middle of a frame,
frame 0, a frame beyond the end, a frame that is free already. In the kernel each of those is a bug, so
pmm::free_frame panics on them.
FrameBitmap knows nothing about Limine: it gets a slice for its bits and a list of regions. That makes it testable
with a fake machine of 256 frames.
Step 4: a home for the bitmap
The bitmap needs 4 KiB of memory before there is anything that hands out memory. So it takes the start of the first usable range it fits into, through the HHDM – and then marks its own frames as used:
#![allow(unused)]
fn main() {
    let mut frames = FrameBitmap::new(bits, frame_count, usable);
    let usable_frames = frames.free_frames();
    frames.reserve(bitmap.0, bitmap_bytes); // or the first frames handed out would overwrite the bitmap itself
}
The global allocator is a spin::Mutex like the keyboard buffer. Unlike that buffer, no interrupt handler touches
it, so taking its lock with interrupts on is fine – the rule from chapter 7 is about locks a handler shares.
Step 5: using a frame
kmain prints the memory map, takes a zeroed frame, writes to it and reads it back:
#![allow(unused)]
fn main() {
    let frame = pmm::alloc_frame_zeroed().expect("a free frame");
    let pointer = frame.as_mut_ptr::<u64>();
    unsafe { pointer.write(0x00C0_FFEE) };
}
The tests
make test now runs 45 tests in the kernel; nine are new:
alignment_rounds_to_whole_pagesandthe_hhdm_is_in_the_higher_half– the helpers ofmem.rs;only_whole_frames_are_free– the fake machine: of two ranges, one unaligned, five frames count;the_lowest_frame_comes_first_until_none_is_left– thenNone;freed_frames_come_back_and_nonsense_is_refused– double free, unaligned, frame 0, beyond the end;reserved_frames_are_not_handed_out;most_of_the_ram_is_usable– between 100 and 128 MiB of the machine's 128;every_frame_is_usable_ram_and_none_is_the_bitmap– takes every frame the allocator has. Each must lie wholly in a usable range of the memory map and outside the bitmap, and each stores the address of the previous one: a chain through all of memory, which the test then walks back, freeing every frame. At the end the free count is what it was;a_zeroed_frame_is_zero– a frame filled with0xAB, freed and taken again, comes back as zeros.
The boot check wants the memory map, the "MiB usable" line and the value read back through the HHDM.
Run it
cd course/08-frames
make run
After the timer lines, the memory map, then:
Frames: 125 MiB usable, 32066 frames free; the bitmap takes 4 KiB at 0x61000
Frame 0x62000, seen at 0xffff800000062000 through the HHDM: wrote 0xc0ffee, read 0xc0ffee
The bitmap took the first usable frame, 0x61000, so the first frame handed out is the next one.
The exact numbers depend on QEMU's firmware: under QEMU 8.2 one more frame is free.
What can go wrong
-
The bitmap is not reserved: the first frame handed out is the bitmap itself.
alloc_frame_zeroedfills it with zeros – every frame is "free" now – and the kernel panics as soon as it gives the frame back:Frame 0x61000, seen at 0xffff800000061000 through the HHDM: wrote 0xc0ffee, read 0xc0ffee KERNEL PANIC: panicked at src/pmm.rs:213:9: free_frame(0x61000): NotAllocatedIn
make test,a_zeroed_frame_is_zerofails first. -
A physical address used as a pointer:
frame.0 as *mut u64instead offrame.as_mut_ptr(). Nothing is mapped at virtual0x62000, and chapter 5's handler reports it:EXCEPTION: PAGE FAULT at address 0x0000000000062000 cause: page not present, write, kernel mode -
Limine's memory counted as usable: the treacherous one – the kernel boots normally; it only uses one frame, and that one happens to be harmless.
every_frame_is_usable_ram_and_none_is_the_bitmap, which writes into every frame, ends in a page fault in the middle of the HHDM (0xffff800007f79000). Most likely one of the frames it wrote into was one of Limine's page tables, and with it the mapping of that part of the HHDM went away. -
Frames half inside a range: a region boundary that is not a multiple of 4 KiB, rounded the wrong way, hands out a frame that partly belongs to the firmware.
only_whole_frames_are_freehas such a region.
Experiments
- Start QEMU with
-m 512M(inrun-qemu.sh). How big is the bitmap now, and where does it live? - The test chains every frame to the one before. That chain is an allocator – a free list: allocating takes the first frame of the chain, freeing puts one in front. Write it. What does it need instead of a bitmap, and what can it not do that the bitmap can (hint: "is this frame free?")?
- Remove
next_word(always search from word 0) and time the test that takes every frame. - Write
alloc_contiguous(n):nframes that follow each other – devices that read memory themselves need that. Why is it easy with a bitmap and hard with a free list?
9 – Paging
Goal: read the page tables the CPU uses, change them, and use that for the first thing paging buys a kernel: a
stack that cannot overflow silently.
You end up with: translate (what the CPU does on every memory access, in software), map and unmap, kernel
stacks with a guard page, and a real stack overflow (fault=overflow) that ends in the double fault handler of
chapter 5.
Code: course/09-paging/ (chapter 8
plus paging.rs, stack.rs, one more Limine request and a fourth boot check)
What changed: diff -ru course/08-frames course/09-paging (in the repository) shows every line this chapter adds.
Background: four levels of tables
A virtual address on x86-64 has 48 meaningful bits (the 16 above them repeat bit 47). The CPU cuts them into five pieces:
 47      39 38      30 29      21 20      12 11            0
+----------+----------+----------+----------+---------------+
| PML4     | PDPT     | PD       | PT       | offset        |
+----------+----------+----------+----------+---------------+
   9 bits     9 bits     9 bits     9 bits      12 bits
Each 9-bit piece picks one of 512 entries in a table. CR3 holds the physical address of the top table, the PML4. Its entry names the next table (a PDPT), whose entry names a PD, whose entry names a PT, whose entry names the frame. The 12-bit offset is the position inside that frame's 4 KiB. Every table is itself one frame of 512 entries × 8 bytes – which is why chapter 8's allocator comes first: new tables are new frames.
An entry is a physical address plus flags in the bits the address does not need: present (bit 0), writable (bit 1), no execute (bit 63), and a few more. A PD entry can also say huge (bit 7): "I map 2 MiB myself, there is no PT below me" – a PDPT entry the same with 1 GiB. Limine builds the HHDM mostly from 2 MiB pages.
The CPU caches translations in the TLB. Changing an entry does not change the TLB: after removing a mapping we
must tell the CPU with invlpg.
Step 1: entries and tables
An entry is a u64; the address is bits 12–51, everything else is flags. A table is 512 of them, aligned to 4 KiB.
We reach every table through the HHDM – an entry holds a physical address, and PhysAddr::as_mut_ptr from chapter
8 turns it into a pointer:
#![allow(unused)]
fn main() {
/// The entry numbers of `virt` in the four tables, PML4 first.
pub fn indices(virt: u64) -> [usize; 4] {
    [39, 30, 21, 12].map(|shift| ((virt >> shift) & 0x1FF) as usize)
}
}
Step 2: translating by hand
translate walks the four levels like the CPU: an entry that is not present ends the walk, a huge entry ends it
early with a bigger page, and the PT entry ends it with a 4 KiB frame:
#![allow(unused)]
fn main() {
        let page_size = match level {
            1 if entry.is(Flags::HUGE) => 1 << 30,
            2 if entry.is(Flags::HUGE) => 1 << 21,
            3 => PAGE_SIZE,
            _ => {
                entries = &table(entry.address()).0;
                continue;
            }
        };
}
One trap: in a huge page entry, bit 12 is not part of the address but the PAT bit, which picks the caching type. Limine sets it for the framebuffer. Rounding the address down to the page size removes it:
#![allow(unused)]
fn main() {
        let start = entry.address().0 & !(page_size - 1);
}
The reference kernel had exactly this bug until this chapter found it (bug #26).
A new Limine request, EXECUTABLE_ADDRESS, says where the kernel lies physically. It lets a test check translate
against an answer that does not come from our own code.
Step 3: mapping and unmapping
map walks the same way, but a missing table on the way is created – a zeroed frame from chapter 8 (a frame with
old contents would be read as 512 random entries):
#![allow(unused)]
fn main() {
        if !entry.is(Flags::PRESENT) {
            // a new, empty table: zeroed, or its garbage would be read as entries
            let new = pmm::alloc_frame_zeroed().ok_or(MapError::OutOfFrames)?;
            // the tables above allow everything; the last entry decides what the page may do
            *entry = Entry::new(new, Flags(Flags::PRESENT.0 | Flags::WRITABLE.0));
}
The CPU combines the flags of all four levels: a page is writable only if every entry on the way says so. So
the upper entries allow everything and the last one decides. map refuses an address inside a huge page
(splitting it is possible, but not needed yet), an address that is mapped already, and anything not aligned to
4 KiB.
unmap clears the last entry, flushes the TLB entry, and gives the frame back to the caller:
#![allow(unused)]
fn main() {
    entries[i1] = Entry(0);
    // the CPU keeps recent translations in its TLB; without this it could go on using the old one
    unsafe { asm!("invlpg [{}]", in(reg) virt, options(nostack, preserves_flags)) };
}
Empty tables are not freed again – a few frames, and much simpler.
Step 4: a stack with a guard page
Chapter 5 could only fake a stack overflow, by pointing the stack at an unmapped address. Now we can build a stack
whose end really is unmapped. stack::alloc takes a slice of an area reserved for stacks (PML4 entry 510), leaves
its lowest page unmapped – the guard page – and maps the pages above it:
#![allow(unused)]
fn main() {
    for page in 1..=pages {
        let frame = pmm::alloc_frame_zeroed().ok_or(MapError::OutOfFrames)?;
        paging::map(guard + page * PAGE_SIZE, frame, Flags::DATA)?;
    }
}
fault=overflow switches to such a stack and calls a function that calls itself forever, 512 bytes deeper each
time:
#![allow(unused)]
fn main() {
    fn deeper(depth: u64) -> u64 {
        let room = core::hint::black_box([depth; 64]); // 512 bytes of stack per call
        deeper(depth + 1) + room[0]
    }
}
After 16 KiB the next push lands in the guard page: a page fault. To report it, the CPU would push the exception frame on the same stack – into the guard page again – and that is a double fault, which chapter 4 gave its own stack.
The tests
make test now runs 52 tests in the kernel; seven are new:
an_address_is_four_indices_and_an_offset– the kernel's own address is entries 511, 510, 0, 0;the_kernel_is_where_limine_put_it–translateof a function in the kernel gives the physical address Limine reported;the_hhdm_maps_every_frame_to_itself– and the lower half is empty (chapter 8's page fault at0x62000);a_mapped_frame_appears_at_its_new_address– the first page in an empty 512 GiB region costs exactly three new tables; what is written at the new address is in the frame; mapping twice and unaligned addresses are refused; afterunmapthe address translates to nothing;the_framebuffer_translates_exactly– the PAT bit of bug #26;huge_pages_are_not_split– an HHDM address inside a 2 MiB page;the_stack_is_mapped_and_its_guard_page_is_not– and two stacks do not overlap.
A fourth boot check runs fault=overflow and wants the double fault on its own stack, with the last page fault in
the guard page.
Run it
cd course/09-paging
make run
After the memory lines of chapter 8:
Paging: PML4 at 0x7f7d000; kmain at 0xffffffff800104d0 is physical 0x7de44d0 (the kernel starts at physical 0x7dd4000)
Mapped frame 0x62000 at 0xfffffe0000000000: wrote 0xbeef there, read 0xbeef through the HHDM
Stack: 16 KiB below 0xffffff0000005000, its guard page at 0xffffff0000000000 is mapped: no
The exact physical addresses depend on the firmware and on the size of your kernel. And the real overflow:
KERNEL_CMDLINE=fault=overflow make run
running on the double fault stack: yes (rsp=0xffffffff800240d0)
KERNEL PANIC: panicked at src/interrupts.rs:153:5:
EXCEPTION: DOUBLE FAULT (code 0x0), last page fault at 0xffffff0000000be8
rip=0xffffffff800099e7 cs=0x8 rflags=0x286 rsp=0xffffff0000000bf0 ss=0x10
The page fault was at …0be8, inside the guard page …0000–…0fff; the stack pointer rsp of the interrupted
code was in it too.
What can go wrong
- The guard page is mapped as well: start the loop in
stack::allocat 0, and the overflow does not stop at the end of the stack. Here it ends one page further down, atlast page fault at 0xfffffeffffffff28– below the stack area, where nothing is mapped. A stack allocated before it would have been overwritten without a sound. - The TLB is not flushed: without
invlpginunmap, the old translation survives. Reading the page right afterunmapstill gives0xbeef; withinvlpgthe same read is a page fault (page not present, read). - A new table without the writable flag: the page itself says writable, but one entry above it does not, and
the first write is a
protection violation, write. All four levels count. - A huge page translated with the 4 KiB mask: bug #26 – the result is 4 KiB off wherever the PAT bit is set.
Experiments
- Print the four indices and every entry on the way for
kmain, a stack variable and the framebuffer. Which levels are huge pages? - Map the same frame at two addresses and write through one. Then map a page without
WRITABLEand write to it – what does the page fault's error code say? - Count how deep
deepergets before the fault (storedepthin a static). Does it match 16 KiB / 512 bytes? Why not exactly? - Make
unmapfree the tables that became empty. When is a table empty, and why is the PML4 never freed?
The next chapter puts a heap on top: memory in any size, not just 4 KiB at a time – and with it, Vec and String.
10 – The heap
Goal: memory in any size, not just 4 KiB at a time – so that the kernel can use Box, Vec and String like
any Rust program.
You end up with: a free-list allocator behind #[global_allocator], a heap that maps fresh pages with chapter
9's map whenever it is full, Rust's alloc crate working in the kernel, and a request too big for the heap
(fault=heap) that ends in a panic. This chapter ends part II.
Code: course/10-heap/ (chapter 9
plus heap.rs, a few lines in main.rs and a fifth boot check)
What changed: diff -ru course/09-paging course/10-heap (in the repository) shows every line this chapter adds.
Background: why frames are not enough
Chapter 8 hands out whole frames, chapter 9 puts them where we want them. But most things a kernel keeps are small and of a size known only at run time: a line of text, a list of open files, a table that grows. Taking a 4 KiB frame for 20 bytes wastes almost all of it, and a list longer than a frame does not fit at all.
A heap cuts bigger pieces of memory into blocks of any size and takes them back in any order. Rust asks for
one with a Layout – a size and an alignment – and gives it back with the same Layout. That is the whole
interface, the trait GlobalAlloc. Once a kernel has one, the alloc crate works: Box, Vec, String,
format!, BTreeMap – everything of the standard library that needs nothing but memory.
The heap needs bookkeeping: which parts are free? Our allocator keeps a free list. Every gap of free memory stores its size and a pointer to the next gap in its own first 16 bytes – the list costs no memory besides the gaps themselves. The gaps are sorted by address:
 first
   |
   v
 +-----------+--------+------------------+--------+------------+---------
 | size, next| block  | size, next       | block  | size, next | ...
 |  gap 64 B | in use |  gap 1024 B      | in use |  gap 32 KiB|
 +-----|-----+--------+-------|----------+--------+------------+---------
       +----------------------^          +--------^
Step 1: the bookkeeping in the gap
A gap begins with this:
#![allow(unused)]
fn main() {
#[repr(C)]
struct Gap {
    size: usize,
    next: *mut Gap,
}
}
Every block starts and ends on a multiple of 16 bytes, and is at least 16 bytes big. Then whatever is left over
when a block is cut out of a gap is either nothing or big enough to hold a Gap of its own:
#![allow(unused)]
fn main() {
fn block_size(layout: Layout) -> usize {
    layout.size().max(BLOCK_ALIGN).next_multiple_of(BLOCK_ALIGN)
}
}
The list itself is a pointer to the first gap and a counter of the bytes handed out. add_region gives it a piece
of memory; it works on any memory, which is how the tests run it on a 16 KiB array.
Step 2: allocating – first fit
alloc walks the list and takes the first gap the block fits into. The block may have to start further up than
the gap, to be aligned as the Layout asks:
#![allow(unused)]
fn main() {
            let block_start = gap_start.next_multiple_of(align);
            let block_end = block_start + size;
            if block_end <= gap_end {
}
Then the gap leaves the list, and what the block does not cover goes back: the padding in front of it, the rest behind it. Both are multiples of 16 – step 1 made sure of that.
Step 3: freeing – and merging
dealloc puts the block back into the list at its address. Without more than that, the heap would crumble: free
three neighbouring blocks of 100 bytes, and the list holds three gaps of 100 – none of them big enough for 250
bytes, although 300 free bytes lie side by side. This is fragmentation. So insert merges a new gap with the
one right after it and the one right before it if they touch:
#![allow(unused)]
fn main() {
            // touches the gap after it: one gap
            if !after.is_null() && start + size == after as usize {
                (*gap).size += (*after).size;
                (*gap).next = (*after).next;
            }
}
Because the list is sorted, the two neighbours are found in the same walk that finds the place for the gap.
Step 4: the global allocator, which grows
The kernel heap is a free list behind a spin lock, plus the end of its mapped area. It has an area of its own,
PML4 entry 507 (0xfffffd8000000000) – 508 and 509 hold chapter 9's test pages, 510 its stacks. It starts with nothing mapped. When
a request does not fit, it maps at least 64 KiB more at its end – frames from chapter 8, map from chapter 9 – and
hands them to the list:
#![allow(unused)]
fn main() {
        let start = self.end;
        while self.end < start + bytes {
            let Some(frame) = pmm::alloc_frame() else {
                break;
            };
            if paging::map(self.end as u64, frame, Flags::DATA).is_err() {
                pmm::free_frame(frame);
                break;
            }
            self.end += PAGE_SIZE as usize;
        }
}
The new region starts where the old one ends, so insert merges it with the last gap. The heap stops at 16 MiB:
beyond that, alloc returns null. Rust's collections cannot report that to the caller – Vec::with_capacity has
no error – so Rust panics with memory allocation of … bytes failed. fault=heap does exactly that.
The #[global_allocator] attribute makes this the allocator behind the alloc crate, and extern crate alloc; in
main.rs brings the crate in:
#![allow(unused)]
fn main() {
#[global_allocator]
static HEAP: KernelHeap = KernelHeap(Mutex::new(State {
    list: FreeList::empty(),
    end: START,
}));
}
The lock is a spin lock with interrupts on, like the one of the page tables. That is only safe because no
interrupt handler allocates. If one did, it could interrupt a CPU in the middle of alloc and wait forever for
the lock the same CPU holds. The reference kernel turns interrupts off around every heap call for this reason.
What the reference kernel (kernel/src/mem/heap.rs)
has besides: interrupts off around the lock, statistics (number and largest gap, shown by its shell), and a
bigger limit. Neither heap ever gives pages back.
The tests
make test now runs 61 tests in the kernel; nine are new. Four test the free list on a 16 KiB array, without the
heap area:
freed_blocks_merge_into_one_gap– three blocks freed in the order middle, left, right end up as one gap;blocks_are_aligned_as_asked– a block aligned to 4096 is, and its padding is merged back after freeing;a_full_list_says_null– and after a free there is room again;first_fit_takes_the_first_hole– a freed block is the first one used again.
Five test the kernel heap:
box_string_and_format_work– and theBoxlies in the heap area;the_heap_grows_when_it_is_full– aVecbigger than everything mapped so far makes the heap map more;freed_memory_is_used_again– 10 000 boxes of 32 bytes, one after another, leave the heap exactly as it was;a_btreemap_works– 1000 entries;more_than_the_limit_is_null– a request over 16 MiB gets null, and maps nothing.
A fifth boot check runs fault=heap and wants the panic.
Run it
cd course/10-heap
make run
After the stack line of chapter 9:
Heap: Box at 0xfffffd8000000000 holds 42, a Vec of 1000 numbers sums to 500500, format! made "YAK has 10 chapters"
Heap: 8048 bytes in use, 64 KiB mapped at 0xfffffd8000000000 - after drop: 0 bytes in use
The first Box is the first block of the heap. 8048 bytes are 16 for the Box (8 rounded up), 8000 for the
numbers and 32 for the String (19 bytes); after drop, nothing is in use. And the request that is too big:
KERNEL_CMDLINE=fault=heap make run
Asking the heap for 16 MiB and one byte ...
KERNEL PANIC: panicked at /rustc/76456a688bc0ed897fa23a677d4ddb5b3fdb575a/library/alloc/src/alloc.rs:699:9:
memory allocation of 16777217 bytes failed
The panic comes from Rust's alloc crate, not from our code: alloc returned null, and Vec gave up. The path
and line depend on your compiler version.
What can go wrong
- Gaps are not merged: take out the merge with the following gap, and freed blocks stay gaps of their own. The
first test that notices is
blocks_are_aligned_as_asked: three gaps where there should be one,left: 3, right: 1. - The alignment is ignored: start the block at the start of the gap, and the block that should be aligned to
4096 is not:
left: 16, right: 0– it is 16 bytes past a page boundary. - Sizes are not rounded to 16: a
Box<u64>takes 8 bytes, and the gap behind it starts at an address that is not a multiple of 16, and a leftover gap can be smaller than its own 16-byte header, which then reaches into the next block. The kernel soon follows a pointer that is none:misaligned pointer dereference: address must be a multiple of 0x8 but is 0x1, from the debug checks Rust builds in. - The pages are not mapped: hand the area to the list without
map, and the firstBoxwrites a gap header into nothing:PAGE FAULT at address 0xfffffd8000000000,page not present, write, kernel mode.
Experiments
- Print the list – start and size of every gap – after each step of
freed_blocks_merge_into_one_gap. - Change first fit to best fit (the smallest gap that is big enough). Which test notices? Is it better or worse for the 10 000 boxes?
- Allocate in a loop until
fault=heap's panic, printingheap::mapped()each time. How often does the heap grow, and by how much? - Make
alloctake interrupts off while it holds the lock (cli, andstionly if they were on before). Then allocate in the timer handler – what happened without it?
Part II is complete: frames, pages and a heap. Part III builds on them a first shell – a loop that reads a line, splits it into words and runs a command.
11 – A first shell
Goal: a kernel you can talk to: it prints a prompt, reads a line from the keyboard, and runs what you typed.
You end up with: a line editor, a splitter that turns a line into words (with quotes), a table of six commands
(help, echo, clear, uptime, sleep, mem), and a make test that types four commands and checks what
the shell answers. This chapter is part III.
Code: course/11-shell/ (chapter 10
plus words.rs, shell.rs, and a kmain that ends in the shell instead of chapter 7's echo loop)
What changed: diff -ru course/10-heap course/11-shell (in the repository) shows every line this chapter adds.
Background: a loop with four steps
A shell is a loop:
print the prompt  ->  read a line  ->  split it into words  ->  run the command the first word names
       ^                                                                       |
       +-----------------------------------------------------------------------+
None of the steps is new hardware. Reading keys is chapter 7, sleeping chapter 6, the numbers of mem come from
chapters 8 and 10. What is new is that the kernel now keeps things whose size it learns only at run time: a line
as long as you type it, as many words as the line has. Before chapter 10 that needed fixed arrays and limits
everywhere; now it is a String and a Vec<String>.
One decision runs through the whole chapter: every piece writes to a core::fmt::Write, not to the screen. The
shell passes the screen; a test passes a String – and can compare exactly what a command printed.
Step 1: words
words::split walks the line once. A space ends a word, unless a quote is open; inside "…" or '…' a space is
part of the word, and the quotes themselves are not:
#![allow(unused)]
fn main() {
        match (quote, c) {
            // inside quotes: everything up to the matching quote belongs to the word
            (Some(open), c) if c == open => quote = None,
            (Some(_), c) => word.push(c),
            (None, '"' | '\'') => {
                quote = Some(c);
                in_word = true;
            }
}
in_word tells "no word yet" from "an empty word": two spaces in a row are no word, '' is one. A quote that is
still open at the end of the line is an error, UnclosedQuote, not a guess.
Step 2: a line editor
LineEditor::feed takes one key at a time. A character goes into the line and onto the screen; Enter hands back
the line; Backspace takes the last character out and erases it on the screen with chapter 7's "\x08 \x08":
#![allow(unused)]
fn main() {
            Key::Backspace => {
                // at the start of the line there is nothing to erase - and the prompt must stay
                if self.line.pop().is_some() {
                    let _ = out.write_str("\x08 \x08");
                }
            }
}
A line holds at most 72 characters. With the 5 characters of the prompt it fits into a terminal of 80 columns and
never wraps – which matters because \x08 only moves left inside a row, never up into the row above.
Step 3: a table of commands
A command is a name, a usage line, a help text and a function. The function gets the words after the name and the place to write to, and may fail with a message:
#![allow(unused)]
fn main() {
type Run = fn(&[String], &mut dyn Write) -> Result<(), String>;
}
All commands are one static slice. help walks it, and a new command is one more entry. execute puts the
steps together – split, take the first word, find it, call it:
#![allow(unused)]
fn main() {
    let Some((name, args)) = words.split_first() else {
        return; // an empty line: nothing to do
    };
    match COMMANDS.iter().find(|command| command.name == name) {
        Some(command) => {
            if let Err(message) = (command.run)(args, out) {
                let _ = writeln!(out, "{}: {}", name, message);
            }
        }
}
sleep shows the error path: it wants exactly one argument, and a number. A slice pattern checks the first, parse
the second:
#![allow(unused)]
fn main() {
    let [ms] = args else {
        return Err(String::from("usage: sleep <ms>"));
    };
}
Step 4: the loop
run is the loop from the background, with the screen as its Write. kmain no longer echoes keys; it starts
the keyboard, prints Shell: type help and Enter and calls shell::run(), which never returns.
What the reference kernel's shell (kernel/src/shell/, about 2100 lines) has besides: input from the serial port
as well (IRQ 4), so the shell works in a terminal; escape sequences for the arrow keys and a cursor that moves
inside the line; history, tab completion and Ctrl keys; backslash escapes in words; and many more commands. This
chapter reads only the PS/2 keyboard – type into the QEMU window, not into the terminal.
The tests
make test now runs 71 tests in the kernel; ten are new:
spaces_separate_words,quotes_keep_spaces_in_a_word,an_unclosed_quote_is_an_error– the splitter, also with empty words ('') and a quote inside the other kind ("it's");the_line_editor_echoes_and_erases– exactly the bytes on the screen, and one Backspace too many does nothing;a_full_line_takes_no_more_keys– 77 keys, 72 characters;echo_joins_its_words,empty_lines_and_unknown_commands,help_lists_every_command;sleep_checks_its_argument_and_sleeps– three wrong calls and one that waits at least 50 ms;uptime_and_mem_report_numbers.
The boot check types four lines with QEMU's sendkey: echo Hi YAK! (with Shift, Caps Lock and two spaces),
echo shelx, Backspace, l, then nope and mem – and wants Hi YAK! with one space, shell, the unknown
command and the memory numbers.
Run it
cd course/11-shell
make run
Click into the QEMU window and type. What the boot check typed, as a terminal shows the serial output:
Shell: type help and Enter
yak> echo Hi  YAK!
Hi YAK!
yak> echo shell
shell
yak> nope
unknown command: nope (try help)
yak> mem
frames: 31854 of 31884 free (124 of 124 MiB)
heap: 128 bytes in use, 64 KiB mapped
yak>
The second line was typed as shelx, Backspace, l. The serial log keeps every byte – shelx\x08 \x08l – and a
terminal, like the screen, moves back over the x, covers it with a space and moves back again.
And help, uptime and a wrong sleep:
yak> help
  help         list the commands
  echo [words] print the words, one space between them
  clear        clear the screen
  uptime       time since boot
  sleep <ms>   wait for <ms> milliseconds
  mem          free frames and the heap
yak> uptime
up 3.94 s
yak> sleep soon
sleep: not a number: soon
What can go wrong
- Backspace at the start of the line: without the
if, Backspace erases on the screen even when the line is empty – and eats the prompt.echoand six Backspaces leaveyakofyak>on the screen. The test saysleft: "ls\u{8} \u{8}\u{8} \u{8}\u{8} \u{8}hi\n", one erase too many. - Every space ends a word: split on each space without
in_word, and two spaces make an empty word between them.echo a 'b c'then printsa b cinstead ofa b c. - No limit on the line: 77 keys give a line of 77 characters (
left: 77, right: 72). A line long enough wraps – on an 80-column terminal much sooner than on the 160-column screen – and since chapter 3'sput_charmoves\x08only inside a row, Backspace cannot erase what wrapped.
Experiments
- Add a command
add <a> <b>that prints the sum. What shouldadd 1andadd 1 xsay? - Add a history: the last ten lines in a
Vec<String>, and a commandhistorythat prints them. - Let
echounderstand a backslash:echo a\ bis the one worda b. Where insplitdoes it go, and what should a backslash at the end of the line do? - Read the serial port too: turn on its receive interrupt (IRQ 4), put the bytes into a second ring buffer, and
let
read_keytake from both. Which byte does a terminal send for Enter, and which for Backspace?
The shell is the place every later part plugs into: a command per new subsystem – for the CPUs, the disk, the network.
12 – ACPI and the APIC
Goal: replace the PIC of 1981 with the interrupt controllers of every PC since the late 1990s – and find them
the way a real kernel does, in the firmware's ACPI tables.
You end up with: a parser for the RSDP, the RSDT/XSDT and the MADT; the local APIC switched on, with its own
timer measured against the PIT; the I/O APIC routing the timer and the keyboard; and QEMU started with a local APIC
again. This chapter begins part IV.
Code: course/12-apic/ (chapter 11
plus acpi.rs, lapic.rs, ioapic.rs, an uncached mapping in paging.rs, and interrupts::start instead of
start_timer/start_keyboard)
What changed: diff -ru course/11-shell course/12-apic (in the repository) shows every line this chapter adds.
Background: two APICs, and a map of the wiring
An x86 PC has two kinds of APIC (advanced programmable interrupt controller):
 keyboard --+                                         +--> local APIC --> CPU 0
 PIT -------+--> I/O APIC: 24 inputs, each with   ----+    (EOI, timer)
 disk, ... -+    "vector v on the CPU with ID c"      +--> local APIC --> CPU 1 ...
- The I/O APIC is where the interrupt lines of the devices end. For each input a redirection entry says which vector to raise on which CPU – or that the input is masked. It replaces the PIC's fixed "line n is vector 32 + n".
- Every CPU core has a local APIC. Every interrupt reaches the core through it, and it wants an end of interrupt after each one, like the PIC. It also has a timer of its own – one per CPU, which a scheduler on several CPUs will need.
Chapter 6 already met the local APIC: Limine leaves its input for the PIC (LINT0) masked, and under QEMU 8.2 no
PIC interrupt arrived while it existed (bug #25). So chapters 6–11 ran on a CPU without one
(-cpu qemu64,-apic). This chapter switches the PIC off instead and starts QEMU with -cpu qemu64.
Where are these controllers? Their registers are memory at physical addresses, and not every machine uses the same
ones. The firmware says where, in its ACPI tables: Limine hands us the RSDP, which points to the RSDT
(or, since ACPI 2.0, the XSDT with 64-bit addresses), a list of all other tables. The one we need is the
MADT (signature APIC): the CPUs, the I/O APICs, the local APIC's address – and the interrupt source
overrides, the ISA lines that are not wired the obvious way. On almost every PC, and in QEMU, one of them is the
timer: ISA IRQ 0 arrives at I/O APIC input 2.
Step 1: reading the ACPI tables
Every table starts with the same 36-byte header: a four-letter signature, the length, and a checksum – all bytes of the table add up to 0:
#![allow(unused)]
fn main() {
pub fn checksum_ok(bytes: &[u8]) -> bool {
    bytes.iter().fold(0u8, |sum, &byte| sum.wrapping_add(byte)) == 0
}
}
acpi::read checks the RSDP (RSD PTR , checksum), takes the RSDT or the XSDT depending on the RSDP's revision,
checks that table, and walks its entries. Limine gives the RSDP as an HHDM address, and Limine maps the tables into
the HHDM too (the memory map's "reserved, but in the HHDM" lines); a page it left out would be mapped by bytes.
The MADT's body is a list of records, each starting with a type and a length. We read four types and skip the rest by their length:
#![allow(unused)]
fn main() {
        match kind {
            // a CPU's local APIC; flag bit 0: enabled, bit 1: can be enabled later
            0 if u32_at(entry, 4) & 0b11 != 0 => cpus += 1,
            1 if io_apic.is_none() => io_apic = Some((PhysAddr(u32_at(entry, 4) as u64), u32_at(entry, 8))),
}
Type 2 is an override: ISA IRQ entry[3] arrives at global system interrupt (GSI) u32_at(entry, 4) – the
number of the I/O APIC input. Madt::gsi(irq) returns it, or irq itself if there is no override. An override
also says whether a line is active-low or level-triggered; QEMU's say so for IRQ 5, 9, 10 and 11 (flags 0xd),
not for the timer and the keyboard, so this chapter does not read them. The parser is plain code over a byte slice,
so a test feeds it a hand-made MADT, too.
Step 2: device registers, mapped uncached
The local APIC's registers are 4 KiB at 0xfee00000, the I/O APIC's at 0xfec00000. They are not RAM, so they are
not in Limine's HHDM – a read there page-faults. Chapter 9's map puts them there, with one more flag:
#![allow(unused)]
fn main() {
    /// Device registers: like data, but never cached - a cached read would return an old value, not the device's.
    pub const DEVICE: Flags = Flags(Self::DATA.0 | Self::NO_CACHE.0);
}
Every access to them is read_volatile/write_volatile: to the compiler, two reads of the same address with no
write between give the same value, and it may drop the second – for a register that changes on its own, wrong.
This is also why the interrupts now start after memory: the registers must be mapped (chapter 9, frames for new
tables from chapter 8), and the MADT's lists are Vecs (chapter 10). kmain calls interrupts::start after the
heap demonstration; until then the kernel runs without hardware interrupts, which nothing before needs.
Step 3: the local APIC and the I/O APIC
The local APIC is switched on through its spurious interrupt vector register: bit 8 enables it, the low byte is
the vector it raises for an interrupt that vanished before it could deliver it (such a spurious interrupt gets no
end of interrupt). The end of interrupt itself is a write of 0 to register 0xB0 – the timer and keyboard handlers
call lapic::end_of_interrupt instead of the PIC's.
The I/O APIC has only two registers: write a register number to SELECT, then read or write it through WINDOW.
Input n's redirection entry is registers 0x10 + 2n and 0x11 + 2n. init masks all 24 inputs; route writes
one entry – the vector in the low byte, the destination CPU's APIC ID in the top byte, everything else 0 (a normal
interrupt, edge-triggered, active high – what ISA lines are):
#![allow(unused)]
fn main() {
pub fn route(gsi: u32, vector: u8, cpu: u8) {
    set_entry(input(gsi), vector as u64 | (cpu as u64) << 56);
}
}
The PIC is still in the machine. pic::init moves it off the exception vectors and masks every line – and that is
all this chapter does with it.
Step 4: a timer that has to be measured
The local APIC timer counts down from a number we write, raises its vector at zero, and in periodic mode starts
again. How fast it counts depends on the machine, so we measure it against a clock we know: the PIT, for a tenth of
a second. start puts the steps together:
#![allow(unused)]
fn main() {
    // The PIT is our clock for a moment: its IRQ 0 arrives at the I/O APIC input the MADT says (2, not 0)
    pit::init(time::TICKS_PER_SECOND);
    ioapic::route(madt.gsi(TIMER_IRQ), TIMER_VECTOR, cpu);
    unsafe { asm!("sti", options(nomem, nostack)) };
    // ... long enough to measure the local APIC timer against it; then the APIC timer takes over the same vector
    let counts_per_tick = lapic::measure_timer(CALIBRATION_TICKS);
    ioapic::mask(madt.gsi(TIMER_IRQ));
    lapic::start_timer(TIMER_VECTOR, counts_per_tick);
}
measure_timer waits for the next tick, starts the APIC timer at u32::MAX with its interrupt masked, waits ten
ticks, and reads how far it got. Both sources use vector 32 and the same handler, so time does not notice the
change – which is why the PIT's input is masked before the APIC timer starts.
The PIT now runs in mode 2 (one short pulse per period), not mode 3 (a square wave) as in chapters 6–11. In mode 3 the I/O APIC delivered two interrupts per period – 200 Hz – and the measurement came out at half the right value (bug #27, found while writing this chapter).
What the reference kernel (kernel/src/arch/x86_64/)
does besides: it measures the APIC timer with PIT channel 2 by polling, without any interrupt; it reads the
overrides' polarity and trigger mode; it uses the local APIC to start and wake the other CPUs (inter-processor
interrupts); and it routes more devices – the serial port, the disk, the network card.
The tests
make test now runs 82 tests in the kernel. Twelve are new; two PIC tests of chapter 6 became one
(every_line_is_masked):
the_checksum_adds_up_to_zero,a_handmade_madt_is_parsed(two CPUs of which one is enabled, an I/O APIC, an override, an unknown type),a_madt_without_io_apic_is_refused;qemus_tables_describe_qemus_machine– the real tables:APICandFACPamong them, one CPU, the addresses, and IRQ 0 at input 2;the_cpu_has_a_local_apic(CPUID),the_registers_are_mapped_uncached,the_apic_is_on_and_built_into_the_cpu,its_id_is_the_one_cpuid_reports,the_timer_runs_periodically_on_vector_32;the_timer_was_measured_against_a_100_hz_clock– QEMU's local APIC counts at 1 GHz; divided by 16 that is 625 000 per tick, and the test wants 550 000 to 700 000 (a busy host delays the PIT's ticks a little, bug #29). It is the only test that checks time against a second clock – the one that catches bug #27, which halves it;qemus_io_apic_has_24_inputs,only_the_keyboard_is_routed– the PIT's input is masked again.
The boot checks of chapter 11 run unchanged: the shell is typed into through the I/O APIC now.
One test failed on its first run and taught something: the_registers_are_mapped_uncached compared the page's
flags with == and got 0x8000000000000073 – bits 5 and 6 more than DEVICE. The CPU sets them itself:
accessed when a page is read, dirty when it is written. The test now checks contains.
Run it
cd course/12-apic
make run
After the heap lines:
ACPI: RSDP revision 0, 5 tables: FACP APIC HPET MCFG WAET
MADT: 1 CPU, local APIC at 0xfee00000, I/O APIC at 0xfec00000 with 24 inputs
Timer: the PIT's IRQ 0 arrived at I/O APIC input 2; the local APIC timer counts 624964 per tick of 10 ms
Timer: now the local APIC timer of CPU 0 raises vector 32, 100 Hz; input 2 is masked: yes
sleep_ms(1000) took 1010 ms (at least 1000: yes), the CPU waited in hlt
Keyboard: IRQ 1 arrives at I/O APIC input 1, vector 33 (US layout)
Shell: type help and Enter
Revision 0 is ACPI 1.0: QEMU's BIOS (SeaBIOS) gives an RSDT. The count per tick differs a little from run to run –
it is measured. QEMU 8.2.2 printed 624407.
What can go wrong
Three of these mistakes look the same: the kernel prints the heap lines and then nothing, for ever. No tick
arrives, so measure_timer waits for one that never comes.
- No end of interrupt: take
lapic::end_of_interrupt()out of the timer handler. The first tick is handled, the local APIC waits for its EOI, and delivers no second one. - The override ignored: route IRQ 0 to input 0 instead of
madt.gsi(0). Input 2, where the PIT really is, stays masked. - The APIC not switched on: leave bit 8 out of the spurious register.
- The PIT not masked: leave out
ioapic::mask, and two clocks drive vector 32. Nothing hangs, every test is green,sleep_ms(1000)even says 1010 ms – butsleep 5000in the shell returns after 2.7 s on a watch. The kernel measures time in its own ticks, and those come twice as often. - The PIT in mode 3: bug #27 – the same symptom, for the length of the measurement: the test says
311689 counts per tick.
Experiments
- Start QEMU with
-smp 4(inrun-qemu.sh). How many CPUs does the MADT list now? Which APIC IDs do they have? - Print every override with its flags. Which lines are level-triggered, and what are they for (look up IRQ 9 in
the FADT –
FACP– as "SCI")? - Route the keyboard to vector 50 instead of 33. What else has to change for it to work?
- Use the timer's one-shot mode instead of periodic: start it again in the handler. When would a kernel want that rather than a fixed beat?
The rest of part IV builds on this timer: threads, and a scheduler that its ticks switch between them.
13 – Threads and a scheduler
Goal: several things at once on one CPU – threads that the timer switches between, and that wait without
burning the CPU.
You end up with: kernel threads with guarded stacks, a context switch of 15 instructions, a
round-robin scheduler that the local APIC timer of chapter 12 drives, blocking waits (sleep, keyboard, join)
without lost wake-ups, an idle thread, and a shell command threads.
Code: course/13-threads/
(chapter 12 plus task.rs, stack::free, a heap that locks with interrupts off, and sleep_ms/read_key that
block instead of halting)
What changed: diff -ru course/12-apic course/13-threads (in the repository) shows every line this chapter adds.
Background: a thread is a stack
What does the CPU need to continue a piece of code later? Its registers – the instruction pointer, the stack pointer, the rest – and its stack, where the calls that led here keep their data. A thread is exactly that: a stack of its own and the registers that go with it.
Switching from thread A to thread B is therefore: push A's registers onto A's stack, remember A's stack pointer, load B's stack pointer, pop B's registers. B continues wherever it stopped – because B stopped in the very same function, which now returns. This is the context switch.
Who decides when to switch? Threads may give up the CPU themselves (yield_now). But a thread that never does –
a loop, a bug – would keep it for ever. So the timer interrupt of chapter 12, 100 times a second, may move the
running thread to the end of the queue of ready threads and switch to the first one: preemptive round-robin
scheduling.
And a thread that waits – for a time, a key, another thread – should not take turns at all. It is blocked: out of the queue until whoever makes the thing happen wakes it. When no thread is ready, the idle thread runs and halts the CPU until the next interrupt.
Step 1: the context switch
switch_context is assembly – Rust has no way to say "now continue on another stack". It saves only the six
registers a function must keep for its caller (rbx, rbp, r12–r15 in the System V ABI); for the compiler this is
a normal function call, so it already assumes all other registers are changed:
#![allow(unused)]
fn main() {
    "switch_context:",
    "push rbp",
    "push rbx",
    "push r12",
    "push r13",
    "push r14",
    "push r15",
    "mov [rdi], rsp",
    "mov rsp, rsi",
}
…and then the same six pops in reverse order, and ret. The kernel is built without SSE, so there are no
vector registers to save either.
A new thread has never been switched away from, so its stack is filled by hand as if it had: six registers –
r12 holding a pointer to the closure to run – and as return address a small trampoline that calls
thread_start(r12):
#![allow(unused)]
fn main() {
    // lowest address first: r15, r14, r13, r12, rbx, rbp, return address
    let trampoline = thread_trampoline as unsafe extern "C" fn() as usize as u64;
    let frame = [0, 0, 0, entry, 0, 0, trampoline];
}
thread_start turns interrupts on (the switch to it happened with them off), runs the closure, and ends the
thread. Its stack comes from chapter 9's stack::alloc – 32 KiB with a guard page below.
Step 2: the scheduler
The scheduler is a map of threads (each in a Box, so that the stack pointer switch_context writes to does
not move), a queue of ready ids, the current one and the idle one. Every change happens with interrupts off: the
timer handler uses the same data, and on one CPU "interrupts off" means "nobody else runs". Picking the next
thread:
#![allow(unused)]
fn main() {
    fn switch_to_next(&mut self) -> Option<(*mut u64, u64)> {
        let next = self.ready.pop_front().unwrap_or(self.idle);
}
yield_now, blocking and exit differ only in where they put the current thread first – back into the queue,
blocked, dead – then schedule switches. kmain becomes thread 0, "main", by simply being the one that runs
when task::init creates the scheduler; its registers are saved by its first switch.
A thread cannot free the stack it runs on. exit only marks it dead; reap frees the stacks of dead threads
later, in spawn and join – never in the timer interrupt, because freeing takes the page table lock, which the
interrupted thread may hold.
Step 3: preemption
The timer handler now does three things:
#![allow(unused)]
fn main() {
    time::tick();
    // without it, the local APIC would never deliver the next tick - and it must come first: `on_tick` may switch to
    // another thread, and this handler finishes only when this thread runs again
    lapic::end_of_interrupt();
    task::on_tick();
}
on_tick wakes the sleepers whose tick has come, and if any thread is ready, calls yield_now – from inside the
interrupt handler. That is fine: the handler runs on the interrupted thread's stack, and it finishes (with
iretq) when that thread is switched back to.
Step 4: waiting without losing the wake-up
Before this chapter, sleep_ms and read_key waited in hlt loops. Now both call one function:
#![allow(unused)]
fn main() {
pub fn wait_for<T>(wait: Wait, mut ready: impl FnMut() -> Option<T>) -> T {
}
ready checks the condition – a byte in the keyboard buffer, a tick reached, a thread dead. If it is not there,
the thread blocks as wait. The keyboard handler calls task::wake(Wait::Input), the timer wakes Until(tick),
exit wakes Join(id).
The trap is the lost wake-up: check "no key yet" – the key arrives, its handler wakes nobody, since nobody is
blocked yet – block, and wait for a key that has already come. wait_for checks and blocks with interrupts off,
so no handler can run in between. Before task::init there are no threads, and wait_for halts like the old
loops did.
Step 5: a heap for interrupt handlers
Chapter 10 kept the heap's spin lock with interrupts on and said why that was safe: no interrupt handler
allocated. That is over – the timer handler puts threads into the queue, and wake collects them in a Vec. If
a tick came while a thread held the heap lock, the handler would wait for the lock, and the thread that holds it
never runs again. So the heap now takes its lock only with interrupts off:
#![allow(unused)]
fn main() {
    unsafe fn alloc(&self, layout: Layout) -> *mut u8 {
        without_interrupts(|| self.alloc_locked(layout))
    }
}
without_interrupts turns them back on only if they were on before, so it works inside interrupt handlers and
nested.
The console's lock is a different case: it is never taken in an interrupt handler, so a thread that waits for it cannot deadlock – but a thread preempted while it prints holds it until its next turn, and another thread that prints spins until its own time slice is over. The reference kernel has a sleeping lock for this.
What the reference kernel's scheduler (kernel/src/task/)
has besides: several CPUs sharing one queue (each with its own idle thread, and wake-up interrupts between them),
FPU/SSE state per thread, user threads with their own address spaces, CPU time per thread for ps, and the
sleeping lock.
The tests
make test now runs 92 tests in the kernel; ten are new:
a_new_stack_returns_into_the_trampoline– the hand-made first stack, checked word by word;a_thread_runs_and_is_joined– spawned, still ready (main keeps the CPU), run, joined, and gone from the table;yield_takes_turns– two threads that yield three times each;a_thread_that_never_yields_is_preempted– a loop without yield or sleep; main sleeps 50 ms and comes back;a_sleeping_thread_is_blocked_until_its_tick;ended_threads_give_their_stack_back– 20 threads of 8 pages, and the 160 frames are free again afterjoin;the_timer_can_allocate_while_a_thread_holds_the_heap– a thread that allocates in a loop while main wakes up 20 times; with the heap's lock taken with interrupts on, it hangs every time (three of three runs);the_idle_thread_is_thread_1_and_never_queued(bug #28),only_main_and_idle_are_left, and in the shellthreads_lists_the_shell_itself.
The boot check types threads as a fifth command. Concurrency bugs are often rare, so I ran the test kernel seven
times under QEMU 10.2 and three times under 8.2.2: all green.
Run it
cd course/13-threads
make run
After the APIC lines of chapter 12:
Threads: kmain is now thread 0, "main"; the idle thread halts the CPU when nobody else is ready
Threads: while main slept 200 ms, threads 2 and 3 counted to 965585 and 996017 - both ran: yes
Shell: type help and Enter
yak> threads
   0  main     Running
   1  idle     Ready
Two threads that never give up the CPU both counted – the timer took it from them in turns – and main, which was
blocked, came back after its 200 ms. The counts differ from run to run. sleep 5000 in the shell still takes 5.2
seconds on a watch.
What can go wrong
- The end of interrupt after
on_tick: the handler switches to another thread before telling the local APIC it is done – and the APIC delivers no further tick until the interrupted thread runs again, which needs a tick. The boot stops afterThreads: kmain is now thread 0; in the tests,a_thread_that_never_yields_is_preemptedhangs until the 30 s limit. - No
stiinthread_start: new threads run with interrupts off. In the boot, the first counter thread then keeps the CPU – no tick can take it away – and the boot stops at the same place. In the tests it is the idle thread, the first time a test sleeps: itshltwith interrupts off never ends. - The scheduler visible half built: the first version of
task::initinstalled the scheduler with the idle id still 0 –main's – and spawned the idle thread afterwards, with interrupts on. One boot in 20 a tick came in between,yield_nowtookmainfor the idle thread and never queued it again, and the kernel halted for good after theKeyboard:line (bug #28). Nowinitbuilds both threads first and installs the scheduler in one step with interrupts off. - The heap's lock with interrupts on: six test runs pass without the new test. With it, the timer finds the
lock held and the kernel hangs in
the_timer_can_allocate_while_a_thread_holds_the_heap– in three of three runs.
Experiments
- Give each thread a count of how many ticks it ran, and show it in
threads. - Add a shell command
spinthat starts a thread counting for ever. Does the shell stay usable? Start three. - Change the time slice: switch only every second tick. What changes in the counts of the boot demonstration?
- Write a sleeping mutex: a thread that finds it locked blocks (a new
Wait::Lock) instead of spinning, andunlockwakes one waiter. Which lost wake-up do you have to avoid here?
The kernel now does several things at once – on one CPU. The reference kernel goes on to start the other CPUs, which needs the local APIC of chapter 12 once more.
14 – The other CPUs
Goal: wake the other cores of the machine and bring them into our kernel – through 16-bit real mode, 32-bit
protected mode and 64-bit long mode, the whole history of the x86 in one page of start code.
You end up with: a trampoline below 1 MiB, the INIT/STARTUP sequence sent through the local APIC, every CPU
with its own stack, GDT and TSS and the shared IDT, and run_on(cpu, job) that runs a closure on another CPU.
QEMU now has 4 CPUs (KERNEL_SMP changes it).
Code: course/14-smp/ (chapter 13
plus smp.rs, inter-processor interrupts in lapic.rs, a GDT and TSS per CPU in gdt.rs, the MADT's APIC IDs)
What changed: diff -ru course/13-threads course/14-smp (in the repository) shows every line this chapter adds.
Background: one CPU starts, the others wait
After power-on only one core runs, the bootstrap processor (BSP). Limine handed it to kmain, and everything so
far ran on it. The others, the application processors (APs), sit in a waiting state until their local APIC
receives two messages from another CPU – inter-processor interrupts (IPIs):
- INIT resets the core and lets it wait for the next one.
- STARTUP (SIPI) carries a page number
v. The core starts executing at physical addressv << 12– in 16-bit real mode, exactly like a PC of 1981: no paging, 1 MiB of address space, segments times 16.
So the start code must lie in the first megabyte, and it must climb on its own: real mode → protected mode (32 bit, a GDT, CR0.PE) → long mode (PAE paging, the EFER.LME bit, CR0.PG) → a jump into Rust. This code is called the trampoline. The MADT of chapter 12 already lists the CPUs; this chapter keeps their APIC IDs, not just their number.
What does a started AP share with the BSP, and what is its own? Shared: memory and the page tables (one CR3 for all – that is what makes it one machine), the kernel's code, the IDT. Its own: registers, stack, local APIC – and a TSS, as step 3 shows.
The scheduler of chapter 13 stays on the BSP in this chapter. The APs wait in hlt until run_on gives them a job;
one scheduler for all CPUs comes next.
Step 1: a frame below 1 MiB
The frame allocator of chapter 8 hands out the lowest free frame first, and the usable frames below 1 MiB are few.
So smp::reserve_frame takes one right after mem::init, before anything else can:
#![allow(unused)]
fn main() {
pub fn reserve_frame() {
    let frame = pmm::alloc_frame().expect("a free frame");
    assert!(frame.0 < MIB, "no free frame below 1 MiB for the trampoline");
}
Under QEMU it is 0x62000, right after the frame bitmap.
Step 2: the trampoline
The trampoline is assembly in global_asm!, assembled into the kernel at its high address and copied into the
low frame before use. It cannot know where it runs until it does, so it computes its own physical address from CS
(ebx = CS * 16) and reads its data relative to it. The assembler cannot use the difference of two labels as a
memory operand, so the few instructions that read the trampoline's data are written as bytes – for example
lgdt [ap_gdt_pointer]:
#![allow(unused)]
fn main() {
    // lgdt [ap_gdt_pointer]: 0F 01 /2 with a 16-bit displacement
    ".byte 0x0F, 0x01, 0x16",
    ".word ap_gdt_pointer - ap_trampoline",
}
The trampoline has a small GDT of its own (32-bit and 64-bit code and data). It switches on protected mode, PAE,
long mode and no-execute in EFER, and paging with our PML4 – the address smp::start filled in. Then it loads
a stack, the CPU's number and the address of ap_main from its data area and calls it.
One trap remains. The instruction that turns paging on is fetched at a physical address; the next one is fetched
through the page tables – at the same address, now a virtual one. Our page tables map the higher half, not
0x62000. So for the start, the trampoline's frame is also mapped at its own address:
#![allow(unused)]
fn main() {
    paging::map(frame.0, frame, Flags::CODE).expect("the trampoline's address is free in the lower half");
}
Flags::CODE has no no-execute bit – the AP runs code there. After the last AP is up, the mapping goes again.
Step 3: INIT, STARTUP, and a TSS per CPU
An IPI is sent through the local APIC's interrupt command register: the destination's APIC ID into its high half, then the kind of message into its low half – writing the low half sends it. Intel's recipe for one AP:
#![allow(unused)]
fn main() {
        lapic::send_init(apic_id);
        time::sleep_ms(10);
        lapic::send_startup(apic_id, page);
        if !wait_online(cpu, 10) {
            lapic::send_startup(apic_id, page);
}
The APs start one after another: they all run through the same trampoline, whose stack and CPU number are filled in anew for each.
In ap_main every AP loads a GDT and a TSS of its own, the shared IDT, and switches its local APIC on. Why not the
BSP's GDT? Loading a TSS with ltr marks it busy in its GDT descriptor, and the CPU refuses to load a busy TSS –
the second CPU would fail. Each also needs its own double fault stack: two CPUs on one IST stack would overwrite
each other's frames. gdt::init_other_cpu builds both on the heap.
Step 4: jobs for the other CPUs
An AP then waits in hlt for a job. Each CPU has a mailbox – a Mutex<Option<Job>>. run_on(cpu, job) puts a
closure into it and sends a wake-up IPI (vector 0xF0, whose handler only ends it), and the AP takes the job,
runs it and puts the result where run_on waits for it. The AP checks its mailbox with interrupts off and
sleeps with sti; hlt: sti takes effect only after the next instruction, so a wake-up that comes right after the
check still ends the hlt.
Two old rules now really matter. The heap and the console are used by several CPUs at once – their spin locks work across CPUs, which is what spin locks are for. And "interrupts off" no longer means "nobody else runs": on one CPU it did, which is all chapter 13's scheduler relies on. That is why it stays on the BSP for now, and why jobs on the APs must not touch it.
What the reference kernel (kernel/src/arch/x86_64/smp.rs)
does besides: up to 16 CPUs, an idle thread per CPU that the scheduler uses, a local APIC timer on every CPU,
SSE/FPU and syscalls switched on per CPU, and TLB shootdowns – when one CPU changes a mapping, the others must drop
their cached copy of it.
The tests
make test now runs 96 tests in the kernel; four are new:
every_cpu_of_the_madt_runs– as many CPUs online as the MADT lists;a_job_runs_on_the_cpu_it_was_sent_to– each CPU answers with its own number and APIC ID, has the TSS loaded, and a GDT at an address of its own; there is no CPU 8;the_heap_works_on_every_cpu– aVecbuilt and summed on each CPU;the_trampoline_is_below_1_mib_and_unmapped_again.
qemus_tables_describe_qemus_machine now wants the APIC IDs 0, 1, … for as many CPUs as there are. The test kernel
passed with KERNEL_SMP=1, 2 and 4, and 30 boots of the normal kernel did not hang once.
On the way, this chapter found a bug in chapter 13: about one boot in 20 hung after the Keyboard: line. The
scheduler was installed in steps with interrupts on, and a tick in between lost main (bug #28);
chapter 13 is fixed too.
Run it
cd course/14-smp
make run
After the thread lines of chapter 13:
SMP: 4 CPUs run; the others started at the trampoline at physical 0x62000
SMP: a job on each CPU asked it (number, APIC ID): [(0, 0), (1, 1), (2, 2), (3, 3)]
KERNEL_SMP=2 make run starts QEMU with two CPUs.
What can go wrong
Two of these mistakes end the whole machine, not just one CPU: a triple fault on any CPU resets them all, and
with -no-reboot QEMU quits – run-qemu.sh says QEMU ended by itself: the machine reset. QEMU's own log
(-d int,cpu_reset -D log.txt on its command line) shows what happened:
- No identity mapping: a page fault at
0x6205bwith error code0x10– an instruction fetch – right after themov cr0that turns paging on. The next instruction's address is not mapped. - The BSP's GDT on the APs: a general protection fault with error code
0x18– the TSS selector:ltrrefuses the TSS the BSP already marked busy. The AP has no IDT of ours yet, so the exception cannot be handled, and the next faults end in the triple fault. - The AP's local APIC left off: nothing resets, but the boot stops after the first
SMP:line. The wake-up IPI is never accepted, the AP sleeps on, andrun_onwaits for ever.
Experiments
- Start QEMU with
-smp 8, and withKERNEL_SMP=9– what doesstartdo with the ninth CPU? - Leave out the second STARTUP. Does QEMU need it? (Real hardware sometimes does.)
- Time how long the start of the APs takes. Where do the milliseconds go?
- Give
run_ona job that never ends. What does the CPU that sent it do now – and the shell?
The CPUs run, but only the BSP runs threads. The next chapter gives all of them to one scheduler – and with that, every lock and every "interrupts off" has to be thought through again.
15 – One scheduler for all CPUs
Goal: let every CPU run threads – one queue, one scheduler, as many CPUs as the machine has – and find out which
of the old certainties of chapter 13 no longer hold.
You end up with: a scheduler whose lock is held through every switch, a timer and an idle thread on every CPU,
waiting that cannot lose a wake-up sent from another CPU, and run_on jobs that run in an interrupt handler. The
end of part IV.
Code: course/15-scheduler/
(chapter 14 with a new task.rs, a timer per CPU in interrupts.rs, the APs joining the scheduler in smp.rs)
What changed: diff -ru course/14-smp course/15-scheduler (in the repository) shows every line this chapter adds.
Background: "interrupts off" was a lock – for one CPU
Chapter 13's scheduler touches its state with interrupts off, and on one CPU that was enough: nothing else runs while the timer cannot interrupt. Chapter 14 started three more CPUs and kept them away from the scheduler for exactly this reason. Now they take part, and three things break that worked before:
- The scheduler's data.
SCHEDULERwas always behind aspin::Mutex, but the lock was released before the switch. On one CPU nobody could take it in between. With four, another CPU can take the old thread from the queue while this CPU is still pushing its registers onto its stack – two CPUs, one stack. - Which thread is "current". There is a running thread per CPU now, and an idle thread per CPU.
- Waiting. "Check, then block" (chapter 13's
wait_for) has a gap: the event can happen on another CPU between the check and the block, and its wake-up finds a thread that is not blocked yet. The wake-up is lost; the thread sleeps until something else wakes it – maybe never.
Step 1: per-CPU state in one scheduler
The scheduler keeps, for every CPU, the thread it runs and its idle thread; a thread remembers the CPU it is on:
#![allow(unused)]
fn main() {
    /// The thread each CPU runs, and its idle thread (`None`: that CPU has not joined yet).
    current: [Option<Id>; MAX_CPUS],
    idle: [Option<Id>; MAX_CPUS],
}
on_cpu is set when a CPU switches to a thread and cleared only after it has switched away from it completely – so
"in the queue" and "still on a CPU" can be true at the same time for a moment, and the code must not mix them up.
The APs join in ap_main: after their GDT, IDT and local APIC (chapter 14) they start their own timer and turn the
code that runs there into their idle thread:
#![allow(unused)]
fn main() {
    lapic::init_local();
    interrupts::start_timer_here();
    ONLINE[cpu].store(true, Ordering::Release);
    task::join_cpu(cpu)
}
start_timer_here uses the count the BSP measured in chapter 12: all local APIC timers of a machine run from the
same clock. Every CPU's timer interrupt calls task::on_tick, but only one may count the time – otherwise four CPUs
would make the clock run four times as fast:
#![allow(unused)]
fn main() {
    // every CPU has a timer now, but the clock is counted once: by the BSP's
    if smp::cpu() == 0 {
        time::tick();
    }
}
Step 2: the lock stays held through the switch
schedule decides what runs next under the lock – and then does not release it:
#![allow(unused)]
fn main() {
    core::mem::forget(guard);
    unsafe { switch_context(old_rsp, new_rsp) };
    finish_switch();
}
}
forget drops the guard without unlocking. The thread that runs after switch_context – a thread coming back from
its own schedule, or a new one in thread_start – calls finish_switch, and only then is the old thread really
off this CPU:
#![allow(unused)]
fn main() {
fn finish_switch() {
    let cpu = smp::cpu();
    // Safety: the lock is held (by `schedule` on this CPU, which forgot its guard), so nobody else touches the data.
    let s = unsafe { &mut *SCHEDULER_DATA.load(Ordering::Relaxed) };
    let previous = PREVIOUS[cpu].load(Ordering::Relaxed);
    if let Some(thread) = s.threads.get_mut(&previous) {
        thread.on_cpu = None;
        // A thread that ended is only now off its stack: from here on `join` may return and `reap` may free it.
        if thread.state == State::Dead {
            s.wake(|wait| wait == Wait::Join(previous));
        }
    }
    unsafe { SCHEDULER.force_unlock() };
}
}
A thread that ended is a special case: until this moment its stack was still in use, so its joiners are woken only
now – exit just marks it dead. The lock is ours, but the guard that would let us reach the data is gone – so init keeps a raw pointer to the
scheduler, SCHEDULER_DATA, and force_unlock releases the lock by hand. Both are unsafe for a good reason: they
are correct only because every path into a thread goes through finish_switch exactly once.
Step 3: announce the wait, then check
wait_for now marks the thread blocked first and asks ready second:
#![allow(unused)]
fn main() {
            set_state(State::Blocked(wait));
            if let Some(value) = ready() {
                set_state(State::Running);
                return value;
            }
            schedule(); // returns when a wake-up made the thread run again - or found it still here
}
A wake-up from another CPU can now come at any point. Before ready – then ready sees the event. After it – then
the thread is blocked and the waker finds it. The waker must only not queue a thread that is still on a CPU – it
would run twice. So wake_one cancels the block instead:
#![allow(unused)]
fn main() {
        if thread.on_cpu.is_some() {
            thread.state = State::Running;
            return;
        }
}
schedule sees Running, keeps the thread on its CPU, and the loop asks ready again.
Step 4: waking idle CPUs, and jobs
A CPU with nothing to do halts in its idle thread. When a thread becomes ready – spawn, a wake-up – the scheduler
sends one idle CPU the wake-up interrupt of chapter 14 (kick_idle_cpu), and its idle thread looks at the queue.
run_on changes too. In chapter 14 the APs ran jobs in their wait loop; now an AP may be busy with a thread when a
job arrives – even with the thread that sent it, which may have moved there. So jobs run in the handler of the
wake-up interrupt, whatever the CPU is doing. That gives them the rules of interrupt handlers: no waiting, and no
lock that is ever taken with interrupts on.
The tests
make test now runs 100 tests in the kernel; these are new or changed:
every_cpu_has_an_idle_thread_that_is_never_queuedandonly_main_and_the_idle_threads_are_left;every_cpu_has_its_own_timer– every CPU's timer interrupt count grows during 50 ms;threads_run_on_every_cpu– as many spinning threads as CPUs; together they ran on all CPUs;no_wake_up_is_lost_between_cpus– two threads play ping-pong 2000 times through a counter, each waiting for its turn withwait_forand waking the other. One lost wake-up, and both wait for ever.the_scheduler_lock_is_free_after_a_switch– 100 yields and a short thread, and the lock is still usable.
Three old tests had to learn about other CPUs: a new thread no longer waits while main has interrupts off – an
idle CPU takes it at once; the thread that should be asleep may still be on its way there on another CPU; and
threads spawned for the stack test would end – and give their stacks back – before the frames were counted. They
now wait for a signal (Wait::Event). The first of them was found by CI, not here: on the runner an idle CPU was
quicker than on this machine.
To find such timing assumptions, the unit tests ran 8 more times, 4 of them with all host cores kept busy. That
found two more problems: join returned while the ended thread was still on its CPU, so its stack could not be
freed yet (bug #30) – and a timer test of chapter 12 whose window was too narrow for a busy machine
(bug #29).
Two counter-checks were run, 3 times each: with chapter 13's order in wait_for (check, then block), the ping-pong
test hangs every time; with the lock released before switch_context, the same. The chapter's test kernel passed
with KERNEL_SMP=1, 2 and 4, and the whole make test three times in a row.
Run it
cd course/15-scheduler
make run
After chapter 14's SMP: lines:
Scheduler: 4 threads that never yield, 100 ms - they ran on the CPUs [0, 1, 2, 3]
and in the shell, threads now says where each thread is:
   0  main     Running, on CPU 0
   1  idle     Ready
   2  idle     Running, on CPU 1
   3  idle     Running, on CPU 2
   4  idle     Running, on CPU 3
What can go wrong
- The lock released before the switch: another CPU runs a thread whose registers are only half saved. Here it showed as a hang in the ping-pong test; in a bigger kernel it is a crash somewhere far away.
- A path into a thread that skips
finish_switch: the lock stays held, and the next CPU that wants it spins for ever – every CPU, one after another. New threads start inthread_start, so it callsfinish_switchfirst. - "Ended" is not "off the CPU": a joiner that is woken when the thread is marked dead runs while the dead thread is still on its stack (bug #30) – fine for the result, too early for freeing the stack.
- "Check, then block": wake-ups get lost, rarely – which is why the ping-pong test plays 2000 rounds.
- Every CPU counting the time: each CPU adds its own 100 ticks a second, so with four CPUs the clock runs four times too fast and every sleep ends early.
- A check that assumed the BSP: writing this chapter, the double fault test failed – the handler compared its
stack with the BSP's double fault stack, but
mainhad moved to another CPU, which has its own.gdt:: on_double_fault_stacknow asks for the stack of the CPU it runs on.
Experiments
- Count how often each thread changes CPU (
on_cpudiffers from last time). Is moving between CPUs rare or common? What does it cost – which caches are cold on the new CPU? - Remove
kick_idle_cpu. Do threads still get run? How much later? - Run the ping-pong test with
KERNEL_SMP=1. Why can the oldwait_fornot lose a wake-up there?
The kernel can now do several things at the same time for real. Part V gives it something worth waiting for: a disk.
16 – PCI and a SATA disk
Goal: find the devices of the machine on the PCI bus, and read sectors from a SATA disk through its AHCI
controller – the first device that moves data into RAM by itself.
You end up with: a list of every PCI device at boot, a driver that asks the disk who it is and reads any
sector by DMA, and two shell commands, disk and read. The start of part V, storage.
Code: course/16-ahci/
(chapter 15 plus pci.rs, block.rs, ahci.rs, 32-bit ports in port.rs, a test disk from mkdisk.py)
What changed: diff -ru course/15-scheduler course/16-ahci (in the repository) shows every line this chapter adds.
Background: devices that find themselves, and DMA
The serial port, the PIC and the keyboard sit at fixed I/O ports that every PC has had since the 1980s. Newer devices do not: a machine has whatever cards are plugged in, so the kernel has to ask. That is what PCI is for. Every device has a 256-byte configuration space saying what it is (vendor, device, class) and where its registers are: the BARs, base address registers, hold physical addresses at which the device answers like memory.
A disk is an array of sectors of 512 bytes, numbered from 0 – the LBA, logical block address. The SATA controller of nearly every PC since 2005 speaks AHCI. It does not take data byte by byte through a port, as the serial port does. We write a command into RAM and set a bit; the controller reads the command, fetches the sectors from the disk and writes them into RAM itself – DMA, direct memory access. The CPU only waits until the controller says "done".
That has two consequences. The controller knows nothing about our page tables: every address we give it is physical. And it writes into RAM behind the back of the compiler, which must not assume that memory stays as it left it.
Step 1: the configuration space
Two I/O ports reach the configuration space: an address goes to 0xCF8, then the data comes from 0xCFC. Both are 32
bits wide, so port.rs gets outl and inl next to outb and inb:
#![allow(unused)]
fn main() {
/// Reads 32 bits from an I/O port.
pub unsafe fn inl(port: u16) -> u32 {
    let value: u32;
    unsafe {
        core::arch::asm!("in eax, dx", in("dx") port, out("eax") value, options(nomem, nostack, preserves_flags))
    };
    value
}
}
A device's place is bus, device and function; together with the offset of a double word they make the address:
#![allow(unused)]
fn main() {
    fn address(self, offset: u8) -> u32 {
        1 << 31
            | (self.bus as u32) << 16
            | (self.device as u32) << 11
            | (self.function as u32) << 8
            | (offset & 0xFC) as u32
    }
}
Reading is two port accesses – and with four CPUs since chapter 14, two CPUs could interleave theirs: CPU 1 writes its address, CPU 2 writes its own, CPU 1 reads CPU 2's data. So a lock holds the pair together:
#![allow(unused)]
fn main() {
    pub fn read(self, offset: u8) -> u32 {
        let _lock = CONFIG.lock();
        unsafe {
            outl(CONFIG_ADDRESS, self.address(offset));
            inl(CONFIG_DATA)
        }
    }
}
Step 2: finding every device
Where nothing is, nobody answers, and the read returns all ones – vendor 0xFFFF. So enumerate tries every place.
A device whose header type has bit 7 set has more than one function (QEMU's 00:1f is one: ISA bridge, SATA
controller and SMBus controller in one chip):
#![allow(unused)]
fn main() {
pub fn enumerate() -> Vec<Device> {
    let mut devices = Vec::new();
    for bus in 0..=255 {
        for device in 0..32 {
            let Some(first) = probe(Location {
                bus,
                device,
                function: 0,
            }) else {
                continue;
            };
            devices.push(first);
            let header_type = (first.location.read(HEADER_TYPE) >> 16) as u8;
            if header_type & 0x80 != 0 {
                devices.extend((1..8).filter_map(|function| probe(Location { bus, device, function })));
            }
        }
    }
    devices
}
}
8192 places, most of them empty – crude, but in QEMU it took 10 ms in three runs (one tick of our clock, which cannot measure finer). (Real kernels follow the bridges from bus 0 instead, or read the PCI Express area that the ACPI table MCFG describes.)
The AHCI controller is the device with class 0x01 (mass storage), subclass 0x06 (SATA), programming interface 0x01
(AHCI). Its registers are at the physical address in BAR5. Before it may use them – and before it may access RAM
itself – the command register needs two bits, memory space and bus master; enable_dma sets them.
Step 3: the controller and its ports
ahci::init finds the controller, maps its registers – uncached, like the APIC's in chapter 12 – and switches it to
AHCI mode:
#![allow(unused)]
fn main() {
    let device = pci::find(0x01, 0x06, 0x01).ok_or("no AHCI controller")?; // mass storage, SATA, AHCI
    device.enable_dma();
    let bar = device.memory_bar(5).ok_or("AHCI's BAR5 is not a memory BAR")?;
    // 0x100 bytes for the HBA, 0x80 for each of up to 32 ports: two pages
    let hba = paging::map_device(PhysAddr(bar)).map_err(|_| "cannot map the AHCI registers")?;
    paging::map_device(PhysAddr(bar + PAGE_SIZE)).map_err(|_| "cannot map the AHCI registers")?;
    write32(hba + HBA_GHC, read32(hba + HBA_GHC) | GHC_AHCI_ENABLE);
}
Then it looks at every port the controller has (register PI, "ports implemented"). A port is in use when its SATA
status says a device is there and talking (DET = 3); its signature says what kind: 0x101 is a disk, 0xEB140101 an
ATAPI device – a CD drive. QEMU's -cdrom, our boot disk, is one.
A disk port gets one zeroed frame for its three structures – the command list at offset 0, the area where the disk
posts its answers at 1024, the command table at 2048 – and a second frame for the data. Disk::start stops the
port (the firmware may have left it running with its own command list), writes the physical addresses of our
structures into its registers, starts it again and sends the first command: IDENTIFY DEVICE, which answers with 512
bytes about the disk – among them its model name (words 27–46) and its size in sectors (words 100–103).
Step 4: one command
A command is three things in RAM: a header in slot 0 of the command list (how long the command is, how many buffers, where the table is), the command FIS in the table (the ATA command, the LBA in six bytes, the number of sectors) and one PRD, which says "the data goes to this physical address, this many bytes". Then:
#![allow(unused)]
fn main() {
        // Everything above must be in memory before the controller is told to fetch it
        fence(Ordering::SeqCst);
        self.set_reg(PORT_IS, u32::MAX);
        self.set_reg(PORT_CI, 1);
        let failed = || self.reg(PORT_IS) & IS_TASK_FILE_ERROR != 0;
        wait_until(|| self.reg(PORT_CI) & 1 == 0 || failed())?;
        // ... and what the controller wrote must not be read before it said "done"
        fence(Ordering::SeqCst);
        if failed() || self.reg(PORT_TFD) & TFD_ERROR != 0 {
            self.set_reg(PORT_IS, u32::MAX);
            return Err(BlockError::Device);
        }
        Ok(())
    }
}
Setting bit 0 of CI ("command issue") hands slot 0 to the controller; it clears the bit when the command is done. The two fences are for the compiler: it knows nothing about the controller, and without them it may move a write to the command table after the write to CI, or a read of the data before the wait. x86 itself keeps the order of these accesses, but the fence costs nothing next to a disk access.
wait_until polls – the CPU spins until the bit clears, for at most a second (time::uptime_ms, so the timer
must run). In QEMU a command takes microseconds; chapter 19 lets the controller send an interrupt instead, so that
the CPU can run other threads meanwhile.
Step 5: reading sectors
The data frame is the bounce buffer: the controller needs a physically contiguous buffer, and a buffer on the heap is contiguous only within a page. So one command moves at most 8 sectors, and a longer read is several commands, each copied out of the bounce buffer:
#![allow(unused)]
fn main() {
    fn read(&mut self, lba: u64, buf: &mut [u8]) -> Result<(), BlockError> {
        block::check_request(self.sectors, lba, buf.len())?;
        for (i, chunk) in buf.chunks_mut(SECTORS_PER_COMMAND * SECTOR_SIZE).enumerate() {
            let first = lba + (i * SECTORS_PER_COMMAND) as u64;
            self.command(ATA_READ_DMA_EXT, first, (chunk.len() / SECTOR_SIZE) as u16, chunk.len())?;
            chunk.copy_from_slice(self.bounce(chunk.len()));
        }
        Ok(())
    }
}
read belongs to the trait BlockDevice in block.rs: "something with sectors". The file system of the next
chapter will only know the trait, so its tests can use a disk in RAM. check_request refuses a buffer that is not
whole sectors, and sectors past the end – with checked_add, so that a huge LBA cannot wrap around to a small one.
Step 6: a disk for QEMU, and wiring it in
mkdisk.py makes the test disk: 1 MiB, 2048 sectors, and every sector starts with its own number – "YAK test
disk, sector 5" – and is filled up with the byte n % 251, so a test can tell every sector from its neighbours at
both ends. run-qemu.sh makes it fresh before every start and gives it to QEMU as a SATA disk on port 0:
python3 -I mkdisk.py build/disk.img
-drive file=build/disk.img,format=raw,if=none,id=disk -device ide-hd,drive=disk,bus=ide.0)
(ide-hd and ide.0 are QEMU's names for "a hard disk on the first port of the q35's controller" – which is an
AHCI controller, whatever the name says.)
main.rs declares the new modules (mod ahci;, mod block;, mod pci;), and kmain calls show_disk() after
show_scheduler(): it prints every PCI device, calls ahci::init() and reads sector 0. The test kernel calls
ahci::init() before the tests, so that they find the disk in ahci::DISK:
#![allow(unused)]
fn main() {
    ahci::init().expect("the AHCI controller and its disk");
}
The shell gets two commands: disk (model and size) and read <sector>, which prints the first 64 bytes in hex and
as text:
#![allow(unused)] fn main() { fn read(args: &[String], out: &mut dyn Write) -> Result<(), String> { let [lba] = args else { return Err(String::from("usage: read <sector>")); }; let lba: u64 = lba.parse().map_err(|_| alloc::format!("not a number: {}", lba))?; let mut sector = [0u8; SECTOR_SIZE]; let mut guard = ahci::DISK.lock(); let disk = guard.as_mut().ok_or("no SATA disk")?; disk.read(lba, &mut sector) .map_err(|e| alloc::format!("sector {}: {:?}", lba, e))?; drop(guard); hex_dump(§or[..64], out); Ok(()) } }
The tests
make test now runs 111 tests in the kernel; these are new:
the_q35_host_bridge_is_device_zero,the_sata_controller_is_found(vendor 8086, device 2922 at 00:1f.2, BAR5 a page-aligned memory address),nothing_answers_where_there_is_no_device,dma_is_on_after_init;the_disk_says_who_it_is– IDENTIFY reports "QEMU HARDDISK" and 2048 sectors, and the CD drive is on a port too;one_sector_is_read(the first and the last sector),a_long_read_takes_several_commands(20 sectors: 8 + 8 + 4, each sector checked at its start and its end),bad_requests_are_refused,init_runs_once;requests_are_checked(block.rs) andread_shows_a_sector_in_hex_and_as_text(the shell).
The boot check types disk and read 5 and looks for their output.
Run it
cd course/16-ahci
make run
After the scheduler line:
PCI 00:00.0  8086:29c0  host bridge
PCI 00:01.0  1234:1111  display controller
PCI 00:02.0  8086:10d3  network controller
PCI 00:1f.0  8086:2918  ISA bridge
PCI 00:1f.2  8086:2922  SATA controller
PCI 00:1f.3  8086:2930  SMBus controller
AHCI 1.0 at 00:1f.2, ports in use: 0 SataDisk, 2 Atapi
Disk: QEMU HARDDISK on port 0, 2048 sectors (1024 KiB); sector 0 says: YAK test disk, sector 0
and in the shell:
yak> read 5
0000  59 41 4b 20 74 65 73 74 20 64 69 73 6b 2c 20 73  |YAK test disk, s|
0010  65 63 74 6f 72 20 35 0a 05 05 05 05 05 05 05 05  |ector 5.........|
0020  05 05 05 05 05 05 05 05 05 05 05 05 05 05 05 05  |................|
0030  05 05 05 05 05 05 05 05 05 05 05 05 05 05 05 05  |................|
The network card at 00:02.0 waits for part VII.
What can go wrong
- No bus mastering: the controller may not touch RAM, and the first command never finishes. I cleared the bit on
purpose: IDENTIFY timed out and the test kernel stopped at
ahci::init. Leaving the bit out ofenable_dma, on the other hand, changed nothing here – the firmware had set it already (the command register read 0x107 beforeenable_dma), because SeaBIOS reads the boot CD through this very controller. On another machine, or with another firmware, it may not. - A virtual address in a register or a PRD: the controller reads from that number as a physical address –
somewhere else entirely. Every address handed over is
frame.0, neverto_virt(). - Initializing a port twice: the port gets a new command list while the old
Diskstill fills in the old one, which the controller no longer reads – it runs stale commands, and the data lands in the wrong buffer. In the reference kernel a test did exactly this, and reading sector 0 returned the disk's IDENTIFY data instead (bug #3).initrefuses a second run, andinit_runs_oncechecks it. - Holding
ahci::DISKwhile waiting: the lock is a spin lock; another thread that wants the disk spins until the command is done. Fine for microseconds in QEMU – chapter 19 replaces the polling. - The timer is not running:
wait_untilmeasures its timeout withtime::uptime_ms. With interrupts off, a disk that never answers would make it spin for ever.
Experiments
- Print
d.vendorandd.deviceof every device and look them up in the PCI ID database (pci-ids.ucw.cz). What is 1234:1111? - Attach a second disk (another
-drivewithbus=ide.1). On which port does it appear? Makeinitkeep all disks. - Read sector 0 of the boot CD on port 2. Why does it fail? (ATAPI devices take SCSI commands wrapped in an ATA PACKET command, not READ DMA EXT.)
- Time
readof 2048 sectors withtime::uptime_ms. How much faster is it with 16 sectors per command (a bounce buffer of two contiguous frames)?
Next, chapter 17 turns these numbered sectors into files: FAT32.
17 – Reading FAT32
Goal: turn the numbered sectors of chapter 16 into files and directories – by reading the FAT32 format, which
every operating system understands and which Linux tools write for our tests.
You end up with: a FAT32 volume mounted at boot, lookup, read_dir and read_file with long file names, and
ls and cat in the shell. A volume whose numbers are broken gives an error, never a hang.
Code: course/17-fat32/
(chapter 16 plus fat32.rs and fs.rs, a test disk made by mkdisk.sh)
What changed: diff -ru course/16-ahci course/17-fat32 (in the repository) shows every line this chapter adds.
Background: a linked list on a disk
A file system answers one question: which sectors belong to /docs/notes.txt, in which order? FAT, from 1977,
answers it with a table. The volume is cut into clusters – a few sectors each, here one – numbered from 2. The
File Allocation Table has one 32-bit entry per cluster: 0 means free, 0x0FFFFFF8 or more means "the file ends
here", any other number is the next cluster of the same file. A file is a linked list; its directory entry holds
the first cluster and the size in bytes. A directory is a file too, a list of 32-byte entries.
The layout is fixed by Microsoft's specification, "FAT: General Overview of On-Disk Format" (version 1.03), and starts at sector 0:
sector 0         boot sector: the BPB says how big everything is
sectors 1..31    reserved (FSInfo, a copy of the boot sector)
sectors 32..     FAT #1, then FAT #2 (a copy)
then             the data area: cluster 2, cluster 3, ...  (cluster 2 is the root directory here)
FAT is old and simple, and that is the point: Linux formats a disk image with mkfs.fat, copies files onto it
with mtools, and checks it with fsck.fat – so our reader is tested against what other systems write.
Step 1: a disk with known files
mkdisk.sh replaces chapter 16's mkdisk.py. It makes a 64 MiB FAT32 volume – the whole disk, no partition table,
one sector per cluster – and copies files onto it:
mkfs.fat -F 32 -s 1 -n YAKDISK -C "$IMG" $((64 * 1024)) >/dev/null
hello.txt, a long file name.txt, an empty file, big.bin (100 000 bytes, byte i = i % 253, so 196
clusters), docs/notes.txt, docs/deeper/end.txt, and a directory many/ with 40 files whose long names do not
fit into one cluster of the directory. fsck.fat says about it: "50 files, 251/129022 clusters". From this chapter
on, the host needs dosfstools and mtools; the course's CI job installs them.
Step 2: the boot sector
FatFs::mount reads sector 0 and takes the numbers it needs from the BPB: bytes per sector (offset 11), sectors per
cluster (13), reserved sectors (14), number of FATs (16), total sectors (32), sectors per FAT (36), the root
directory's first cluster (44), the label (71). Everything else follows from them – the data area starts after the
reserved sectors and every FAT, and the number of clusters is what fits after it.
These numbers come from a disk, so mount does not trust them: a sector size other than 512, zeros where sizes
belong, a volume bigger than the disk, a FAT too small for its clusters, a root directory outside the volume – each
is an error. The test disk has 129 022 clusters, the number fsck.fat printed.
Step 3: following a chain
The FAT entry of cluster c is the 4 bytes at offset 4c of the FAT – one sector read:
#![allow(unused)] fn main() { fn next(&mut self, cluster: u32) -> Result<u32> { let offset = cluster as u64 * 4; let mut sector = [0u8; SECTOR_SIZE]; self.disk .read(self.fat_start + offset / SECTOR_SIZE as u64, &mut sector)?; Ok(u32_at(§or, (offset % SECTOR_SIZE as u64) as usize) & FAT_MASK) } }
(The top 4 bits of an entry are reserved, hence FAT_MASK. The name FAT32 promises 32 bits; it has 28.)
A chain read from a disk can be wrong – point outside the volume, or back to a cluster it has passed, and then a loop would follow it for ever. A chain can never be longer than the volume has clusters, so that is the limit:
#![allow(unused)]
fn main() {
    fn chain(&mut self, first: u32) -> Result<Vec<u32>> {
        let mut chain = Vec::new();
        if first == 0 {
            return Ok(chain); // an empty file has no cluster at all
        }
        let mut cluster = first;
        loop {
            if !self.valid(cluster) {
                return Err(FsError::Corrupt("a cluster chain that leaves the volume"));
            }
            if chain.len() == self.clusters as usize {
                return Err(FsError::Corrupt("a cluster chain that runs in a circle"));
            }
            chain.push(cluster);
            match self.next(cluster)? {
                next if next >= END_OF_CHAIN => return Ok(chain),
                next => cluster = next,
            }
        }
    }
}
Step 4: directory entries and their names
An entry has the 8.3 name in bytes 0–10 (8 for the name, 3 for the extension, filled with spaces), attributes in byte 11 (0x10: a directory, 0x08: the volume label), the first cluster in two halves (bytes 20 and 26) and the size (28). A first byte 0xE5 marks a deleted entry, 0 the end of the directory.
Two things make names more than 11 bytes. Case: "hello.txt" is stored as HELLO TXT; byte 12 says "base
name and extension are lower case" (0x08 and 0x10, set by Windows NT and by mtools – a short name has no other
place for it):
#![allow(unused)]
fn main() {
fn short_name(raw: &[u8], case: u8) -> String {
    let part = |bytes: &[u8], lower: bool| {
        let text = String::from_utf8_lossy(bytes);
        let text = text.trim_end();
        if lower {
            text.to_ascii_lowercase()
        } else {
            String::from(text)
        }
    };
    let mut name = part(&raw[..8], case & LOWER_CASE_BASE != 0);
    let extension = part(&raw[8..11], case & LOWER_CASE_EXT != 0);
    if !extension.is_empty() {
        name.push('.');
        name.push_str(&extension);
    }
    name
}
}
Long names (VFAT, Windows 95): "a long file name.txt" gets an 8.3 alias, ALONGF~1.TXT, and before it extra
entries with the attributes 0x0F – read-only, hidden, system and volume label, a combination no old system
expected, so they skipped these entries. Each holds 13 UTF-16 characters at scattered offsets, a number (the piece
with the highest number comes first on the disk, marked with 0x40) and a checksum of the 8.3 name:
#![allow(unused)]
fn main() {
fn checksum(raw: &[u8]) -> u8 {
    raw[..11]
        .iter()
        .fold(0u8, |sum, &byte| sum.rotate_right(1).wrapping_add(byte))
}
}
The checksum protects against an old system that deleted or renamed the 8.3 entry and left the pieces behind: a long name counts only if it matches the 8.3 entry that follows it. The loop collects the pieces by their number:
#![allow(unused)]
fn main() {
                if attributes & ATTR_LONG_NAME == ATTR_LONG_NAME {
                    // the pieces come last one first: the first piece on the disk says how many there are
                    let number = (raw[0] & 0x1F) as usize;
                    if raw[0] & LAST_LONG_NAME_PIECE != 0 {
                        pieces = vec![[0xFFFF; 13]; number];
                        expected = raw[13];
                    }
                    if number == 0 || number > pieces.len() || raw[13] != expected {
                        pieces.clear(); // a piece without the others: ignore the long name
                        continue;
                    }
                    for (i, &offset) in LONG_NAME_CHARS.iter().enumerate() {
                        pieces[number - 1][i] = u16_at(raw, offset);
                    }
                    continue;
                }
}
and at the 8.3 entry decodes them, if the checksum fits – the name ends at a 0 or at the 0xFFFF padding:
#![allow(unused)]
fn main() {
                // the long name counts only if its checksum matches this 8.3 name - else it belonged to a deleted one
                let name = if !long.is_empty() && checksum(raw) == expected {
                    let units = long.iter().flatten().copied().take_while(|&u| u != 0 && u != 0xFFFF);
                    char::decode_utf16(units).map(|c| c.unwrap_or('?')).collect()
                } else {
                    short_name(&raw[..11], raw[12])
                };
}
Step 5: paths and files
lookup starts at the root directory and looks for each part of the path in turn – without regard to case, as FAT
does: /HELLO.TXT is /hello.txt. read_file follows the file's chain and takes size bytes from it; the last
cluster is only partly used:
#![allow(unused)]
fn main() {
    pub fn read_file(&mut self, path: &str) -> Result<Vec<u8>> {
        let file = self.lookup(path)?;
        if file.is_dir {
            return Err(FsError::IsADirectory);
        }
        let size = file.size as usize;
        let mut data = Vec::with_capacity(size);
        let mut buf = vec![0u8; self.cluster_size()];
        for cluster in self.chain(file.cluster)? {
            if data.len() == size {
                break; // a chain longer than the file: the rest is not ours to read
            }
            self.read_cluster(cluster, &mut buf)?;
            let take = (size - data.len()).min(buf.len());
            data.extend_from_slice(&buf[..take]);
        }
        if data.len() < size {
            return Err(FsError::Corrupt("a file whose chain is shorter than its size"));
        }
        Ok(data)
    }
}
Step 6: wiring it in
FatFs works on any BlockDevice and owns it. The kernel's one is fs::SystemDisk, which takes the lock of
ahci::DISK for each access – so the disk stays where chapter 16 put it, and read in the shell still works:
#![allow(unused)]
fn main() {
impl BlockDevice for SystemDisk {
    fn sector_count(&self) -> u64 {
        ahci::DISK.lock().as_ref().map_or(0, |disk| disk.sector_count())
    }

    fn read(&mut self, lba: u64, buf: &mut [u8]) -> Result<(), BlockError> {
        ahci::DISK.lock().as_mut().ok_or(BlockError::Device)?.read(lba, buf)
    }
}
}
fs::mount() puts the volume into fs::FS. show_disk in main.rs calls it after ahci::init() and prints the
volume, the root directory and /hello.txt; the test kernel mounts it before the tests:
#![allow(unused)]
fn main() {
    fs::mount().expect("a FAT32 volume on the disk");
}
The shell gets ls [dir] and cat <file> (shell.rs); without a current directory yet, a path without a leading
/ starts at the root. run-qemu.sh runs ./mkdisk.sh build/disk.img instead of mkdisk.py, and the AHCI tests
of chapter 16 now check the boot sector instead of numbered sectors.
The tests
make test runs 122 tests in the kernel; new:
the_boot_sector_is_read(label, cluster size, 129 022 clusters asfsck.fatcounts them);the_root_directory_lists_short_long_and_lower_case_names,names_are_found_in_any_case,the_long_name_checksum(whatchecksumcomputes is what mtools wrote);files_are_read(three levels deep, and the empty file),a_big_file_follows_its_chain(all 100 000 bytes checked),a_directory_can_span_clusters(many/: more than one cluster, 40 entries);wrong_paths_are_errors,a_disk_without_fat32_is_refused,a_chain_in_a_circle_is_an_error_not_a_hang– the last two mount the test disk with a few sectors replaced in RAM (Patched): a zeroed boot sector, and a FAT entry ofbig.binpointing back to its first cluster;ls_and_cat_show_the_disk(the shell).
The boot check types ls and cat docs/notes.txt.
Run it
cd course/17-fat32
make run
After the PCI and AHCI lines:
Disk: QEMU HARDDISK on port 0, 131072 sectors (64 MiB)
FAT32: volume YAKDISK, 129022 clusters of 512 bytes
FAT32: / holds hello.txt, a long file name.txt, empty.txt, big.bin, docs/, many/
FAT32: /hello.txt says: Hello from the disk!
and in the shell:
yak> ls
      21  hello.txt
      38  a long file name.txt
       0  empty.txt
  100000  big.bin
   <dir>  docs/
   <dir>  many/
yak> cat docs/notes.txt
Notes, one directory down.
What can go wrong
- Trusting the disk: a FAT entry that points back makes a naive loop run for ever – on a disk that came from
somewhere else, or one a crash left half written. The chain limit turns it into an error. Without it, the test
with the circular chain did not hang for ever here but ended worse: the
Vecof clusters grew until the heap was full, and the kernel panicked on a failed allocation. - The 4 reserved bits: an entry read without
FAT_MASKcan look like a huge cluster number. - Clusters count from 2: cluster 2 is the first one of the data area. An off-by-two reads the wrong directory – and it may even look like one.
- Lower case without byte 12: mtools stored
hello.txtasHELLO TXTwith the case flags, not with a long name. A reader that ignores byte 12 showsHELLO.TXT– still found, because names compare without case, but not what was written. - The order of a directory: entries come in the order they were made, not sorted –
deeper/was made beforenotes.txtwas copied, sols docsshows it first. My first version of the shell test expected the other order. - Slow by design: every FAT entry is one sector read, and
cat big.binreads the same few FAT sectors 196 times. Chapter 19 puts a block cache in between.
Experiments
- Run
fsck.fat -v build/disk.imgandmdir -i build/disk.img -/ ::/on the host and compare withls. - Make a file with a name of more than 26 characters (three long name pieces) and
lsit. Then one with a name in Greek or with an emoji: what does UTF-16 do with characters beyond U+FFFF? - Delete a file on the host (
mdel -i build/disk.img ::/hello.txt) and boot withoutmkdisk.shmaking the disk anew.readthe root directory's sector: where is the first byte 0xE5, and what happened to the long name pieces of a deleted long name? - Keep the last FAT sector in
FatFs(a one-sector cache). How many disk commands doescat big.binsave?
Next, chapter 18 writes: new files, appended data, deleted files – and fsck.fat must still be happy.
18 – Writing FAT32
Goal: create, change, append to and remove files and directories on the FAT32 volume – so that afterwards
fsck.fat finds nothing wrong and the Linux tools read exactly what the kernel wrote.
You end up with: WRITE DMA EXT and FLUSH in the AHCI driver; free clusters counted and allocated; write_file,
append, create_dir and remove; write, append, mkdir and rm in the shell; and a make test that hands the
disk to fsck.fat and mtools after QEMU has ended.
Code: course/18-fat32-write/
(chapter 17 plus writing in ahci.rs, block.rs, fs.rs and fat32.rs; check-disk.sh)
What changed: diff -ru course/17-fat32 course/18-fat32-write (in the repository) shows every line this chapter
adds.
Background: one change is several writes
Writing a new file touches four places: the clusters with the data, their entries in the FAT, the same entries in the second FAT, and an entry in the directory. Each is one write to the disk, and the machine can stop between any two of them. A file system cannot make that impossible – but it can choose the order, so that whatever has been written so far leaves a volume that is still consistent, at worst with clusters nobody uses:
- data into free clusters,
- the chain in the FAT (all copies),
- the directory entry that points to it,
- the free count in the FSInfo sector, and a FLUSH, so that the disk's own cache is empty too.
Stopped after 1 or 2: the clusters are lost – used in the FAT, but by no file; fsck.fat gives them back. Stopped
after 3: everything is there. The reverse order would be worse: an entry pointing to clusters that are still free
and may be given to another file. Replacing a file follows the same rule – the new data, then the entry, then the
old clusters are freed.
How well this holds against real power loss is a topic of its own. The reference kernel tests it with a disk that
fails on purpose and tears a write in half (FaultyDisk in
kernel/src/drivers/block.rs,
milestone M53): without a journal, FAT32 can still be left with lost clusters or a chain longer than its file –
fsck.fat repairs both. This chapter keeps to the order and checks the result with fsck.fat.
Step 1: writing sectors
The AHCI command of chapter 16 learns the other direction. Bit 6 of the command header ("W") says the data goes to the disk:
#![allow(unused)]
fn main() {
            let direction = if to_disk { 1 << 6 } else { 0 };
            write_volatile(header, 5 | direction | prds << 16);
}
write copies each piece of up to 8 sectors into the bounce buffer and sends WRITE DMA EXT (0x35); flush sends
FLUSH CACHE EXT (0xEA), which returns when the disk has its cache on the medium. BlockDevice gets both as methods,
and fs::SystemDisk passes them on to ahci::DISK.
Step 2: free clusters
At mount, count_free reads the whole FAT – 8 sectors per command – and counts the entries that are 0. The FSInfo
sector holds such a count too, but the specification calls it a hint: after a crash it may be wrong, so we count
ourselves and only write it. On this chapter's test disk the count is 128 769 – 129 022 clusters minus the
253 that fsck.fat reports as used.
A FAT entry is changed in every copy of the FAT, keeping the 4 reserved bits:
#![allow(unused)]
fn main() {
    fn set(&mut self, cluster: u32, value: u32) -> Result<()> {
        let offset = cluster as u64 * 4;
        let sector = offset / SECTOR_SIZE as u64;
        let at = (offset % SECTOR_SIZE as u64) as usize;
        let mut data = [0u8; SECTOR_SIZE];
        self.disk.read(self.fat_start + sector, &mut data)?;
        let old = u32_at(&data, at);
        put_u32(&mut data, at, (old & !FAT_MASK) | (value & FAT_MASK));
        for copy in 0..self.fats {
            self.disk.write(self.fat_start + copy * self.fat_size + sector, &data)?;
        }
        Ok(())
    }
}
allocate refuses at once when the count is too small – before anything is written – and otherwise searches from
next_free for entries that are 0. It links the clusters it found back to front, so the chain is complete before
anything points to it, and only then hangs it onto after (the last cluster of a file that grows):
#![allow(unused)]
fn main() {
        for (i, &c) in found.iter().enumerate().rev() {
            self.set(c, found.get(i + 1).copied().unwrap_or(END_MARK))?;
        }
        if let Some(last) = after {
            self.set(last, found[0])?;
        }
}
Step 3: directory entries
entries (chapter 17) now also remembers where each entry is: its slots – the long name pieces and the 8.3 entry
– and its 8.3 name as stored. free_slot finds a deleted or unused entry in a directory; when every cluster is full,
the directory grows by one cluster of zeros (all "end of directory").
Names: this chapter writes 8.3 names only. short_name_for turns "notes.txt" into NOTES TXT with both
lower-case flags; a name that needs more – longer than 8 + 3, mixed case like "ReadMe", spaces – is BadName.
(Writing long names means creating a unique alias like ALONGF~1 and the pieces with their checksum: an
experiment below.) One trap: a file with a long name has an 8.3 name too. prepare refuses a new name that is
the alias of an existing file, or the directory would hold the same 8.3 name twice.
Step 4: the operations
Each public operation ends with sync: the free count into the FSInfo sector, then FLUSH. When it returns, the
change is on the disk.
#![allow(unused)]
fn main() {
    pub fn write_file(&mut self, path: &str, data: &[u8]) -> Result<()> {
        let size = u32::try_from(data.len()).map_err(|_| FsError::NoSpace)?;
        match self.lookup(path) {
            Ok(old) if old.is_dir => return Err(FsError::IsADirectory),
            Ok(old) => {
                // new data first, then the entry points to it, then the old clusters are freed
                let first = self.store(data, None)?;
                let slot = *old.slots.last().expect("a file has an entry");
                self.write_slot(slot, |e| {
                    put_u16(e, 20, (first >> 16) as u16);
                    put_u16(e, 26, first as u16);
                    put_u32(e, 28, size);
                })?;
                self.free_chain(old.cluster)?;
            }
            Err(FsError::NotFound) => {
                let (raw, case, dir) = self.prepare(path)?;
                let first = self.store(data, None)?;
                let slot = self.free_slot(dir)?;
                self.write_slot(slot, |e| {
                    e.copy_from_slice(&entry_bytes(&raw, case, ATTR_ARCHIVE, first, size))
                })?;
            }
            Err(other) => return Err(other),
        }
        self.sync()
    }
}
append fills the free end of the file's last cluster first and hangs new clusters behind it for the rest.
create_dir writes a cluster with "." (the directory itself) and ".." (its parent – 0 when that is the root, as
the specification wants) before the entry that makes it visible. remove deletes the entry first, then frees the
clusters – and deletes every slot of the entry, the long name pieces included:
#![allow(unused)]
fn main() {
    pub fn remove(&mut self, path: &str) -> Result<()> {
        split(path)?; // not "/"
        let entry = self.lookup(path)?;
        if entry.is_dir && !self.entries(entry.cluster)?.is_empty() {
            return Err(FsError::NotEmpty);
        }
        for &slot in &entry.slots {
            self.write_slot(slot, |e| e[0] = ENTRY_DELETED)?;
        }
        self.free_chain(entry.cluster)?;
        self.sync()
    }
}
Dates: the kernel has no clock that knows the date yet, so every entry says 1980-01-01, the first day FAT can store.
Step 5: the shell, and checking from the outside
write <file> [words] makes a file of the words (and a newline), append adds them, mkdir and rm do what they
say. mkdisk.sh adds a directory trash/ with one long-named file for the removal test.
The strongest test is not inside the kernel. check-disk.sh runs after QEMU has ended, on the disk image the kernel
wrote: fsck.fat -n (look, change nothing) must find no problem, and mtype must return byte for byte what the
kernel wrote:
if ! fsck.fat -n "$IMG" > build/fsck.log 2>&1; then
make test runs it twice: after the unit tests (which leave /kept.txt and a 100 000-byte /keptdir/big.bin for
it), and after the boot check, which types write hi.txt hello disk, append hi.txt and more and cat hi.txt.
The tests
make test runs 132 tests in the kernel; new:
a_new_file_is_written_and_read_back(also by a second, fresh mount),replacing_a_file_gives_its_clusters_back(6 clusters → 1 → none, the free count follows),append_fills_the_last_cluster_then_grows;directories_are_made_and_grow(20 files: the directory grows to 2 clusters; a directory in it),removing_frees_clusters_and_the_name(also a long-named file made by mtools; a non-empty directory is refused);names_and_paths_are_checked(long, mixed-case and too long names, missing parents, the hidden alias),a_full_volume_is_refused_before_anything_is_written,the_free_count_stays_exact(the running count equals a fresh count of the FAT);write_append_mkdir_and_rm(the shell), andfiles_for_the_host_to_check.
Then check-disk.sh: fsck.fat clean, and mtools reads /kept.txt, /keptdir/big.bin and /hi.txt as written.
Three counter-checks, each run once, each caught by check-disk.sh:
setwriting only the first FAT: "FATs differ but appear to be intact."removedeleting only the 8.3 entry: "Orphaned long file name part "to be removed.txt"".- The writing tests each mounting a
FatFsof their own (my first version): "Free cluster summary wrong (128769 vs. really 128542)". Two mounts of one disk each keep their own free count; whichever writes the FSInfo sector last writes a wrong one. The tests now use the volume the kernel mounted at boot.
Run it
cd course/18-fat32-write
make run
and in the shell:
yak> mkdir notes
yak> write notes/todo.txt buy milk
yak> append notes/todo.txt write chapter 19
yak> cat notes/todo.txt
buy milk
write chapter 19
yak> rm notes
rm: /notes: NotEmpty
After QEMU has ended, the host reads the same: MTOOLS_SKIP_CHECK=1 mtype -i build/disk.img ::/notes/todo.txt.
What can go wrong
- The wrong order: an entry written before its clusters are linked points into free space; a later file gets the same clusters, and two files share data. The order of step 4 avoids it.
- One FAT only: other systems compare the copies –
fsck.fatnoticed at once. - Long name pieces left behind: they belong to no entry any more;
fsck.fatcalls them orphaned. - Two mounts of one disk: each believes its own free count – and its own idea of what is free. Here it only made the FSInfo count wrong (allocation always reads the FAT itself); a kernel that kept a free-cluster bitmap in memory would hand the same cluster to two files.
- Tests that depend on each other: the tests do not run in the order of the file but sorted by their names
(that is how the compiler hands them to the runner). My first removal
test deleted a file that a read test of chapter 17 expected – and a test that compared the whole root directory
saw the files of the writing tests. Each test now has its own files, and the read test checks only what
mkdisk.shmade. - A directory that grows: a new entry may need a cluster for the directory itself; a test that expects the free count back after write + remove has to count after the write.
Experiments
- Stop QEMU (
quitin its monitor) betweenstoreandwrite_slot– e.g. with asleepin between – and runfsck.fat -non the image. What does it report, and why is the file system still usable? - Write long names: generate
BASIS~N.EXTaliases (counting N up until no entry has it), the pieces with the checksum of chapter 17, and write them in front of the 8.3 entry. count_freereads 1009 FAT sectors at mount. How long does it take? Would trusting the FSInfo count be worth the risk?- Let
write_filefail half way on purpose (return an error afterstore). Which clusters are lost, and what doesfsck.fat -nsay about them?
Next, chapter 19 makes the disk faster and the CPU free: a block cache, and the disk's interrupt instead of polling.
19 – A block cache, and the disk's interrupt
Goal: stop doing work twice and stop waiting actively. The file system reads the same FAT sectors again and
again, and the CPU spins while the disk works. A cache in RAM answers the repeats; an interrupt tells the kernel
when a command is done, so the waiting thread can sleep.
You end up with: a write-through sector cache with least-recently-used replacement under the file system;
message signaled interrupts (MSI) from the SATA controller; disk commands that wait in task::wait_for – and a
count of what it saves. The end of part V.
Code: course/19-disk-irq/
(chapter 18 plus BlockCache in block.rs, MSI in pci.rs, the interrupt in ahci.rs and interrupts.rs)
What changed: diff -ru course/18-fat32-write course/19-disk-irq (in the repository) shows every line this
chapter adds.
Background: measure first
"The disk is slow, add a cache" is the obvious idea, and the reference kernel found out it was only half true
(docs/LEARN.md, M32): QEMU's disk answers in microseconds, and most of the time went into asking it the same
things again. So this chapter counts first. Reading /big.bin (196 clusters) through chapter 18's file system costs
394 disk commands:
- 2 for the root directory (its FAT entry and its one cluster),
- 196 for the FAT – one sector read per FAT entry, although one FAT sector holds 128 entries,
- 196 for the data.
The data has to come from the disk once. The FAT reads are repeats: the cache's job.
The other cost is invisible in that number: during each command the CPU spins in wait_until. With four CPUs and a
scheduler (chapter 15), that is a CPU that could run another thread. The controller can say when it is done – by
interrupt.
Step 1: a cache of sectors
BlockCache<D> is a BlockDevice in front of another one. It keeps sectors in a BTreeMap from sector number to
data, each with the time it was last used (a counter, clock). A read takes what the cache has and fetches each
run of missing sectors with one read of the device. A write goes to the device first:
#![allow(unused)]
fn main() {
    fn write(&mut self, lba: u64, buf: &[u8]) -> Result<(), BlockError> {
        check_request(self.sector_count(), lba, buf.len())?;
        self.device.write(lba, buf)?; // the disk first: if this fails, the cache still has the old data
        for (i, sector) in buf.chunks(SECTOR_SIZE).enumerate() {
            self.keep(lba + i as u64, sector);
        }
        Ok(())
    }
}
That is write-through: the disk is never behind the cache, so everything chapter 18 said about the order of
writes and about fsck.fat still holds. (A write-back cache would collect writes and save disk commands – and lose
them, and break that order, when the machine stops.)
When the cache is full, keep drops the sector whose used is smallest – the least recently used. It looks at every
sector for that; with 2048 sectors that is cheap next to one disk command.
The file system now sits on fs::Disk, the cache in front of SystemDisk:
#![allow(unused)]
fn main() {
pub type Disk = BlockCache<SystemDisk>;
pub const CACHE_SECTORS: usize = 2048;
}
One rule comes with it: everything that writes to the disk must go through the cache, or the cache holds old
data. The shell's read and the tests' own mounts only read, so they may go around it.
Step 2: MSI – an interrupt without a wire
Chapter 12 routed the keyboard's interrupt line through the I/O APIC, and the MADT said which input it arrives at. For a PCI device the wiring is described in ACPI's AML bytecode, which this kernel does not interpret. PCI has a simpler way: message signaled interrupts. The device does not raise a line; it writes a value to a memory address – an address that belongs to the local APICs (0xFEE0_0000, with the APIC ID in bits 12–19). The APIC turns the write into an interrupt with the vector in the value.
MSI is a capability, one of the extra register blocks in a linked list that starts at offset 0x34 of the
configuration space. pci::Device::capability walks the list (at most 48 steps – a broken list could be a loop);
enable_msi writes the address and the vector, switches MSI on and the old interrupt pin off:
#![allow(unused)]
fn main() {
    pub fn enable_msi(&self, vector: u8, apic_id: u8) -> bool {
        let Some(msi) = self.capability(CAPABILITY_MSI) else {
            return false;
        };
        let control = self.location.read(msi) >> 16;
        let is_64bit = control & (1 << 7) != 0;
        self.location.write(msi + 4, 0xFEE0_0000 | (apic_id as u32) << 12); // the address: which APIC
        let data = if is_64bit {
            self.location.write(msi + 8, 0); // the high half of the address
            msi + 12
        } else {
            msi + 8
        };
        self.location.write(data, vector as u32); // the data: fixed delivery, edge, this vector
        // control: enable (bit 0), one message only (bits 4-6 = 0); the low half (id, next) cannot be written
        self.location.write(msi, ((control & !(0b111 << 4)) | 1) << 16);
        let command = self.location.read(COMMAND) & 0xFFFF;
        self.location.write(COMMAND, command | COMMAND_NO_PIN_INTERRUPT);
        true
    }
}
ahci::init calls it with vector 0x50 and the APIC ID of the CPU it runs on, then sets GHC.IE (the controller may
interrupt) and, per port, PxIE: "the disk answered" (the register FIS that ends every command) and "task file
error". interrupts.rs puts a handler on vector 0x50 – and the old test that only the vectors we handle are present
in the IDT noticed the new one at once.
Step 3: the handler, and sleeping until it comes
The handler finds the ports that report something, notes errors, clears the status bits (by writing 1 – first in the port, then in the HBA) and wakes whoever waits:
#![allow(unused)]
fn main() {
pub fn handle_interrupt() {
    let hba = HBA.load(Ordering::Relaxed);
    if hba == 0 {
        return;
    }
    let pending = read32(hba + HBA_IS);
    for port in (0..32).filter(|port| pending & (1 << port) != 0) {
        let registers = hba + 0x100 + port as u64 * 0x80;
        let status = read32(registers + PORT_IS);
        if status & IS_TASK_FILE_ERROR != 0 {
            FAILED_PORTS.fetch_or(1 << port, Ordering::Relaxed);
        }
        write32(registers + PORT_IS, status);
    }
    write32(hba + HBA_IS, pending);
    INTERRUPTS.fetch_add(1, Ordering::Relaxed);
    task::wake(EVENT);
}
}
The errors go into FAILED_PORTS because the handler has just cleared PxIS – the waiting thread would not find the
error bit there any more. And the command waits with the wait_for of chapter 15, on Wait::Event(0x50) – the
variant that chapter added for exactly this:
#![allow(unused)]
fn main() {
        if USE_INTERRUPTS.load(Ordering::Relaxed) && interrupts::enabled() {
            // sleep until the interrupt handler wakes us. `wait_for` announces the wait before it asks `done`
            // (chapter 15): an interrupt that comes in between is not lost.
            task::wait_for(EVENT, || done().then_some(()));
        } else {
}
Here chapter 15 pays off. The interrupt can come at any moment – even before the thread has gone to sleep, on another
CPU than the one the thread runs on (the MSI goes to one APIC; the thread may be anywhere). wait_for marks the
thread blocked first and asks done second: an interrupt before the question is seen by the question; one after it
finds the thread blocked and wakes it. Without MSI, or with interrupts off on this CPU, the driver polls as before.
The tests
make test runs 137 tests in the kernel; new:
the_cache_reads_a_sector_once(runs of missing sectors become one read; hits and misses counted),writes_go_through_to_the_device,the_least_recently_used_sector_goes_first– on a counting disk in RAM;the_sata_controller_has_msi(the capability list, MSI switched on),commands_end_by_interrupt(16 commands, and interrupts came);- the shell's
disknow reports commands, interrupts and the cache, and the test checks "done by interrupt".
Everything of chapter 18 runs on top of the cache unchanged – including check-disk.sh, so fsck.fat and mtools
still check what the kernel wrote.
Counter-check: with the task::wake in the handler commented out, the test kernel hung (timeout after 40 s, twice)
– already in ahci::init, at IDENTIFY. So the commands really wait for the interrupt; nothing polls behind its back.
Run it
cd course/19-disk-irq
make run
After the FAT32 lines:
Cache: reading /big.bin took 394 disk commands without the cache, 196 through it, 0 the second time
AHCI: commands end by interrupt: yes, 847 interrupts so far
196 through the cache, not 198: the FAT is already in it – mount read the whole FAT to count free clusters, through
the cache. The second read needs no disk at all. In the shell, disk shows the counters:
yak> disk
QEMU HARDDISK on port 0: 131072 sectors of 512 bytes
commands: 847 sent, done by interrupt (847 interrupts)
cache: 1207 of 2048 sectors, 596 hits, 1207 misses
(the numbers of one run, straight after boot; they grow with every command, and there may be fewer interrupts than commands – see below).
What can go wrong
- Writing around the cache: a write that goes straight to the disk leaves an old copy in the cache, and the next
read returns it. Everything that writes uses
fs::FS. - Clearing the status before reading it: the handler must look at PxIS before it clears it, and keep what the
thread needs (
FAILED_PORTS). - Two interrupts, one delivery: an MSI that arrives while the same vector is still pending in the local APIC is
merged with it. So there may be fewer interrupts than commands – harmless, because
doneasks the controller, not a counter. The reference kernel's tests once expected one interrupt per command (bug #8). - No timeout any more:
wait_untilgave up after a second;wait_forsleeps until it is woken. A disk that never answers now hangs the thread for good – the price of sleeping, and the reason real drivers add a timer. - A spin lock held while sleeping: the thread sleeps with
ahci::DISKlocked. Another thread that wants the disk spins on the lock until the command is done – correct, but wasteful; a lock that puts the waiter to sleep (the reference kernel'ssync::Mutex) would be better.
Experiments
- Make the cache smaller than the FAT (
CACHE_SECTORS = 512) and read/big.bintwice. How many commands now, and why does least-recently-used do badly when a file is read from start to end? - Count how long
wait_forsleeps against how longwait_untilspun: read 2048 sectors withtime::uptime_msaround it, with and without MSI. Is the interrupt slower for a single command? - Let
FatFs::read_fileread runs of neighbouring clusters with one call instead of one per cluster. What does/big.bincost then? - Send the MSI to CPU 3 instead of the boot CPU (its APIC ID from
smp::apic_id). Does anything change?
That ends part V: the kernel finds its disk, reads and writes files on it, and waits for it the way it waits for everything else. Chapter 20 starts part VI: code that runs in ring 3, and the first system call.
20 – Ring 3 and the first system call
Goal: run code that may not do everything – in ring 3, the CPU's lowest privilege level – and give it one
controlled door back into the kernel: a system call.
You end up with: user segments in the GDT, a TSS whose RSP0 follows the running thread, pages with the USER bit,
a jump to ring 3 with iretq, int 0x80 with two system calls (write, exit), and faults in ring 3 that end the
program instead of the kernel. The start of part VI – and, for now, the last chapter of the course.
Code: course/20-ring3/
(chapter 19 plus user.rs; user segments and RSP0 in gdt.rs, a DPL 3 gate in idt.rs, the USER bit in
paging.rs, faults from ring 3 in interrupts.rs, one line in task.rs)
What changed: diff -ru course/19-disk-irq course/20-ring3 (in the repository) shows every line this chapter
adds.
Background: four rings, two used
x86 has four privilege levels, rings 0 to 3; every operating system in use today uses two. The kernel runs in ring 0 and may do everything. Code in ring 3 may not:
- run privileged instructions –
cli,hlt, loading CR3, the GDT or the IDT, port I/O: a general protection fault (#GP); - touch a page whose page table entries lack the USER bit: a page fault (#PF);
- raise an interrupt vector with
intunless the IDT gate says it may.
The CPU checks all of that on every instruction, so a program can only hurt itself – if the kernel turns its faults into "this program ends" instead of a panic. And the program needs a way to ask the kernel for things it may not do itself: the system call.
The current privilege level is the low 2 bits of CS. So "going to ring 3" means loading a CS whose descriptor has
DPL 3 – and the way to lower the privilege is a return: iretq, a far return or sysretq. Going up is
what interrupts and exceptions do: the CPU switches to ring 0 and – because the ring 3 stack cannot be trusted –
to a stack it takes from the TSS: RSP0.
Step 1: segments for ring 3
Two more descriptors in the GDT: the kernel's code and data descriptors with DPL 3 (gdt.rs):
#![allow(unused)]
fn main() {
const USER_DATA: u64 = 0x00CF_F200_0000_FFFF; // P | DPL3 | S | RW
const USER_CODE: u64 = 0x00AF_FA00_0000_FFFF; // P | DPL3 | S | E | RW, L = 1
}
They go to 0x28 and 0x30; with the requested privilege level 3 in the low bits, ring 3 uses the selectors 0x2B and 0x33. The GDT now has 7 entries; chapter 4's test of its size expects 7 now.
Step 2: RSP0 – a kernel stack for every thread
When the timer interrupts a program, the CPU must push its frame somewhere in the kernel – onto RSP0 of the TSS of the CPU it runs on. That stack must belong to the thread that was interrupted: if it is preempted there, its kernel stack must survive while other threads run, and when it comes back, perhaps on another CPU, it needs the same stack. So the scheduler sets RSP0 of its CPU at every switch, to the stack of the thread it switches to:
#![allow(unused)]
fn main() {
    // an interrupt or a system call from ring 3 must land on this thread's own stack (chapter 20)
    if let Some(stack) = &thread.stack {
        crate::gdt::set_kernel_stack(stack.top);
    }
}
Until now the TSS was written once; now the kernel changes it while the CPU uses it. gdt.rs keeps each CPU's TSS in
an UnsafeCell (Rust's way of saying "changed through a shared reference") and a pointer to it per CPU:
#![allow(unused)]
fn main() {
pub fn set_kernel_stack(top: u64) {
    let tss = TSS_OF[crate::smp::cpu()].load(Ordering::Relaxed);
    if tss.is_null() {
        return; // a CPU that has no TSS yet runs no thread from ring 3 either
    }
    unsafe {
        let mut stacks = (*tss).privilege_stacks;
        stacks[0] = top;
        (*tss).privilege_stacks = stacks;
    }
}
}
(The copy in and out is because the TSS is a packed struct: Rust allows no reference to its unaligned fields.)
Step 3: pages a program may use
Bit 2 of a page table entry, U/S, is the USER bit. A program may use a page only if the bit is set in every entry on
the way – PML4, PDPT, PD and the page table. Chapter 9's map made new tables with PRESENT and WRITABLE only, so it
learns to pass USER on:
#![allow(unused)]
fn main() {
        // ring 3 may use a page only if every table on the way says USER too (chapter 20)
        let user = flags.0 & Flags::USER.0;
        if !entry.is(Flags::PRESENT) {
            // a new, empty table: zeroed, or its garbage would be read as entries
            let new = pmm::alloc_frame_zeroed().ok_or(MapError::OutOfFrames)?;
            // the tables above allow everything; the last entry decides what the page may do
            *entry = Entry::new(new, Flags(Flags::PRESENT.0 | Flags::WRITABLE.0 | user));
        } else if entry.is(Flags::HUGE) {
            return Err(MapError::HugePageInTheWay);
        } else {
            entry.0 |= user;
        }
}
user.rs maps three pages in the empty lower half, once: code at 0x40_0000 (USER, not writable), data at
0x40_1000 and a stack page below 0x80_0000 (USER, writable, not executable). The kernel fills them through the HHDM,
so the code page can stay read-only for the program. They stay mapped for good: a page unmapped on one CPU can still
be in the TLB of another, which would go on using a frame that may already be someone else's.
There is one address space – the kernel's – and these three pages are in it, so one program runs at a time. Giving each program its own page tables, and loading programs from the disk, is what chapter 21 of the plan would do.
Step 4: into ring 3
iretq takes RIP, CS, RFLAGS, RSP and SS from the stack, as if it returned from an interrupt that came from ring 3.
So we push what we want to find there:
#![allow(unused)]
fn main() {
fn enter(rip: u64, stack_top: u64) -> ! {
    unsafe {
        asm!(
            "push {ss}",
            "push {sp}",
            "push {flags}",
            "push {cs}",
            "push {ip}",
            "xor eax, eax", "xor ebx, ebx", "xor ecx, ecx", "xor edx, edx",
            "xor esi, esi", "xor edi, edi", "xor ebp, ebp",
            "xor r8d, r8d", "xor r9d, r9d", "xor r10d, r10d", "xor r11d, r11d",
            "xor r12d, r12d", "xor r13d, r13d", "xor r14d, r14d", "xor r15d, r15d",
            "iretq",
            ss = in(reg) USER_DATA_SELECTOR as u64,
            sp = in(reg) stack_top,
            flags = in(reg) 0x202u64,
            cs = in(reg) USER_CODE_SELECTOR as u64,
            ip = in(reg) rip,
            options(noreturn)
        )
    }
}
}
RFLAGS 0x202 has the interrupt flag set: the timer can take the CPU away from the program. The registers are cleared first – they hold kernel values, addresses among them, which are none of the program's business.
user::run copies a program into the code page, starts a thread whose entry is enter, and joins it. A program is
a thread that happens to run in ring 3.
Step 5: the system call
The door back is int 0x80, the vector Linux used on 32-bit x86. Its IDT gate gets DPL 3 (set_user_callable in
idt.rs); every other gate keeps DPL 0, so a program cannot fake a timer tick or a page fault with int.
The handler needs the registers as the program left them – the call's number in RAX, the arguments in RDI and RSI –
and an extern "x86-interrupt" function does not get them. So the entry is a few lines of assembly: save the
registers a Rust function may change, pass their address, restore them (RAX now holding the result), iretq:
#![allow(unused)] fn main() { ".global syscall_entry", "syscall_entry:", "push rax", "push rcx", "push rdx", "push rsi", "push rdi", "push r8", "push r9", "push r10", "push r11", "mov rdi, rsp", "call {dispatch}", "pop r11", "pop r10", "pop r9", "pop r8", "pop rdi", "pop rsi", "pop rdx", "pop rcx", "pop rax", "iretq", dispatch = sym syscall, }
The CPU pushed 5 values, we push 9: 14 × 8 bytes, so the stack is 16-byte aligned at the call, as the ABI wants.
Then the call itself:
#![allow(unused)] fn main() { extern "C" fn syscall(registers: &mut Registers) { debug_assert_eq!(registers.cs & 3, 3, "only ring 3 calls int 0x80"); registers.rax = match registers.rax { SYS_WRITE => write(registers.rdi, registers.rsi), SYS_EXIT => end(Exit::Code(registers.rdi)), _ => NO_SUCH_CALL, }; } }
exit ends the thread from inside the handler – its stack is its own, nobody returns there. write prints bytes the
program names by address and length – and here is the rule every system call lives by: an address from a program
is never trusted. It could point into the kernel, past the end of the lower half, or wrap around:
#![allow(unused)] fn main() { fn user_bytes(address: u64, length: u64) -> Option<&'static [u8]> { let end = address.checked_add(length)?; if end > USER_END { return None; } let mut page = align_down(address, PAGE_SIZE); while page < end { if !paging::flags(page)?.contains(Flags::USER) { return None; } page += PAGE_SIZE; } Some(unsafe { core::slice::from_raw_parts(address as *const u8, length as usize) }) } }
A bad address gets −14 back (Linux's EFAULT), an unknown call −38 (ENOSYS).
The first program, assembled into the kernel and copied to 0x40_0000 – it only uses addresses relative to RIP, so it runs wherever it is put:
#![allow(unused)] fn main() { "user_hello:", "mov eax, 1", "lea rdi, [rip + 2f]", "mov esi, 19", "int 0x80", "mov eax, 2", "mov edi, 42", "int 0x80", "ud2", }
Step 6: a fault in ring 3 is the program's
The handlers of #GP, #PF, #UD and #DE look at the CS the CPU saved. If it says ring 3, the program ends and the kernel goes on:
#![allow(unused)] fn main() { fn end_user_program_on_fault(frame: &InterruptStackFrame, what: &'static str) { if frame.cs & 3 == 3 { crate::println!("Ring 3: {} at {:#x} - the program is ended", what, frame.rip); user::end(user::Exit::Killed(what)); } } }
main.rs declares mod user; and kmain calls show_ring3() after show_disk(): the hello program, then one that
tries cli.
The tests
make test runs 145 tests in the kernel; new:
the_user_segments_have_privilege_level_3(gdt.rs);a_program_writes_and_exits(the output, exit code 42),a_program_has_a_stack(push 5; pop rdi);privileged_instructions_end_the_program(cli),kernel_memory_is_out_of_reach(reading a kernel address, and writing into its own read-only code page: page faults);system_calls_check_what_they_get(a kernel pointer → −14, call 99 → −38, anduser_bytesat the edges: past the lower half, wrapping around, an unmapped page);the_timer_takes_the_cpu_away_from_ring_3– a program that spins until a byte in its data page changes; the kernel sleeps 50 ms meanwhile, then changes the byte. It passes withKERNEL_SMP=1too, where only the timer can get the one CPU back from ring 3;each_cpu_switches_to_the_thread_s_own_kernel_stack– RSP0 of the CPU is just above the running thread's stack pointer.
The IDT test of chapter 5 knows vector 0x80 now. Three counter-checks, one run each:
- the gate without DPL 3:
int 0x80itself is a general protection fault – every program is ended at its first call; - USER only on the page, not on the tables above: a page fault at 0x400000, the program's first instruction;
- no
set_kernel_stackin the scheduler: RSP0 is 0, the first interrupt from ring 3 pushes to address −8 – a page fault the CPU cannot deliver either: a double fault ("last page fault at 0xfffffffffffffff8").
Run it
cd course/20-ring3
make run
After the disk lines:
Hello from ring 3!
Ring 3: the program ended with Code(42)
Ring 3: general protection fault at 0x400000 - the program is ended
Ring 3: the program that tried `cli` ended with Killed("general protection fault") - and the kernel goes on
What can go wrong
- RSP0 left alone: a double fault at the first interrupt from ring 3 (the counter-check above) – or, worse, RSP0 of another thread: two threads on one kernel stack, a crash far from its cause.
- USER missing above the page: the page looks right and faults anyway. The CPU combines the bits of all four levels.
- A gate with DPL 3 too many: a program could raise any vector – the timer's, a page fault's with a forged frame. Only 0x80 is open.
- Trusting an address: a
writethat printed whatever address it was given would print the kernel's memory to anyone who asks – the counter-exampleuser_bad_pointerasks exactly that. - Kernel values in registers: without the
xors, the program starts with kernel addresses in its registers – a gift for an attacker looking for where the kernel is. syscallinstead ofint 0x80: faster, and what the reference kernel uses – butsyscalldoes not switch the stack. The kernel must do it itself, with a per-CPU area reached throughswapgs, andsysretto a non-canonical address faults in ring 0. That is a chapter of its own;int 0x80keeps this one to ring 3.
Experiments
- Add a system call
getcputhat returns the number of the CPU the program runs on. Run a program that spins and calls it now and then: does it move between CPUs? - Give the program a second stack page, but forget the USER bit on it. Where exactly does it fail?
- Let
writeaccept at most 256 bytes. Why might a kernel want such a limit? - Look at the reference kernel's
kernel/src/arch/x86_64/syscall.rs: what does its entry do before it can push anything?
The end, for now
This is the last chapter I have written for now (my decision of 2026-11-06, in docs/ROADMAP.md). The kernel boots,
handles interrupts, manages memory, runs threads on every CPU, reads and writes a FAT32 disk, and runs code in ring 3
that can only ask. The reference kernel goes on from here – own address spaces, programs loaded from the disk,
processes, pipes, signals, a network stack – and its walkthroughs explain how.
Walkthroughs
Each walkthrough follows one thing that happens through the code, step by step, with links to the functions involved. Read them with the code open next to them.
| Walkthrough | Follows | Touches |
|---|---|---|
01 – From power-on to /bin/sh | the boot | Limine, GDT/IDT, memory, interrupts, scheduler, disk, first process, ring 3 |
| 02 – A key press reaches a program | one key | IRQ, ring buffer, scancode decoder, blocking wait, read syscall |
03 – cat /README.txt | wc | a pipeline | shell, pipe/dup2/spawn, FAT32, pipe buffer, scheduler, exit and wait |
| 04 – A page fault in a program | one bad memory access | exception, demand paging, killing a process, kernel-mode faults |
How the links are kept honest: a link written as [name](path) promises that name appears in that file.
scripts/check-doc-refs.py (part of make check) verifies every such link in docs/ and README.md, so a rename in
the code breaks the build until the walkthrough is updated. Line numbers are not used – they change too often.
01 – From power-on to /bin/sh
Try it: make run and watch the serial output in the terminal; make debug + make gdb and break kmain to step
through it.
1. Firmware and Limine
The firmware (BIOS or UEFI/OVMF) starts Limine from the ISO that run-qemu.sh builds.
Limine reads limine.conf, loads the kernel ELF to the higher half (0xffffffff80000000, see
linker.ld), switches to 64-bit long mode with paging on, and fills in the answers to our
requests – static structs in boot.rs such as BASE_REVISION
(memory map, framebuffer, HHDM offset, RSDP). Then it jumps to kmain.
At this point interrupts are off, we run on Limine's stack and Limine's page tables.
2. kernel::init – one subsystem after another
init brings the machine up in an order where each step only needs the ones before it:
serial::init– COM1, so that everything after it can print.- The Limine protocol check (
BASE_REVISION) before any response is read. gdt::init– our own segments and the TSS (with the double fault stack),fpu::init,enable_protection(SMEP/SMAP),interrupts::init– the IDT with all exception handlers.mem::init– frame allocator from the memory map (pmm.rs), our page table code (paging.rs), the kernel heap (heap.rs). From here onalloc(Vec,Box, …) works.syscall::init– the MSRs forsyscall/sysret.irq::init– ACPI tables, local APIC timer, I/O APIC routing for keyboard and COM1.console::init– text on the framebuffer.task::init– the scheduler; the code running now becomes thread 0.init_storage– PCI scan, AHCI disk;mount_root– FAT32.enable_interrupts– from now on the timer preempts threads.smp::init– wakes the other cores (INIT/SIPI, trampoline); they join the scheduler.net::init– e1000, DHCP.
3. Our own stack, then give memory back
Back in kmain, the kernel allocates a stack with a guard page
(alloc_stack) and switches to it (switch_stack) –
Limine's stack has no guard page, an overflow there would silently corrupt memory. On the new stack,
kernel_main calls reclaim_bootloader_memory: page tables
that still live in bootloader memory are copied, every CPU switches to the copy, and the old regions go back to the
frame allocator (≈ 13 MiB).
4. The first process
run_init reads /bin/sh from the disk and calls
spawn_with:
elf::parsechecks the ELF header and collects the loadable segments;AddressSpace::newcreates a page table whose upper half is the kernel's;elf::loadmaps each segment with the right permissions (code not writable, data not executable);- 4 stack pages below
USER_STACK_TOPare mapped, the argument block is copied to the top; spawn_usercreates a kernel thread that will leave for ring 3, and theProcessentry (files, cwd, environment, heap) is added to the table.
run_init then waits for the shell to end – if it ever does, the kernel shell (Shell) takes over.
5. Into ring 3
The scheduler picks the new thread. It starts in thread_start, which sees the
user_entry and calls enter_user. The assembly enter_user_mode pushes a
fake interrupt frame (user SS, RSP, RFLAGS with IF, user CS, RIP), clears every register so no kernel value leaks, and
executes iretq – the CPU is now in ring 3 at the ELF entry point.
That entry point is _start in ulib: it aligns the stack and calls the program's main
(declared with entry!). The shell prints its prompt with a write syscall – the first time a
user program asks the kernel for something.
Things to try
make debug,make gdb,break kernel::process::spawn_with,continue: inspect the ELF segments being mapped.mv /bin/sh /bin/sh.off; exitin the running system:run_initreturns and the kernel shell starts (kernel:/>); after a reboot,run_initcannot find/bin/shat all.mv /bin/sh.off /bin/shin the kernel shell puts it back.
02 – A key press reaches a program
You press ä on the keyboard while /bin/sh waits for input. What happens until the character appears in the line
editor?
Try it: python3 -I scripts/qemu-monitor.py kernel/target/x86_64-unknown-none/debug/kernel 5 -- "info pic" "info lapic"
shows the interrupt controllers; make debug + make gdb with break kernel::arch::x86_64::irq::keyboard stops in the handler.
1. The program goes to sleep
The shell's read_line calls sys::read(STDIN, …). The syscall instruction lands in
the assembly stub syscall_entry (syscall.rs), which switches to the
thread's kernel stack, saves the registers as a SyscallFrame and calls
dispatch. For descriptor 0 sys_read
goes to read_stdin, which calls
read_key_or_abort.
No key is there yet, so the thread blocks: wait_for(Wait::Input, …) marks it
blocked on input first and only then checks the condition again. If a key arrives on another CPU between the
check and the switch, the wake-up is not lost (see M26 in docs/LEARN.md). The scheduler runs another thread – or the
idle thread, which halts the CPU with hlt.
2. The hardware interrupt
The keyboard controller puts a scancode into its data port and raises IRQ 1. The I/O APIC was told in
irq::init to deliver it as vector 33 to the boot CPU; the CPU looks up the
IDT entry and runs keyboard (an extern "x86-interrupt" function):
handle_interruptreads the byte from port 0x60. A tiny tracker of the Ctrl key (track_ctrl_c) recognises Ctrl+C right here and sends SIGINT to the foreground process (interrupt_foreground) – that is why Ctrl+C works even while a program never reads. Every other byte goes into a ring buffer (RingBuffer). Translating the scancode is not done here: interrupt handlers must be short.wake_input_waiters→notifymarks every thread blocked onWait::Inputas ready.eoitells the local APIC the interrupt is handled.preempt_idle: if this CPU was idle, switch to the woken thread now instead of at the next timer tick (bug #7 indocs/BUGS.md).
ä on a German keyboard is one scancode (0x28); a key with Shift or AltGr is several bytes, and every key also sends a
release code (pressed code + 0x80).
3. Back in the woken thread
The shell's thread continues inside read_key_or_abort. try_read_key takes the bytes
from the ring buffer and feeds them to the scancode Decoder: it follows Shift,
Caps Lock, Ctrl, AltGr and the E0 prefix of extended keys, ignores releases, and maps the key position through the
layout table (German by default) to a KeyEvent – here Key::Char('ä').
The serial port takes a parallel path: com1 stores the byte, and
TerminalDecoder turns UTF-8 and VT100 escape sequences into the same KeyEvents. That is
how make e2e can type into the shell.
4. Into the program's buffer
A program reads bytes, not key events, so key_bytes turns the event into what a
terminal would send: ä becomes the two UTF-8 bytes C3 A4, arrow keys become ESC [ D and so on. Bytes that do not
fit into the program's buffer wait in stdin_pending for the next read.
copy_to_user checks the buffer and copies under the process table lock (bug #14),
dispatch puts the byte count into RAX and sysretq returns to ring 3.
5. In the shell
read_line feeds the bytes to its own Decoder (the user-space twin of the
kernel's terminal decoder) and hands the KeyEvent to the line editor
(handle – the same source file is compiled into the kernel shell and /bin/sh).
The editor inserts ä and writes it back with a write syscall – that is the echo you see.
Things to try
layout us(a kernel command, reached throughkshell) switches the table inscancode.rs: typey,zandäbefore and after.- Type while
fault spinruns (it never reads): the bytes wait in the ring buffer and appear in the shell afterwards – except Ctrl+C, which the interrupt handler turns into SIGINT at once.
03 – cat /README.txt | wc
Two programs run at the same time, connected by a pipe: cat reads a file from the FAT32 disk and writes it to its
standard output; wc reads its standard input and counts. Neither program knows about the other.
Try it: type the line in make run. ps in a second pipeline (cat | ps) shows both sides as processes.
1. The shell parses the line
run_pipeline gets the parsed pipeline (tokenizer and parser:
syntax.rs) with two stages. It first saves its own descriptors 0, 1, 2 with dup,
then for every stage:
- stdin is the read end of the previous pipe (or the shell's own stdin for the first stage),
- stdout is the write end of a new pipe (or the shell's own stdout for the last stage),
set with dup2 and followed by close of the original descriptor. Then the stage is started with spawn. The child
inherits descriptors 0–2 – this is the whole trick of Unix pipelines: the program just uses 0 and 1.
2. pipe, dup2, spawn in the kernel
sys_pipecallspipe: one 64 KiB queue, twoPipeEnds. Each end counts as a reader or writer; cloning an end (dup, inheritance) increments the count, dropping it (Drop) decrements it.sys_dup2copies a handle into another slot of the process's descriptor table.sys_spawncopies path and arguments from user memory, reads the program from the disk, takes descriptors 0–2, cwd, environment and signal settings of the parent, and creates the process withspawn_with(see walkthrough 01). Both children now exist and are scheduled independently – on different CPUs if there are several.
When the shell has started both, it restores its own descriptors and closes its copies of the pipe ends. Now only
cat holds the write end. That matters for step 5.
3. cat reads the file
cat opens /README.txt (sys_open) and calls read in a loop.
sys_read finds a file handle and asks the file system:
read_at looks up the path (a cached directory walk,
lookup), gets the file's cluster chain from the FAT, and reads runs of consecutive
clusters with one request through the sector cache (BlockCache) and the AHCI
driver (ahci.rs). While the disk works, the thread blocks and the CPU runs others
(the completion arrives as an MSI interrupt, M32).
4. Through the pipe
cat writes the data to descriptor 1. sys_write sees a pipe end and calls
write: as many bytes as fit go into the queue, then
notify(Wait::Pipe(id)) wakes a waiting reader. If the queue is full, the writer
blocks until the reader made room – this is flow control: a fast writer cannot use up memory.
wc reads descriptor 0, which is the read end: read takes what is there, or
blocks with wait_for while the queue is empty and writers exist.
5. End of file – the subtle part
cat reaches the end of the file and exits. exit_current clears its descriptor
table; the write end is dropped, the writer count becomes 0, and the readers are woken. wc's next read finds an
empty queue with no writer and returns 0 bytes: end of file. wc prints its counts and exits too.
If the shell had kept a copy of the write end, wc would wait forever – a classic pipeline bug, and the reason the
shell closes every pipe end it does not need.
6. The shell collects the results
The shell waits for every child (wait_all → wait). In the kernel
wait_child checks that the pid is really a child, lends the console (for Ctrl+C) to
it while waiting, blocks until the child's thread has ended, removes the process from the table and returns its exit
status. The status of the last stage becomes $?.
Things to try
cat /README.txt | wcvs.wc /README.txt: the same numbers, but one goes through a pipe.pipetestwrites 200 KB through a pipe – three times the pipe's capacity – and checks every byte.- Shrink
PIPE_CAPACITY– experiment 4 inEXPERIMENTS.md.
04 – A page fault in a program
Every memory access goes through the page tables. When a translation is missing or forbids the access, the CPU raises exception 14, a page fault. The same exception means three very different things in YAK:
| Situation | Result |
|---|---|
| a program touches its heap or stack for the first time | the kernel maps a page and the program never notices |
a program accesses memory it does not own (fault null) | the program is killed, everything else runs on |
| the kernel accesses unmapped memory | a kernel bug: panic, the system halts |
Try it: fault null and fault kernel in the shell, heaptest (demand paging), and make test runs
kernel/tests/page_fault.rs (a kernel-mode fault on purpose).
1. The CPU's part
On the fault the CPU stores the faulting address in CR2, pushes an error code (bit 0: page was present →
protection violation; bit 1: write; bit 2: user mode) and an interrupt frame, and – coming from ring 3 – switches to the
kernel stack from the TSS (RSP0, set for every thread in the scheduler). Then it runs the IDT entry for vector 14:
page_fault. PageFaultError
turns the error code into the readable text you see in messages.
2. User mode: maybe it is demand paging
from_user looks at the saved CS: ring 3? Then
handle_page_fault decides:
- the page was present (bit 0 set): a protection violation – writing to code, executing data. Not repairable.
- the address is inside the heap (below the
brkend) or the 1 MiB stack area (on_demand):populatemaps a zeroed frame (page_frame) and the handler returns –iretqrepeats the faulting instruction, which now succeeds. This is demand paging (M33):brkonly moves a number, memory is spent when it is used. A program that asks for 32 MiB and touches 3 pages gets 3 frames.
3. User mode: the program dies
Anything else is the program's fault. kill_current logs
process N (name) killed: page fault at 0x0 (page not present, write, user mode), rip=… on the serial port and calls
exit_current with ExitStatus::Killed(reason): other threads of the process are
stopped, descriptors closed, the address space freed. Other processes are untouched – their page tables never mapped
this one's memory.
The parent's wait returns the reason; number_for_reason reports a CPU
exception as signal 11 (SIGSEGV), so the shell sets $? to 139 and prints error: fault was killed: ….
fault kernel reads 0xffffffff80000000: the page is mapped – the kernel itself lives there – but without the USER
bit. The CPU refuses the access from ring 3 (the message says "protection violation, read, user mode"), which is exactly the protection
that keeps programs out of the kernel.
4. Kernel mode: a bug
If the fault happened in ring 0, there is nobody to blame but the kernel: page_fault panics with the address, the
cause and the interrupt frame (RIP!). make addr2line ADDR=<rip> turns the RIP into a file and line.
Two protections make sure the kernel faults loudly instead of silently misbehaving:
- SMAP – the kernel may only touch user memory inside
user_access; an accidental dereference of a user pointer faults (kernel/tests/smap.rs). - Guard pages below every kernel stack (
stack.rs): a stack overflow hits an unmapped page. The handler cannot run on the broken stack, so the CPU escalates to a double fault, which has its own stack in the TSS (IST1,kernel/tests/stack_overflow.rs).
Bug #14 (docs/BUGS.md) was a kernel-mode page fault caused from user space: the kernel checked a user buffer, another
thread unmapped it, and the kernel's copy faulted. That is why user memory is only copied in
copy_from_user / copy_to_user, with
the check and the copy under one lock.
Things to try
fault null,fault kernel,fault stack(stack overflow in user mode: the stack area ends after 1 MiB).heaptest, thenmem: memory is only used for touched pages.sigtestinstalls a handler – but a fault is not a signal you can catch yet in YAK; compare with what Linux does.
Experiments
Each experiment changes one thing, asks you to predict the result, and then shows what really happens. Undo every
change afterwards (git checkout -- <file>) and run make check to see that the system is whole again.
The "Measured" lines come from one run on 2026-10-26 (QEMU TCG on a 4-core host, debug build). Your numbers will differ; the direction should not.
1. More cores, same work
Question: demo 4 starts four threads that each count primes. How much faster are they with four cores than with one?
Do:
KERNEL_SMP=1 make run # then type: demo 4
make run # 4 cores (the default), type: demo 4
Measured: 590 ms with 1 CPU, 250 ms with 4 CPUs.
Why: with one CPU the timer interrupt switches between the four workers every 10 ms – they take turns. With four,
the scheduler (schedule) runs them at the same time on different cores. The speed-up is
less than 4×: the emulated CPUs share the host, the shell and network threads run too, and starting threads costs time.
Walkthrough: 01 – boot, section on smp::init.
2. Forget the floating-point registers
Question: the kernel saves and restores the FPU/SSE/AVX registers of a thread on every switch. What breaks without it?
Do: in schedule, replace
#![allow(unused)] fn main() { if let Some(old) = old_fpu { fpu::save(&mut *old); } fpu::restore(&*new_fpu); }
with let _ = (old_fpu, new_fpu);, then make run and type fputest.
Measured:
worker 2: MXCSR changed to 0x1f80 in round 1
worker 3: MXCSR changed to 0x1f80 in round 1
worker 1: XMM registers changed in round 1
worker 4: XMM registers changed in round 5
error: fputest exited with code 4
Why: the registers belong to the CPU, not to a thread. Without saving them, a thread continues with whatever the
previous thread left behind – here each worker sees the others' values and rounding modes. Programs computing with
f64 would silently get wrong results. See M24 in LEARN.md.
3. Undo a bug fix: check, then copy – without the lock
Question: bug #14 was fixed by copying user memory while holding the lock that also protects the page tables. Is the lock really needed, or would checking first be enough?
Do: in locked_user_copy, keep the check inside with_current but move the
copy behind it:
#![allow(unused)] fn main() { with_current(|p| { p.populate(addr, len) && p.space.as_ref().is_some_and(|s| s.is_accessible(addr, len, writable)) }) .filter(|&ok| ok) .ok_or(errno::EFAULT)?; crate::arch::x86_64::cpu::user_access(copy); // after the lock is released Ok(()) }
then KERNEL_SMP=1 make run and type syscheck race 5000.
Measured (2 of 2 runs):
KERNEL PANIC: panicked at src/arch/x86_64/interrupts.rs:111:5:
EXCEPTION: PAGE FAULT at address 0x000000000044b000
Why: between the check and the copy, the timer can switch to the program's other thread, which shrinks the heap
with brk and unmaps exactly that page. The kernel then touches an unmapped address in ring 0 – fatal. With one CPU
this happens within a second, because every timer tick is a chance to switch at the worst moment. This is a
time-of-check to time-of-use race; see walkthrough 04 and bug #14 in BUGS.md.
4. A pipe that holds 16 bytes
Question: a pipe buffers 64 KiB. What happens if it can only hold 16 bytes – does anything break?
Do: set PIPE_CAPACITY to 16, then make run and type time pipetest
(it pushes 200 KB through a pipe and checks every byte).
Measured: pipetest: all checks passed in both cases – 1.40 s with 64 KiB, 5.41 s with 16 bytes.
Why: correctness does not depend on the size: a full pipe makes the writer block until the reader made room
(write / read in pipe.rs). Only the cost
changes – with 16 bytes every few bytes need a wake-up and two thread switches. That is the trade-off behind every
buffer size in an operating system. Walkthrough: 03 – pipeline.
Ideas for your own experiments
- Set
TIMER_HZto 10 and rundemo 4with one CPU: what changes, and what doeshelloreport for its 100 ms sleep? - Make
CACHE_SECTORStiny (8) and comparetime wcof a large file. - Run
syscheck 100000 <seed>with different seeds – can you find a bug the fixed seed does not?
Extending YAK
Recipes for the four most common changes. Each one ends with the tests that prove it works – a change without a test
is not finished. Run make check before every commit.
Add a system call
Example in the tree: uname (syscall 52), added by following exactly these steps.
- Number – in
syscall.rs, modulenr: add a doc comment with the signature and the result, and the next free number. Never reuse or renumber: user programs on existing disks use the numbers. - Dispatch – one arm in
dispatch:nr::UNAME => sys_uname(a0, a1),. The arguments arrive asa0…a4(RDI, RSI, RDX, R10, R8). - Implementation – a
fn sys_<name>(…) -> SysResultnext to its relatives. The rules every syscall follows:- Never dereference a user pointer. Use
copy_from_user,copy_to_user,copy_struct_to_user,user_path. They check the range against the page tables and copy under the process lock (bugs #12, #14). An unchecked access is a kernel crash waiting for the wrong argument. - Errors are negative
errnovalues (Err(errno::EFAULT)); add a new code to moduleerrnoand to the messages ofimpl Display for Errorinfs.rsif you need one. - Check first, then change state. A call that fails should leave nothing half-done (bug #13).
- Bound every loop by something the kernel owns, never by a user-supplied length alone (bug #11).
- Blocking calls wait with
wait_forand give up whensignal_pendingis true (EINTR), so Ctrl+C andkillstill work. - Do not hold the process table lock (
with_current) while blocking or doing disk I/O.
- Never dereference a user pointer. Use
- User side – in
sys.rs: the same number aspub const, bumpSYSCALL_COUNT, and a safe wrapper (pub fn uname(buf: &mut [u8]) -> i64). Higher-level helpers belong in the otherulibmodules (fs,process, …). - Robustness test – add the call to
syscheck: its bad-pointer loop (every pointer argument × every bad pointer and length must return an error) and, if it never blocks, the random phase listRANDOM_OK.SYSCALL_COUNTmoves the "unknown number" checks automatically. - Functional test – call it from a program (step 2 of "Add a user program") and check the output in the integration test, or write checks into a self-test program.
- Document – a row in the syscall table in
docs/DESIGN.md.
Add a user program
- Create
user/src/bin/<name>.rs(oruser/src/bin/<name>/main.rsfor several files), starting likeuname.rs:#![no_std] #![no_main] use ulib::println; ulib::entry!(main); fn main(args: ulib::Args) -> i32 { println!("hi"); 0 }extern crate alloc;if you needVec/String(the heap is ready beforemain). The first line is a//!comment with a usage line –helpand readers rely on it. - Nothing to register: the Makefile finds every program (
USER_PROGRAMS),make userbuilds it, and every disk image gets it in/bin(scripts/mkdisk.sh,scripts/install-user.sh). Type its name in the shell. - Test it: a
run("<name>", "args")with assertions inuserspace.rs, and an E2E step ine2e-shell.pyif it matters at the shell prompt.
Add a test
| Kind | Where | Runs | Use it for |
|---|---|---|---|
| unit test | #[test_case] fn …() in a #[cfg(test)] mod tests of the module | cargo test --lib inside the kernel | functions and subsystems with the real hardware of QEMU |
| integration test | new file kernel/tests/<name>.rs (copy page_fault.rs for an own kmain), plus [[test]] name = "<name>" harness = false in kernel/Cargo.toml if it must fault or exit itself | its own kernel image | boot-time behaviour, faults, memory reclaim, real programs |
| user self-test | a program like pipetest.rs: print FAIL: … per failed check, exit code = number of failures | from the integration test and E2E | syscalls from user space |
| E2E step | a tuple (keys, expected, forbidden) in STEPS of e2e-shell.py | make e2e, make e2e-uefi | what a user types and sees |
All of them run headless with a 30 s timeout per kernel (KERNEL_TEST_TIMEOUT). A test that needs more than one CPU
should return early when smp::online_count() is 1, so KERNEL_SMP=1 make test stays green. Timing assertions need
a generous margin – the suite also runs under make stress on a loaded machine.
For a bug fix: write the test first, watch it fail on the old code, then fix (see docs/BUGS.md – every entry names its test).
Add a shell built-in
Built-ins are commands that must run inside the shell process (they change its state: cd, export, exit).
Everything else should be a program.
- Add
(name, usage, help)toBUILTINSinmain.rs–helpand tab completion use it. - Add an arm to the
matchinrun_stage(next to"pwd"); returnStage::Done(exit_code). - Test it in the scripted
shsessions ofuserspace.rs(injected serial input) or with an E2E step.
Write a course chapter
Chapter NN consists of the folder course/NN-slug/ and the page docs/course/NN-slug.md (listed in
docs/SUMMARY.md, in the table of docs/course/README.md and in the chapter list of the issue
form .github/ISSUE_TEMPLATE/course-stuck.yml).
- Start from the previous chapter: copy
course/(NN-1)-*/tocourse/NN-slug/and add the chapter's code. The folder must stay a complete project:Makefilewithrunandtest, a copy ofrust-toolchain.toml. make testproves the chapter's promise – it boots the kernel headless and checks its serial output (later chapters: the in-kernel test runner). A chapter without a test that fails when the new code is missing is not done.- Write the page: goal · background · the code step by step · run it · what the test checks · what can go wrong
(from
docs/BUGS.mdwhere the reference kernel hit the same problem) · experiments. Under Code: the page names the command that shows the chapter's changes:diff -ru course/(NN-1)-slug course/NN-slug. Every change a learner has to make appears on the page – including the lines that wire new code intokmain. - Code shown on the page is real code: a block written as
```rust,file=kernel/src/serial.rsmust appear line for line in that file of the chapter folder;scripts/check-course.py(inmake docs-check) fails otherwise – as it does when a chapter is missing fromSUMMARY.md, the course table or the issue form, or the page lacks itsdiffline. Blocks withoutfile=are free (output, shell commands, sketches). make coursebuilds and tests every chapter; CI runs it on every pull request.
Rules: one concept per chapter; no code the learner has not seen explained; no claim without a test or a recorded run; numbers and outputs on the page come from a real run.
When something goes wrong
docs/BUGS.md– most symptoms have happened before.make addr2line ADDR=…for a RIP from a panic;make debug+make gdbfor stepping.- Triple fault / reboot loop:
-d int,cpu_reset -D log.txton thescripts/run-qemu.shcommand line. - Interrupts not arriving:
python3 -I scripts/qemu-monitor.py <elf> 5 -- "info pic" "info lapic".
Learning notes
Short explanations of every subsystem: what it is and why we need it.
M1 – Booting with Limine
- At power-on the firmware (BIOS or UEFI) starts and loads the bootloader (Limine) from the ISO.
- Limine reads
limine.conf, loads our ELF (/boot/kernel), switches the CPU into 64-bit long mode, sets up paging and jumps tokmain. - We talk to Limine through requests: static structs with magic numbers in a dedicated section. Limine finds them in the ELF and fills in pointers to the responses (framebuffer, memory map, ...).
- Base revision: which protocol version we use. If Limine does not support it, the field is not cleared and we halt.
M1 – Serial port (UART 16550)
- An ancient standard chip, accessed through I/O ports (
in/outinstructions) starting at 0x3F8. - Init: set the baud rate via a divisor (DLAB bit), data format 8N1, enable the FIFO.
- Sending: wait until bit 5 of the line status register says "transmit buffer empty", then write the byte.
- QEMU redirects it to your terminal with
-serial stdio. This is ourprintfdebugging, and tests evaluate exactly this output.
M1 – Panic handler
- Without
stdnobody prints a message when the program crashes – we do it ourselves with#[panic_handler]: message to serial, thencli; hltforever.
M2 – Testing without an operating system
cargo testnormally needs the standard library, which we do not have. Withcustom_test_frameworksthe compiler collects all#[test_case]functions and passes them to ourrunnerfunction.- Every test is built as its own kernel. For each binary,
cargo testcalls the runner (scripts/run-qemu.sh): build the ISO, start QEMU headless. - The way back is the virtual QEMU device isa-debug-exit: a write to port 0xF4 terminates QEMU immediately with exit status
(value << 1) | 1– turning "kernel says OK" into an exit status for cargo. - A timeout catches hangs (endless loops, or a triple fault after which QEMU stops because of
-no-reboot).
M3 – Text on the screen
- The framebuffer is a piece of memory where every 32-bit word is a pixel (0x00RRGGBB). What we write there appears on the screen immediately.
- A bitmap font stores 16 bytes per character, one per pixel row; bit 7 is the leftmost pixel. Drawing means checking every bit and setting the foreground or background colour.
- PSF2 is the Linux console font format: header, glyphs, and a table "which Unicode character is which glyph" (that is where the umlauts come from).
- Scrolling: when the last row is full, all pixel rows are copied up by one font height (16 px) and the bottom row is cleared.
M4 – GDT and TSS
- The GDT is a table of segment descriptors, a leftover from 16/32-bit times. In 64-bit mode almost only two things matter: whether a code segment is "64-bit" (L bit) and which privilege level applies (ring 0 = kernel, ring 3 = programs).
- The CS register cannot simply be written. We push selector and return address on the stack and execute a "far return" (
retfq), which makes the CPU reload CS. - In 64-bit mode the TSS no longer holds task state but stack pointers. The IST (interrupt stack table) provides up to 7 emergency stacks: if the kernel stack overflows it is broken – and the double fault handler would itself need a stack. So we let the CPU switch to a separate IST stack for it. Without that we would get a triple fault and the CPU resets.
M5 – Interrupts and exceptions
- An exception is raised by the CPU itself when something goes wrong: division by zero, invalid instruction, access to unmapped memory (page fault), ...
- The IDT is a table with 256 entries: for each vector it says which function the CPU should jump to. Before that the CPU pushes RIP, CS, RFLAGS, RSP and SS (the interrupt stack frame), and for some exceptions an additional error code.
- Handlers end with
iretqinstead ofretso the CPU pops the frame again –extern "x86-interrupt"does this for us. - Page fault: CR2 holds the address that caused the fault; the error code tells whether the page was missing or protected, whether it was a read or a write, and whether kernel or user code made the access.
- Double fault: happens when another exception occurs while handling one. If that fails too: triple fault → CPU reset
(with
-no-rebootQEMU simply stops).
M6 – Hardware interrupts, PIC and timer
- Devices signal via an IRQ (interrupt request). The 8259 PIC collects 16 IRQ lines (two chips of 8, cascaded) and forwards them to the CPU as interrupt vectors.
- Remap: out of the box IRQ0 would arrive as vector 8 – which is also the double fault. So we move the IRQs to 32–47.
- EOI (end of interrupt): every handler must tell the PIC it is done, otherwise no further interrupt arrives.
- The PIT is a counter running at 1.19 MHz. A divisor of 11931 (1193182 / 100, rounded down) gives ~100 interrupts per second = one "tick" every 10 ms.
Uptime and
sleepare built on top of it. hltputs the CPU to sleep until the next interrupt – this way the kernel waits without burning 100 % CPU.- APIC: modern CPUs have a local APIC per core sitting between PIC and CPU. Limine masked its PIC input,
so for now we disable it completely (bug #2). The course instead starts QEMU with a CPU without local APIC
(
-cpu qemu64,-apic): switching it off does not help under QEMU 8.2 (bug #25).
M7 – Keyboard
- When a key is pressed, the PS/2 controller sends a scancode and raises IRQ1. We read the byte from port 0x60.
- Scancodes describe the position of a key, not the letter: on QWERTZ and QWERTY the key next to T has the same code (0x15) but means "z" or "y" respectively. That is why we need a layout.
- Press = code, release = code + 0x80. We remember Shift, Ctrl and AltGr as state; Caps Lock toggles on every press.
- The interrupt handler does almost nothing (byte into a ring buffer) so that it finishes quickly; the work happens outside.
- Race while waiting: "buffer empty? →
hlt" is dangerous if the interrupt arrives exactly in between – then the CPU sleeps although a key is already there. Solution: interrupts off, check, thensti; hlt– the CPU guarantees that no interrupt can slip in betweenstiandhlt. While a periodic timer runs, the lost wake-up only delays the key until the next tick; without one it waits for the next key. - The buffer's spin lock is shared with the handler: the rest of the kernel takes it only with interrupts off – a handler that interrupts the lock's holder would wait for it forever.
M8 – Physical memory
- RAM is managed in frames of 4 KiB. Limine tells us via the memory map which address ranges are usable RAM and which are reserved (firmware, ACPI, devices, the kernel itself, ...).
- The bitmap allocator keeps one bit per frame: 0 = free, 1 = used. Allocating means finding a 0 bit and setting it; freeing clears it. For 256 MiB that is only 65536 bits = 8 KiB of bookkeeping.
- Physical addresses cannot be dereferenced directly because paging is on. Limine maps all of physical memory at a fixed
offset (HHDM, higher-half direct map), so physical
pis accessible at virtualp + offset. - Only usable ranges may be handed out at first. Bootloader reclaimable memory holds the page tables the CPU is using, the boot stack and Limine's responses (the memory map itself); it becomes free only after the kernel has its own.
M9 – Paging
- Every memory access uses a virtual address; the CPU translates it to a physical address through page tables. On x86_64 there are 4 levels: PML4 → PDPT → PD → PT, each a 4 KiB table with 512 entries. The address bits 47–39, 38–30, 29–21 and 20–12 pick the entry on each level, bits 11–0 are the offset inside the 4 KiB page.
- Each entry holds a physical address plus flags: present, writable, user-accessible, no-execute, ... A PD/PDPT entry can also map a 2 MiB / 1 GiB huge page directly.
- CR3 holds the physical address of the PML4. After changing an entry, the old translation may still sit in the TLB (a cache),
so we flush it with
invlpg. - Guard page: we leave the page below each kernel stack unmapped. If the stack overflows, the CPU touches that page and faults immediately, instead of silently corrupting the memory below.
- An entry's bits depend on the level: in a 2 MiB / 1 GiB entry bit 12 is PAT (caching type), not an address bit –
translatemust round the address down to the page size (bug #26). Limine builds the HHDM from 2 MiB pages where it can.
M10 – Heap
- The frame allocator only hands out whole 4 KiB pages. Most kernel data is much smaller and has arbitrary sizes – that is the job of the heap.
- Our linked-list allocator remembers all free gaps in a list. The list needs no extra memory: each free gap stores its size and a pointer to the next gap inside itself.
- Allocate: walk the list, take the first gap that is big enough (first fit), cut off what is not needed and put it back.
- Free: put the block back into the list at its address position; if it touches a neighbouring gap, merge them (coalescing) – otherwise the heap would crumble into many tiny unusable pieces (fragmentation).
- Once a
#[global_allocator]exists, Rust'salloccrate works:Box,Vec,String,BTreeMap– just like in normal programs. - The heap needs nothing but frames and
map: course chapter 10 starts it with nothing mapped, and the firstBoxmaps its first pages. - Locks and interrupts: if an interrupt handler allocated while its CPU was inside
alloc, it would wait forever for the lock its own CPU holds. The kernel therefore turns interrupts off around every heap call; the course chapter keeps them on because no handler allocates.
M11 – Shell
- A shell is a loop: print a prompt, read a line, split it into words, look up the first word as a command, run it.
- Course chapter 11 builds it small: commands write to a
core::fmt::Write, so a test can pass aStringand compare exactly what was printed. - The line editor lets you move the cursor and edit in the middle of the line. Because we only use the backspace character
(
\x08) to move left and simply overwrite characters, the same output works on our screen and on any serial terminal. - Terminals talk in escape sequences: an arrow key on a serial terminal arrives as three bytes
ESC [ A, colours are sent asESC [ 31 m. Our console understands a small subset, and the input decoder turns incoming sequences back into keys. - Serial input works like the keyboard: the UART raises IRQ4 when a byte arrives, the handler stores it in a ring buffer. This lets automated tests "type" into the real kernel through QEMU's stdin.
M12 – ACPI and the APIC
- ACPI tables are a description of the machine provided by the firmware. Limine gives us the RSDP, which points to the XSDT – a list of all other tables. Each table starts with a 4-letter signature and a checksum (all bytes add up to 0).
- The MADT (signature "APIC") lists every CPU's local APIC, the I/O APICs, and overrides such as "the timer (ISA IRQ 0) is actually wired to I/O APIC input 2".
- The I/O APIC replaces the old PIC: for every input line it has a redirection entry saying which vector to raise on which CPU, and whether the line is edge/level triggered and active high/low.
- The local APIC sits in each CPU. It receives the interrupts, needs an EOI after each one, and has its own timer. Its speed is unknown, so we measure it once against the PIT (whose frequency is fixed at 1.193182 MHz) and then program it for 100 Hz.
- APIC registers are memory-mapped I/O (MMIO): reading/writing special physical addresses talks to hardware, not RAM. Such pages must be mapped uncached, otherwise the CPU might serve stale values from its cache.
- Testing a clock: course chapter 12 first calibrated the APIC timer against PIT ticks that came twice as often as they should (the PIT's square wave through the I/O APIC, bug #27). Every test measured in those same ticks and passed. Only a second, independent clock showed it – the host's watch, and QEMU's known APIC rate of 1 GHz.
M13 – Multitasking
- A thread is "a CPU state + its own stack". To switch threads we save the registers of the running one on its stack,
remember its stack pointer, load the stack pointer of the next one and restore its registers – the context switch.
The next
retthen continues wherever that thread stopped. - Preemptive scheduling: the timer interrupt arrives every 10 ms and may switch to another thread, even if the running one never gives up the CPU voluntarily. Round robin: ready threads take turns in a queue.
- Blocking instead of busy-waiting: a thread that waits (sleep, keyboard input, another thread finishing) is taken off the ready queue and woken up by the event it waits for. If nobody is ready, the idle thread halts the CPU.
- The classic trap is the lost wake-up: check "no input yet", then the key arrives, then we go to sleep – and never wake up. We avoid it by checking and blocking with interrupts disabled.
- Course chapter 13 builds this for one CPU. The moment the timer handler touches the scheduler's queue, the heap is used in an interrupt handler – so its lock must be taken with interrupts off, or a tick that finds it held waits for ever.
M14 – PCI and the SATA disk
- PCI devices are found by reading their configuration space: vendor/device ID, class (storage, network, ...) and BARs (base address registers) that tell where the device's registers are mapped in physical memory.
- AHCI is the standard interface of SATA controllers. The kernel prepares command structures in RAM and the controller fetches them by itself – DMA (direct memory access). That is why the buffers must be real physical frames, and why the device needs "bus mastering" enabled.
- A disk is just a long array of sectors (512 bytes).
READ DMA EXT/WRITE DMA EXTmove sectors between disk and RAM, addressed by their number (LBA, logical block address). File systems are built on top of this.
M15 – The FAT32 file system
- A file system turns the flat array of sectors into named files and directories. FAT32 is old and simple, and every OS
(and Linux tools like
fsck.fatand mtools) can read it – ideal to check our own code against. - The disk is split into clusters (here 512 bytes). The FAT (file allocation table) has one entry per cluster saying
which cluster comes next in the same file – a file is a linked list of clusters. 0 = free,
0x0FFFFFF8+= end of the file. - A directory is just a file full of 32-byte entries: name, attributes, first cluster, size, timestamps.
- Names were originally limited to 8+3 upper-case characters. Long file names (VFAT) are stored in extra hidden entries right before the 8.3 entry, 13 UTF-16 characters each, protected by a checksum of the short name.
- Persistence means: after
write, the data must really be on the disk image, so the kernel flushes the disk after every change. The E2E test proves it by writing a file, powering off, booting again and reading it back. - The RTC (real-time clock) is a battery-powered clock chip; we read it via ports 0x70/0x71 for file timestamps and
date.
M16 – User space
- The CPU has privilege levels (rings). The kernel runs in ring 0 and may do everything; programs run in ring 3, where
privileged instructions (
cli,hlt, writing CR3, port I/O) raise a general protection fault and pages without the USER bit cannot be touched. A misbehaving program therefore cannot crash the kernel – it gets killed instead. - Each process has its own address space: its own top-level page table (PML4). The lower half is private, the upper half (the kernel) is the same in all of them. Switching processes = loading another PML4 into CR3.
- Entering ring 3 the first time: build the stack frame an interrupt would push (SS, RSP, RFLAGS, CS, RIP – with ring-3
selectors) and execute
iretq. Coming back happens through interrupts/exceptions (the CPU switches to the kernel stack stored in the TSS, RSP0) or throughsyscall. - A system call is a controlled door into the kernel: the program puts a number and arguments into registers and executes
syscall; the CPU jumps to the address in the LSTAR MSR in ring 0, the kernel does the work and returns withsysret. The kernel must never trust pointers from user space – it checks every buffer against the process's page tables. - An ELF file describes how to build the program image: the program headers list segments ("map these bytes from the
file at that address, with these permissions, plus zeroed memory for
.bss"). Our loader maps exactly these and jumps to the entry point. - Our programs live in
user/: a tiny runtime (ulib:_start, syscall wrappers,println!) plus one file per program. They are ordinary Rustno_stdbinaries, linked at 0x40_0000, and are loaded from/binon the FAT32 disk.
M17 – Files for programs
- A file descriptor is just a small number that stands for an open file inside one process: the kernel keeps a table per
process,
openputs an entry in it and returns its index,read/write/closetake that index. 0, 1 and 2 are pre-opened: keyboard input, screen output, error output. Because the console is "just another descriptor",catwrites a file to the screen with exactly the samewritecall it would use for a file. - The kernel remembers the position in an open file, so consecutive
reads continue where the last one stopped. - Every process has a current directory; relative paths in system calls start there. A program inherits it from the
shell – that is why
lswithout arguments lists the directory youcded into. - Errors come back as negative numbers (
-2=ENOENT"no such file or directory"), the same numbers Linux uses. - Programs get their arguments as one block with NUL bytes between them, so
cp "My Notes/a.txt" b.txtarrives as exactly two arguments even though the first one contains a space.
M18 – A heap for programs
- The kernel gives a process memory in big pieces:
brkmoves the program break, the end of the heap area right after the program image. Growing maps fresh zeroed pages, shrinking frees them again. - Handing out small pieces (a
Stringof 20 bytes) is the job of an allocator inside the program – hereulib::heap. It keeps a list of free blocks, takes the first one that is big enough (first fit), and when a block is freed it is merged with free neighbours so that the heap does not crumble into unusable fragments. - With a
#[global_allocator]in place, the standardalloccrate works:Vec,String,BTreeMap,format!– thesortprogram reads a whole file into memory and sorts its lines without knowing anything about pages.
M19 – Processes starting processes
spawnloads a program from the disk and starts it as a child of the caller;waitblocks until the child ends and returns how it ended (exit code, or the reason the kernel killed it). Only the parent may wait for or kill its children.- A child whose parent ends first is an orphan; since nobody will ever ask for its exit status, the kernel throws the status away as soon as the orphan ends.
- Ctrl+C must work even if the program never reads the keyboard (an endless loop). So the interrupt handler itself watches for it and marks the foreground process – the one the console currently belongs to – as killed. A process that is blocked (sleeping, waiting for input) is woken up so it notices immediately.
M20 – The shell becomes a program
- In a real OS the shell is not part of the kernel: it is an ordinary program that reads lines, starts other programs and
waits for them. The kernel only starts the very first program, init – here
/bin/sh. - Because the keyboard reaches programs as bytes, special keys must be encoded: the arrow keys become the same escape
sequences a serial terminal sends (
ESC [ D= left). The shell decodes them again and edits the line. - The kernel shell's line editor and parser are plain logic without hardware access, so the very same source files are
compiled into the kernel and into
/bin/sh. - If
/bin/shis missing or you typeexit, the kernel shell takes over – a safety net while the user space grows.
M21 – Pipes and redirection
- A pipe is a small buffer inside the kernel with two ends: one process writes into it, another reads from it.
If it is empty the reader waits, if it is full the writer waits – so
cat big.txt | wcworks with a fixed 64 KiB buffer. - When the last writer closes its end, the reader gets "end of file"; when the last reader is gone, writing fails.
- Redirection is just descriptor juggling: the shell makes fd 1 point to a file (
> file) or to a pipe, starts the program (which inherits fds 0–2 and has no idea), then puts its own fd 1 back.dup2(a, b)= "let b refer to what a refers to". Programs only ever write to fd 1. - Programs ask
isattywhether they talk to a person (echo typed characters, Ctrl+D ends input) or to a file/pipe.
M22 – System information for programs
- Commands like
psormemneed data only the kernel has. Instead of letting programs call kernel code directly, the kernel offers system calls that fill a struct in the program's memory (sysinfo,proclist). The struct layout is fixed (repr(C)) and checked for its size on both sides, so kernel and programs agree byte for byte. - An open file has one position:
readandwritecontinue there,seekmoves it. Writing in the middle overwrites, writing at the end grows the file, and writing after seeking past the end leaves a gap that reads as zeros.
M23 – A full-screen editor
- A terminal is not only a stream of lines: escape sequences can move the cursor anywhere (
ESC [ row ; col H), erase the rest of a line (ESC [ K) or swap colours (ESC [ 7 m). A full-screen program draws its whole picture with them. - The editor keeps the text as a list of lines in memory and only writes the file on Ctrl+S. Separating the text model
(insert, delete, cursor movement) from the drawing makes the model testable without a screen (
edit --selftest). - Redrawing everything on every key would be slow; the editor redraws only the line that changed unless it had to scroll.
M24 – Floating point and SSE registers
- Besides the general registers, the CPU has the x87 FPU and 16 XMM registers (128 bit each) for floating point and
vector work, plus the control register MXCSR (e.g. rounding mode). Compilers use them for
f64maths and fast copies. - When the scheduler switches threads, these registers belong to the thread too. If the kernel does not save them, one
program suddenly sees another program's numbers.
fxsavewrites all of them (512 bytes) to memory,fxrstorloads them. - The kernel itself is built without floating point, so it never disturbs them – only the context switch has to care.
fputestproves it: four programs keep different values in all XMM registers while being preempted constantly; with the switch code removed they immediately see each other's values.
M25 – Waking the other CPU cores
- At power-on only one core runs (the bootstrap processor). The others sleep until their local APIC receives an INIT signal followed by a STARTUP IPI carrying a page number: the core then starts executing at that page in 16-bit real mode – just like a PC in 1985.
- So we need start code below 1 MiB that walks through the history of the x86: real mode → protected mode (32 bit, segment table) → long mode (64 bit, needs PAE paging and the EFER.LME bit) and finally jumps into our Rust kernel.
- Each core needs its own stack, its own TSS (where its interrupt stacks are), and its own local APIC set up. Memory and page tables are shared – that is what makes it one machine.
- For now the extra cores only run small jobs we hand them; the scheduler learns to use them in the next milestone.
- Course chapter 14: every core needs its own TSS –
ltrmarks a TSS busy, and a second core cannot load it. A mistake in the start path usually ends in a triple fault that resets all cores; QEMU's-d int,cpu_resetlog shows the last exceptions.
M26 – One scheduler, many cores
- With several cores, "interrupts off" no longer means "nobody else runs": the other cores keep going. Every shared structure needs a real lock, and the order of operations suddenly matters.
- Switching threads: a core must not let go of the old thread before its registers are saved, or another core could start running it with stale registers. So the scheduler lock is held through the switch and released by the new thread.
- Lost wake-ups: "check if there is input, then go to sleep" breaks if the input arrives on another core between the two steps. The fix is to announce the sleep first ("I am waiting for input"), then check, then sleep – a waker that comes in between simply cancels the sleep.
- Idle cores sleep with
hlt; when work appears, another core wakes them with an inter-processor interrupt.
M27 – Networking
- A network card is another DMA device: we give it rings of descriptors pointing at buffers in RAM; it fills receive buffers with incoming Ethernet frames and sends the frames we put into the transmit ring.
- Frames are layered like envelopes: Ethernet (MAC addresses) carries IPv4 (IP addresses), which carries ICMP (ping) or UDP (datagrams to a port). Each layer has a small header in front of its payload.
- To send to an IP address, we first need the neighbour's MAC address: ARP asks "who has 10.0.2.2?" on the whole network and remembers the answer. Hosts outside our subnet are reached through the gateway.
- QEMU emulates a whole small network for us: a router at 10.0.2.2 that answers pings and forwards UDP to the host, which is how the E2E test talks to the kernel over UDP.
M28 – A fine clock
- The timer interrupt comes every 10 ms – too coarse to measure a ping. Every x86 core also has a time stamp counter
that counts up at a fixed, high rate (GHz). We only have to find out how fast: count TSC ticks while the PIT (whose
frequency is known exactly) measures 50 ms. After that,
TSC difference / frequencygives microseconds.
M29/M30 – TCP, DHCP, DNS, HTTP
- TCP turns lost, duplicated or reordered packets into a reliable byte stream: every byte has a sequence number, the receiver acknowledges what it got, and the sender repeats what was not acknowledged in time. A three-way handshake (SYN, SYN-ACK, ACK) opens a connection, FIN packets close each direction.
- DHCP: a new machine shouts "I need an address" (broadcast), a server offers one, the machine requests it, the server confirms – together with gateway and DNS server.
- DNS translates names into addresses: a small UDP question to a name server, which answers with A records.
- HTTP is plain text over TCP:
GET /path HTTP/1.0, an empty line, and the server answers with a status line, headers, an empty line and the file.
M31 – A shell you can program
- Environment variables are name/value pairs every process carries; a child gets a copy of its parent's.
PATHtells the shell where to look for programs. - Before a line is split into words, the shell replaces
$NAMEwith the value – except inside single quotes. 2>redirects the error output (fd 2) the same way>redirects fd 1;2>&1makes fd 2 point where fd 1 points.cmd &starts a program without waiting; the shell keeps a job list and reports when the job is done.- A script is just a file with shell lines;
#!at the start tells the shell to run it withsh.
M32 – Measure before you optimise
- The first guess ("the disk is slow, add a cache") was only part of the truth: the virtual disk answered in microseconds; most of the time went into walking the same FAT chain and directory again for every 4 KiB read. Timing each step separately showed where to work.
- A cache keeps recently used sectors in RAM; write-through means every write still goes to the disk immediately, so the cache can never lose data.
- MSI (message signaled interrupts): instead of an interrupt wire, a PCI device writes a small message to a special address – the local APIC – which turns it into an interrupt. No routing tables needed.
M33 – Getting memory back
- The bootloader's memory (its stack, page tables, the answers to our requests) is marked reclaimable: free once we no longer need it. The tricky part is the page tables – the CPU is using them right now. So we build copies elsewhere, switch every CPU over (writing CR3), and only then release the old frames.
- Demand paging: asking for heap memory with
brkonly reserves addresses. The first access to a page causes a page fault; the handler sees "page not present, inside the heap", maps a fresh zeroed page and returns – the CPU repeats the instruction, which now works. A program that reserves 32 MiB but touches three pages costs three frames.
M34 – Signals
- A signal is a tap on the shoulder of a running program: "the user pressed Ctrl+C", "please terminate". The kernel notes it (a bit per signal) and acts the next time the program would continue running in user mode.
- Without a handler the program simply ends. With a handler, the kernel makes the program "call" the handler as if the interrupted instruction had called it: it pushes the return address onto the program's stack and jumps to a small assembly routine in the program (the trampoline) that saves all registers, calls the handler and restores everything. The program never notices the interruption – except that a blocking call (sleep, read) returns "interrupted" (EINTR).
- Signals are why a shell can stop its own loop on Ctrl+C, and why
kill -TERMlets a program clean up first, whilekill -KILLcannot be caught.
M35 – A shell that is a programming language
- Until now every line was one command. A real shell first parses the text into a tree: lists of commands,
&&/||chains, pipelines, and compound commands likeif,whileandforthat contain lists themselves. Only when a command is about to run are its words expanded ($x,$((1 + 2)),*.txt), so a loop sees the new value of$ieach round. break,continue,returnandexittravel up the tree as a small "flow" value until the loop, function or shell that handles them.- When a line is not finished (an open quote, an
ifwithoutfi), the shell asks for more with the prompt>.
M55 – Using the output of a command
$(command)runs a command and puts what it printed in its place:echo "today: $(date)",for f in $(ls). The shell connects the command's output to a pipe and reads it back – a second thread reads while the command writes, because a pipe only holds 64 KiB and a writer with nobody reading would wait forever."$@"passes on a script's or function's arguments exactly as they came, each one a separate word even when it contains spaces."$*"glues them into one word; unquoted$@splits them again.
M56 – Choosing by pattern, and variables of your own
case $file in *.txt) …;; *.md) …;; esaccompares one word with patterns in order and runs the first branch that matches – the same*and?as for file names, applied to a string.local x=1inside a function gives the function its ownx: the old value is saved and put back when the function returns. Functions it calls still see thisx(dynamic scope) – unlike most programming languages.
M57 – A line longer than the screen
- A terminal knows nothing about "lines you are editing": it has a cursor and rows. When the text reaches the right edge it continues on the next row – so the editor must work out itself where position 170 of the line is (row 1, column 10 on a 160-column screen) and move the cursor there with "up", "down" and "right" escape sequences.
- A small trap: after writing in the last column, most terminals leave the cursor in that column until the next character arrives. The editor writes a space and returns to the row's start in that case, so it always knows where the cursor really is.
M58 – Losing packets on purpose
- A network loses packets all the time; TCP's job is to hide that. The test makes the kernel throw away every tenth packet it sends to itself – data, acknowledgements, even the very first SYN – and checks that the bytes still arrive complete and in order. They do, because every unacknowledged segment is sent again when its timer runs out.
- How long TCP keeps trying matters too: the wait doubles after each attempt, so a peer that has vanished is noticed only after several attempts. The test measures exactly that time and compares it with the sum it should be.
M36 – Threads and futexes
- A thread is a second "line of execution" inside the same program: same memory, same files, own registers and stack. For the kernel it is just one more schedulable thread that happens to use the process's page tables.
- Ending a process gets harder: other threads may be running on other CPUs right now. The kernel marks the process as ending, every thread notices on its next way into or out of the kernel and leaves, and the last step (freeing the memory) waits until all are gone.
- A futex lets user programs build locks that cost nothing when uncontended: an atomic instruction takes the lock; only a thread that has to wait asks the kernel to sleep "while this word still has that value", and the unlocking thread asks the kernel to wake it.
- The kernel got a sleeping mutex too: a thread that finds the disk busy now sleeps instead of spinning.
M37 – Guard rails in the CPU, and wider registers
- SMEP and SMAP are two CPU switches that protect the kernel from itself: with SMEP the kernel can never execute
code that lives in a user program's memory, with SMAP it cannot even read or write that memory – except in short,
explicit windows (
stac…clac) around the few functions that copy data between user programs and the kernel. A bug that follows a user-supplied pointer elsewhere now crashes at once instead of silently doing the wrong thing. - AVX registers (YMM) are 256 bits wide, twice the SSE registers. The kernel must save and restore them on every
thread switch; the
xsaveinstruction does that for every state component the kernel enabled in the register XCR0.
M38 – Finding an interrupt by trying
- Old PCI devices signal interrupts on a wire (INTA#). Which input of the I/O APIC that wire reaches is written down only in the ACPI tables' byte code (AML), which we do not run. So the kernel asks the hardware: it connects one possible input after the other to the network handler and makes the card fake an event; where the interrupt shows up, the wire is. Now the network thread sleeps until a packet really arrives instead of looking every 10 ms.
- Window scaling lets TCP say "I can take more than 64 KiB" (the window field has only 16 bits): both sides agree on a multiplier in their first packets.
- A DHCP address is only leased: half-way through, the client asks the server to extend it.
M41 – Testing how a kernel fails
- Normal tests check that the right input gives the right result. A kernel must also survive every wrong input: any program may pass any number as a pointer, length, descriptor or syscall number.
syscheckdoes that on purpose: null, kernel, non-canonical and unmapped pointers; lengths up tou64::MAX; closed and absurd descriptors; unknown syscall numbers – and then 20 000 random mixes with a fixed seed (so a failure can be reproduced). Every call must return an error, and the kernel must still be alive.- It found five bugs on the first runs (
docs/BUGS.md#11–#15): a length that froze the machine, an empty buffer that panicked the kernel, a directory entry lost on an error, a race between two threads that crashed the kernel, and a TLB shootdown that could wait forever. - Races only show up when timing is right.
syscheck racemakes the bad timing likely: one thread shrinks the heap thousands of times a second while another hands exactly that memory to the kernel. With one CPU the timer interrupt switches between them at random points – that is how the bug appeared. Running with 1, 2 and 4 CPUs matters. - Soak test (
make soak): the same mix of real work for many rounds (files, pipelines, all self-tests, background jobs, ping, HTTP over loopback). Slow leaks and rare hangs only show up over time. - Stress (
make stress): the whole test suite N times with 1, 2 and 4 CPUs, with an old CPU model and under UEFI. A test that fails once in five runs is a bug, not bad luck.
M52 – A guard below every thread stack
- A stack grows downwards. If nothing stops it, a thread that recurses too deeply simply keeps writing – into whatever lies below its stack: the heap, another thread's stack. The program then fails much later, somewhere else, for no visible reason.
- A guard is a range of addresses that is deliberately never mapped. The first write into it is a page fault, and the kernel knows at once what happened: the fault address is in a guard, so it is a stack overflow.
- The kernel stacks have had guards since M9, and nothing is mapped below the main user stack. Thread stacks came from the heap, where there is no room for a hole. Now the kernel hands out fixed stack slots – stack on top, guard below – and frees a slot once its thread has ended.
M53 – When the disk fails in the middle
- One file system command is many disk writes: the FAT (which clusters belong together), the data, the directory entry (name, size, first cluster). If the power goes out after some of them, the disk holds a mix of old and new.
- The order of the writes decides how bad that mix is. YAK writes new data and links it in the FAT before the directory entry points to it, and frees old clusters only after nothing points to them any more. A cut then leaves at worst clusters that are marked used but belong to no file ("lost clusters") – wasted space, no wrong data.
- Real file systems (ext4, NTFS) add a journal: they first write down what they are about to do, so after a crash
they can finish or undo it. FAT32 has no journal;
fsck.fatcleans up afterwards. - The test does not trust this reasoning: a fake disk fails at every single I/O of an operation, and a checker
(like a tiny
fsck) looks at what is left.
Tooling – GNU ld and binutils
- rustc compiles our code into object files; a linker combines them into the final ELF according to
kernel/linker.ld(load address, section order, segments). We use GNU ld (ld.bfd) for that. objdump -ddisassembles the kernel,nmlists symbols with addresses,readelf -lshows the segments Limine loads,addr2lineturns a RIP from a crash message into a source file and line.
Design decisions
Basics
| Topic | Decision | Why |
|---|---|---|
| Language | Rust nightly, #![no_std], some inline assembly | memory safety; nightly is needed for custom_test_frameworks and abi_x86_interrupt |
| Target | x86_64-unknown-none (built-in) | bare metal, soft-float (no SSE in the kernel) → no custom target JSON needed |
| Linker | GNU ld (ld.bfd, binutils 2.46), flavor ld | my preference for GNU tools; linker script kernel/linker.ld |
| Architecture | x86_64 | matches the host PC, best documentation (OSDev, Intel SDM) |
| Bootloader | Limine v11, boot protocol base revision 6, crate limine 0.6.5 | starts directly in long mode with paging, provides memory map, HHDM and framebuffer |
| Boot medium | hybrid ISO (BIOS + UEFI) built with xorriso | boots in QEMU with -cdrom, both firmware paths testable |
| External crates | only limine, spin | everything else is written from scratch |
| Tools | GNU make, gdb, binutils (objdump/nm/readelf/addr2line), gcc for host helpers | my preference: Rust kernel, GNU tooling around it |
Memory layout
- The kernel lives in the higher half at
0xffffffff80000000(top 2 GiB),code-model=kernel,relocation-model=static. - Limine additionally maps all physical memory at the HHDM offset (
boot::HHDM): physical addresspis reachable atp + hhdm_offset. - Linker sections:
.limine_requests(between start and end marker),.text,.rodata,.data/.bss, each page-aligned with its own PT_LOAD segment.
Physical memory
mem::pmmis a bitmap allocator: one bit per 4 KiB frame (1 = used), covering physical memory up to the end of the highest usable region.- The bitmap lives in the first usable region big enough for it and is reserved in itself. Frame 0 is never handed out.
- The bitmap covers
USABLEandBOOTLOADER_RECLAIMABLEmemory; the latter starts as used (it holds Limine's stack, page tables and responses) and is handed over bymem::reclaim_bootloader_memory(M33) at the start ofkernel_main: page tables living there are copied (paging::copy_kernel_tables– tables elsewhere are kept and only repointed), every thread's saved CR3 and every CPU's CR3 move to the new PML4, thenpmm::release_regionfrees the frames. Limine responses must not be read afterwards –pmm::initkeeps a copy of the memory map (pmm::boot_memmap). Test kernels other thantests/reclaim.rsdo not reclaim (they still run on Limine's stack). - All access to physical memory goes through the HHDM (
PhysAddr::to_virt). Allocator calls run with interrupts disabled. free_framepanics on double free / invalid addresses – that is always a kernel bug.
Virtual address space
| Range | PML4 slot | Use |
|---|---|---|
0x0000_0000_0000_0000 – 0x0000_7FFF_FFFF_FFFF | 0–255 | user space: private per process (see "User space") |
0xFFFF_8000_0000_0000 + phys | 256 | HHDM (Limine): all RAM + framebuffer, no MMIO |
0xFFFF_FE00_0000_0000 | 508 | kernel heap (grows upward, max 1 GiB) |
0xFFFF_FE80_0000_0000 | 509 | scratch area for paging unit tests |
0xFFFF_FF00_0000_0000 | 510 | kernel stacks: [guard page][stack pages] per stack, never reused |
0xFFFF_FFFF_8000_0000 | 511 | kernel image (linker script) |
paging::ensure_hhdm_mapped(phys, size, flags)maps pages Limine left out of the HHDM (ACPI tables, LAPIC0xFEE0_0000, I/O APIC0xFEC0_0000) at their usual HHDM address, so every physical address is still reached asphys + hhdm_offset.- Page tables: we modify Limine's tables through the HHDM; intermediate tables come from the frame allocator and are not freed.
paging::initremembers Limine's PML4 askernel_root()and creates all 256 upper-half PML4 entries up front (empty PDPTs). Every process PML4 copies these entries, so later kernel mappings (heap growth, new stacks, MMIO) land in shared lower-level tables and are visible in every address space. The PML4 entries themselves never change after boot.- Limine sets the USER bit on its upper-half intermediate tables (leaves are supervisor-only).
paging::initclears USER in all upper-half PML4 entries, so ring 3 cannot reach the kernel half, whatever the lower levels say. - Limine enables EFER.NXE (so
NO_EXECUTEis usable) and CR0.WP (the kernel cannot write read-only pages either). kmainswitches from Limine's stack to a 64 KiB guarded stack (mem::stack) immediately afterkernel::init().
Threads and scheduling
- SMP (since M26):
current[cpu]/idle[cpu]per CPU, one shared ready queue, every CPU's LAPIC timer preempts. Each thread hason_cpu(set while a CPU executes it or is still switching away from it).schedule()takes the scheduler lock, picks the next thread, forgets the guard and switches; the next thread callsfinish_switch(), which clears the previous thread'son_cpuand releases the lock (force_unlock). New threads do that first thing inthread_start. - Blocking:
wait_for(reason, ready)marks the current threadBlocked(reason), then evaluatesready()(interrupts off, scheduler lock not held –readymay take other locks), then schedules. Wakers (notify,wake,make_ready): a blocked thread that is stillon_cpuis set back toRunning(it will see its condition), otherwise it is queued and an idle CPU gets aWAKE_VECTORIPI. Lock order:PROCESSES→SCHEDULER; pipe/keyboard/serial locks are leaves. - TLB: kernel virtual ranges are never reused after unmapping (stacks) or never unmapped (heap), so the kernel half needs
no shootdowns. User pages of a process with threads may be cached on several CPUs:
sys_brkunmaps without freeing (unmap_keeping_frames), callspaging::shoot_down(root)(arun_onjob per CPU that reloads CR3 if it runs inroot) and only then frees the frames. A CPU always reloads CR3 when it switches address spaces. - Sleeping lock (
sync::Mutex, M36): CAS on a flag; a contendedlockblocks onWait::Lock(address)(spins only before the scheduler runs or with interrupts off); unlock notifies when the waiter count is non-zero. Used fordrivers::DISKandfs::ROOT, whose holders block on the AHCI interrupt during I/O. Not for interrupt handlers. task::Scheduler(behind a spin lock, only touched with interrupts disabled):BTreeMap<Tid, Box<Thread>>(boxed so the saved RSP has a stable address), a FIFO ready queue, the current TID and the idle TID. Thread 0 = the boot code ("main"), runs the shell.- Context switch:
kernel_switch_context(old_rsp_ptr, new_rsp)pushes rbp/rbx/r12–r15, swaps RSP, pops,ret. A new thread's stack is prepared so thatretlands inkernel_thread_trampoline, which callsthread_start(entry)with the boxed closure from r12. schedule()must run with interrupts disabled. A resumed thread continues with interrupts off and restores them itself (viawithout_interrupts,iretqof the interrupted handler, orstiinthread_start).- Preemption: every timer tick, if another thread is ready. The timer handler sends EOI first, then calls
task::on_tick. - Wake-ups: timer (
Until), keyboard/COM1 IRQ on the BSP (Input),exit(Join), pipes (Pipe(id)),kill(wake). - Dead threads are reaped (stack unmapped and frames freed) by a later
schedule()call – never while running on their stack.
Storage
- PCI: legacy configuration mechanism (ports 0xCF8/0xCFC), brute-force scan of all bus/device/function numbers.
- AHCI (q35's ICH9 controller, BAR5): one driver instance per port, probed once at boot into
drivers::DISK. Per port: one frame for command list + received FIS, one for the command table (FIS + 1 PRD), one 4 KiB DMA bounce frame. Commands are polled (no interrupts yet) and limited to 8 sectors; larger requests are split. drivers::DISKis a spin lock held with interrupts enabled during I/O – never use it from interrupt handlers.- File systems only see the
BlockDevicetrait (512-byte sectors); tests useRamDisk. - Disk images: FAT32 without partition table ("superfloppy"), 64 MiB, 512-byte clusters (FAT32 needs ≥ 65525 clusters),
created by
scripts/mkdisk.shfromrootfs/. QEMU:-device ide-hd,bus=ide.0= AHCI port 0 (the boot CD is ATAPI on port 2). Run mode uses the persistentbuild/disk.img; every test binary and the E2E test get fresh images.
Disk caching and interrupts (M32)
- The root file system runs on
BlockCache<SystemDisk>: write-through (the disk is always current, a power-off loses nothing), 1024 sectors, LRU eviction of the oldest eighth when full. Runs of missing sectors are fetched with one request. FatFsadditionally keeps the last cluster chain and the last path lookup; any write to the volume drops both.- AHCI: MSI to the boot CPU's LAPIC on vector 0x50; the handler acknowledges all ports, remembers task-file errors per port
and notifies
Wait::Disk. Commands wait withwait_forwhen interrupts are on and the scheduler runs, else they poll. TheDISKlock stays held while waiting (other threads wanting the disk spin; fine for now).
File system
- One FAT32 volume on the system disk, mounted at boot as
fs::ROOT(a spin lock likeDISK: never from interrupt handlers).FatFs<D: BlockDevice>is generic, so the same code runs onSystemDisk(adapter fordrivers::DISK) and onRamDiskin tests. - Mount: FAT32 boot sector at LBA 0 (superfloppy), otherwise the first MBR partition of type 0x0B/0x0C. Only 512-byte sectors.
- Caching: every sector – FAT and data – goes through the write-through
BlockCachebelow the file system (see "Disk caching and interrupts");FatFsitself keeps the FAT sector it used last, the last cluster chain and the last path lookup. FAT updates are written through to every FAT copy immediately. Every mutating operation ends withsync(FSInfo hints + disk flush), so apoweroffor reset right after a command never leaves the volume inconsistent. A power loss or disk error during a command is a different case. What holds then is measured (M53,fs::fat32::fault_tests: every I/O of create, replace, append,write_at, mkdir, rename and remove made to fail once, as a transient error and as a power loss with a torn write, then the volume re-mounted and checked):- the command returns
FsError::Io, never panics, and the volume mounts again; - files the command did not touch are intact; its target is in the old or the new state (
write_atmay have written part of its bytes); - the damage is what
fsck.fatrepairs without losing data that was there before: lost clusters (new clusters not yet in a directory entry, or old ones not yet freed), the two FAT copies differing in one sector, after append/write_ata chain longer than the file size, after rename both names pointing to the same clusters (the new entry is written before the old one is freed – the order Linux's vfat uses too); - after a transient error the same mount keeps working (later writes do not damage the volume).
There is no journal: FAT32 has none, and the kernel does not run
fsckat boot.
- the command returns
- Names: a name that fits 8.3 in one case per part (
hello.txt,README) is stored as a plain short entry with the NT lower-case flags, like Windows/Linux do. Everything else gets LFN entries plus a unique 8.3 alias (MYNOTE~1). Lookup is case-insensitive on long and short names. - Paths at the FS API are absolute and normalized (
/a/b); the shell owns the current directory and callsfs::normalize. rmrefuses non-empty directories;mvonly rewrites directory entries (and the..entry of moved directories).- Timestamps come from the CMOS RTC (
drivers/rtc.rs, treated as UTC). - Validation outside the kernel: after
make test,scripts/check-test-disks.shrunsfsck.fat -non every test disk and checks kernel-written files with mtools; the E2E test does the same for its disk after two boots.
User space
- Address space (
mem::address_space::AddressSpace): own PML4, user half empty, kernel half shared. Frames are filled via the HHDM, so loading never switches CR3.Dropfrees every user frame and page table (paging::free_user_half); all user mappings own their frames. It must not be the active address space when dropped. - User layout: ELF segments between
USER_IMAGE_START(64 KiB, null page area stays unmapped) andUSER_IMAGE_END; our programs link at0x40_0000. The heap starts at the first page after the image and is moved withbrk(max 64 MiB). Stack: up to 1 MiB (USER_STACK_MAX) belowUSER_STACK_TOP = 0x7FFF_FFFF_0000, the top 4 pages mapped at start, the rest on demand (M35); nothing is mapped below it (overflow → page fault → process killed). Below that gap: 64 thread stack slots (M52), each[64 KiB guard][256 KiB stack]; a slot belongs to a thread started withthread_spawn(entry, 0, arg), its stack pages are demand-paged, the guard never. A fault in a guard kills the process with "stack overflow in a thread". Slots of ended threads are unmapped (TLB shoot-down first) at the nextthread_spawnorthread_join.USER_IMAGE_ENDleaves room for the largest heap plus a guard below the slots (bug #21). The argument block is copied to the stack top;_startgets pointer and length in RDI/RSI. Arguments inside the block are separated by NUL bytes (ulib::Args); the shell joins its words that way. - ELF loader (
process::elf): staticET_EXECx86_64 only,PT_LOADsegments with R/W/X → USER, WRITABLE, NO_EXECUTE. Every header field is bounds-checked; segments outside the user image area or an entry point outside an X segment are refused. - Processes (
process::PROCESSES, interrupts off while locked): one kernel thread per process.task::spawn_usercreates a thread with its own CR3 and aUserEntry;thread_startdrops the closure and theniretqs to ring 3 (enter_user). The thread's kernel stack is abandoned at that point and reused from its top by every interrupt/syscall from ring 3. - Scheduler: each thread has
cr3; on a switch the scheduler loads it (if different) and sets TSS.RSP0 + the syscall stack to the next thread's kernel stack top (syscall::set_kernel_stack). Switching CR3 on the old thread's stack is fine: kernel stacks are in the shared half. - End of a process:
exitsyscall, CPU exception with CS.RPL = 3 (handlers callprocess::kill_currentinstead of panicking), or a fatal signal (process::deliver_signals, run when the timer/wake IPI interrupts user code and on every syscall return).exit_currentrecords the status, moves the thread to the kernel CR3, frees the address space and exits the thread. The status stays in the table untilprocess::wait(zombie); the shell always waits. - System calls (
syscall/sysret): STAR = kernel CS 0x08 / sysret base 0x10, LSTAR =syscall_entry, FMASK clears IF/TF/DF/AC. The stub doesswapgs(IA32_KERNEL_GS_BASE = this CPU'sCpuLocal), parks the user RSP ings:[0], loads the kernel stack fromgs:[8], pushes the user RSP and swaps GS back before enabling interrupts (a preempted syscall may resume on another CPU, so GS must never stay swapped), saves aSyscallFrame, enables interrupts and callsprocess::syscall::dispatch. Convention like Linux: number in RAX, args in RDI/RSI/RDX/R10/R8/R9, result in RAX, negative =-errno; only RCX/R11 are clobbered. Syscalls may block (read, sleep).# Name 0 exit(code)never returns 1 write(fd, buf, len)fd 1/2 → console (or a capture buffer in tests) 2 read(fd, buf, len)fd 0 → keyboard/serial keys as terminal bytes ( \n,0x08, UTF-8), blocks for ≥ 1 byte3 sleep_ms(ms)-EINTRwhen a signal arrives4 getpid()5 uptime_ms()6 yield()7 open(path, len, flags)flags READ=1, WRITE=2, CREATE=4, TRUNCATE=8, APPEND=16; a directory opens for readdir8 close(fd)9 readdir(fd, *DirEntryInfo)1 = entry written, 0 = end; 296-byte repr(C)struct shared withulib10 stat(path, len, *Stat)32-byte repr(C): size, kind (1 file, 2 dir), modified time11 getcwd(buf, len)-ERANGEif too small12 unlink(path, len)files and empty directories 13 mkdir(path, len)14 brk(new_end)0 = query; growing only moves the end (pages come on first touch), shrinking frees used pages; -ENOMEMoutside the range15 spawn(path, len, args, args_len)4th argument in R10; child inherits cwd and output; -ENOENT,-ENOEXEC,-E2BIG16 wait(pid, *WaitStatus)children only ( -ECHILD); 128-byte status: kind (1 exited, 2 killed), code (exit code / signal number), kill reason17 kill(pid, sig)any user process ( -ESRCH); sig 0 = existence check18 chdir(path, len)-ENOTDIRfor files19 kshell(line, len)transitional: runs a kernel shell built-in (not cd/pwd/history/run) in the caller's cwd and output 20 kcommands(buf, len)NUL-separated names usable with kshell21 pipe(*[u32; 2])read end, write end 22 dup(fd)lowest free fd for the same object 23 dup2(fd, new_fd)closes what was at new_fd24 isatty(fd)1 for the console (stdin, stdout to the console), else 0 25 sysinfo(*SysInfo)176 bytes: uptime, ticks, memory, kernel heap, FS size/free/label, CPUs, CPU vendor/brand, date 26 proclist(*[ProcInfo], max)one 64-byte entry per thread (tid, cpu ticks, parent, state, user?, name) 27 rename(from, len, to, len)28 seek(fd, offset, whence)SET/CUR/END for files, -ESPIPEotherwise; past the end is allowed (gap = zeros on write)29 termsize()console rows << 32 | columns (the serial side has no size; programs draw for the console) 30 ignore_interrupt(on)Ctrl+C arrives as 0x03 instead of killing the caller (the editor) 31 net_info(*NetInfo)40 bytes: MAC, link, IPv4, netmask, gateway, frame counters; -ENODEVwithout a card32 ping(ip, seq, timeout_ms)round trip in µs; -ETIMEDOUT,-EHOSTUNREACH33 udp_socket(port)0 = ephemeral (≥ 0xC000); -EADDRINUSE34 sendto(fd, buf, len, ip, port)≤ 1472 bytes, -EMSGSIZEabove35 recvfrom(fd, buf, len, *SockAddr, timeout_ms)5th argument in R8; -ETIMEDOUT,-EINTR36 clock_us()microseconds since boot (TSC) 37–43 TCP, shutdown,setenv/getenv/environsee kernel/src/process/syscall.rs44 sigaction(sig, disposition, trampoline)SIG_DFL0,SIG_IGN1 or a handler; old disposition; SIGKILL →-EINVAL45 sigreturn()called by the trampoline when a handler returns (unblocks the next one) 46 thread_spawn(entry, stack, arg)tid; ≤ 64 running further threads ( -EAGAIN); entry/stack must be user addresses; stack 0 = a kernel slot with a guard47 thread_exit(code)ends the thread; in the main thread the process 48 thread_join(tid)exit code as u32; -ESRCHif not a further thread of the caller or already joined49 futex_wait(addr, expected, timeout_ms)-EAGAINif*addr != expected,-ETIMEDOUT,-EINTR50 futex_wake(addr, n)number of threads woken 51 gettid()getpid()returns the process id in every thread52 uname(buf, len)"YAK x86_64", -ERANGEiflenis too small (the example ofdocs/HACKING.md) /bin/edit:buffer.rsis pure logic (tested byedit --selftest),main.rsdraws withESC[r;cH,ESC[K, SGR 7. The text area is all rows but the last; the cursor line and the status bar are redrawn per key, the whole screen only after scrolling or when lines are inserted/removed. Writing the bottom-right cell is safe: the console wraps lazily (only when the next character comes).- Pipes (
process::pipe): bounded queue (64 KiB) + reader/writer counts. A descriptor holds aPipeEnd;Clone(dup, dup2, spawn) increments,Drop(close, process exit) decrements and notifies. Read blocks while empty with writers, returns 0 without; write blocks while full with readers,EPIPEwithout. Waiters sleep onWait::Pipe(id); the pipe lock is only taken with interrupts disabled (descriptors are dropped under the process table lock). Kills abort the wait (EINTR). - Descriptor inheritance:
spawnclones the parent's fds 0–2 into the child (other fds are not inherited). A shell redirects bydup2-ing a pipe end or file over 0/1 beforespawnand restoring its saved copies afterwards. - Process tree:
parent(None = started by the kernel; only the kernel waits for those). When a process ends, finished children are dropped and running ones become orphans, removed from the table at their own exit (nobody waits for them). - Threads (M36):
thread_spawn(entry, stack, arg)starts a kernel thread with the process's CR3 whoseowneris the main thread;task::current_owner()is the pid, sowith_current,getpid, files and signals are per process.Process::threadsmaps further tids toNone(running) / exit code (untilthread_join). The end of a process (exitin any thread, a fatal signal or a fault) setsexiting;signal_pending()is then true for every thread (blocking calls give up) anddeliver_signalssends any thread that is about to enter ring 3 intoexit_current. A further thread just wakes the others and exits; the main thread joins all further threads, then records the status, frees the address space and exits – sowait(which joins the main thread) only returns when every thread is gone. Signals are taken by whichever thread returns to user mode first. - Futexes (
process/futex.rs):futex_wait(addr, expected, timeout)reads the word under theFUTEXESlock (insidewith_current, so no other thread can unmap it meanwhile), queues the thread under the key (pid << 47 | addr) and blocks (Wait::Futex, orWait::Untilwith a timeout);futex_wake(addr, n)moves up to n waiters to thewokenset andtask::wakes them.ulib::sync::RawLock(0 free / 1 locked / 2 contended) only calls the kernel when contended; the user heap uses it,ulib::thread::spawnasks for a kernel stack slot (256 KiB with a guard, see "User layout"). - Signals (M34,
process/signal.rs): per process a disposition per signal (default = end, ignore, handler), a pending mask and anin_handlerflag.send_signalsets the bit andtask::wakes the target; blocking syscalls use abortable waits (input::read_key_or_abort,task::join_or_abort,time::sleep_ms_or_abort, pipes, sockets) that give up whensignal_pending()and returnEINTR. Delivery happens on the way back to ring 3 – at the end ofdispatch(it may changeSyscallFrame.rip/rsp) and in the timer / wake-IPI handlers (they change the CPU-pushedInterruptStackFramewith volatile writes). SIGKILL first, then the lowest pending signal; default →kill_current(reason)(exit statusKilled(reason),waitreports the number viasignal::number_for_reason, exceptions = SIGSEGV). - Handlers without a kernel register frame: the kernel only pushes
sig, handler, rflags, ripbelow the user RSP and jumps to the trampoline registered withsigaction(ulib::signal). The trampoline pushes all 15 GPRs and XSAVEs (or FXSAVEs), calls the handler, callssigreturn, restores everything and ends withpopfq; ret(which also restores RSP). So neither the syscall stub nor the interrupt handlers need a full register frame. Price: no red zone in user code (the target setsdisable-redzone; the kernel writes right below RSP). While a handler runs, further handled signals stay pending (default actions still happen); a signal arriving during the trampoline's epilogue nests safely, because everything below RSP has been consumed by then. The trampoline must be a user address (< USER_END, it becomes asysrettarget).spawnresets handlers but keeps ignored signals (likeexec).FOREGROUND= pid owning the console: set by the kernel shell for its programs, inherited byprocess::wait_childwhile the foreground process waits for that child (handed back when the wait ends);spawnalone never changes it (bug #4). The keyboard and COM1 interrupt handlers recognise Ctrl+C themselves (raw 0x03 / Ctrl tracker on set-1 scancodes, the C key is 0x2E on QWERTY and QWERTZ) and callprocess::interrupt_foreground: the key is swallowed and SIGINT sent (default: killed, "interrupted"), unless the process hasignore_interruptand no SIGINT handler – then the key reaches it as byte 0x03. - init:
kernel_mainrunsprocess::run_init("/bin/sh")(foreground,ignore_interrupt) and waits; when it is missing or exits, the kernel shell runs on thread 0 as before. /bin/sh(user/src/bin/sh/): compiles the kernel'sshell/line_editor.rsandshell/parser.rswith#[path]; both sides provide akeysmodule (Key,KeyEvent) next to them. Pipelines: for each stage, stdin = previous pipe (or<file), stdout = new pipe (or>/>>file), then the stage runs (built-in inline, program spawned); all children are waited for in order, only the last exit code is reported, kills always; an "interrupted" stage kills the rest.read(0)delivers keys as terminal bytes (VT100 sequences for arrows, Home/End, Delete, PageUp/Down, Insert);keys::Decoderturns them back intoKeyEvents. Order of lookup: sh built-ins, functions, kernel built-ins (kshell), program path /$PATH.- sh grammar (M35,
syntax.rs): the text is tokenized into raw words (quotes kept,$((...))one word) and separators, then parsed intoList→AndOr→Pipeline→Command(simple / compound + redirections / function definition). Words are expanded only when a command runs (expand_words: variables, arithmetic, wildcards, then the kernel'sparser::split), so loops see new values. Interactive input that parses asIncomplete(open quote, missingfi/done/}) continues with the prompt>; scripts andsh -care parsed as a whole first. Execution returns aFlow(Next,Exit,Break(n),Continue(n),Return,Interrupted) up the call chain. Compound commands and functions in a pipeline run inside the shell like built-ins.set -eis ignored insideif/whileconditions and for all but the last pipeline of&&/||. Ctrl+C: the shell's SIGINT handler (and a child killed by SIGINT) setsINTERRUPTED, which every list and loop checks; at the prompt the line is cancelled. Wildcards: the expander marks unquoted*/?with private-use characters,glob.rsmatches them per path component. - Command substitution and
"$@"(M55):$(...)stays inside its word when tokenizing (syntax::subst_endskips quotes and nested parentheses). At expansionShell::substituteparses the text and runs it in the shell with stdout on a pipe, while a second thread (ulib::thread) drains the pipe – so the output can exceed the 64 KiB pipe. Afterwards variables, the directory, functions and$@are restored, which gives subshell semantics without a new process (functions keep working inside);exitends only the substitution,$?is its last status. Because expansion produces text thatparser::splitsplits again, substituted output and arguments are inserted quoted: in double quotes as one escaped string, unquoted as one quoted word per field, afterNAME=as one word (no splitting)."$@"closes and reopens the quotes between the arguments; without arguments it produces no word. Variables live in the kernel's per-process environment: values up to 4096 bytes, up to 256 variables – a larger assignment is an error. caseandlocal(M56):;;is its own token; a pattern is a raw word ending in)(an optional leading(, alternatives split at unquoted|), its body a list ended by;;oresac. Subject and patterns are expanded without splitting; unquoted*/?in a pattern are wildcards (glob::matches), no[...]classes.localrecords the variable's old value in the running function's frame (Shell::locals);callrestores the frame in reverse order when the function returns, so nested functions see the caller's locals (dynamic scope, like bash).- Files: each process has a cwd (inherited from the spawner, paths are normalized against it) and up to 32 file descriptors
(
process::Handle): 0 stdin, 1/2 the process'sOutput, then files (path + one offset for reads and writes, shared withdup-ed and inherited copies like a POSIX open file description – the shell's save/restore of fds 0-2 depends on it; writes useFatFs::write_at, orappend_filewith the APPEND flag) and directories (snapshot of the entries atopen). Handlers copy what they need out of the table, do the disk I/O without holdingPROCESSES(onlyfs::ROOT), then update the descriptor.readof a file usesFatFs::read_at, ≤ 64 KiB per call. FS errors map to Linux errno values (ENOENT,EISDIR, ...). - User pointers: every buffer is checked page by page against the process's page tables (present + USER, + WRITABLE for
read) before the kernel touches it; then it is accessed directly (the process CR3 is active) insidecpu::user_access(M37): with SMAP that isstac…clac, the only window in which the kernel may touch user pages (copy_from_user,copy_to_user, the futex read). SMEP keeps the kernel from executing user pages. Both are enabled per CPU bycpu::enable_protectionwhen CPUID has them; QEMU runs-cpu max(TCG) so they are there (KERNEL_CPU=qemu64runs without SMEP/SMAP/XSAVE/AVX - the fallback paths).tests/smap.rschecks that a kernel read and a kernel jump into a user page fault. - User programs (
user/, crateulib+src/bin/*): own targetuser/x86_64-yak-user.json(x86-64 with SSE2 and the normal hard-float ABI, static,code-model=small, red zone allowed – interrupts from ring 3 switch stacks), built with-Zbuild-std=core,alloc(+compiler-builtins-mem; needsrust-srcandgccas host linker for build scripts), linked by GNU ld at0x40_0000(user/linker.ld).make usercopies them tobuild/user/bin;scripts/mkdisk.shand (for the persistent disk)run-qemu.shinstall them into/binviascripts/install-user.sh. - User heap (
ulib::heap): first-fit allocator, free list sorted by address with coalescing, 16-byte units, grows the break by ≥ 64 KiB at a time. No lock (programs are single-threaded). - Demand paging (M33, stack since M35): the heap
[heap_start, align_up(heap_end))and the stack area are only reserved ranges. A user page fault with the present bit clear inside it maps one zeroed RW/NX page (process::handle_page_fault, called first in the page-fault handler) and returns, so the instruction is retried; any other fault, or no free frame, kills the program as before. Syscalls callProcess::populatefor user buffers beforeis_accessible, so the kernel never faults on them. - Environment (M31):
Process::env(BTreeMap), copied into children byspawn; syscallssetenv/getenv/environ./bin/shkeeps no variables of its own – shell variables are environment variables. - Shell: a word that is not a built-in is a program path or a name in
/bin;run <path> [args]does the same explicitly. Programs run in the shell's cwd.ls,catandcpare programs (no built-ins any more). Non-zero exit codes and kills are reported as errors.Shell::capture_programsmakes program output go to the command'sout(unit tests). - FPU/SSE/AVX (
arch::x86_64::fpu): the kernel is soft-float and never uses x87/MMX/XMM/YMM, so user register contents survive syscalls and interrupts untouched. Each thread has a boxed, 64-byte aligned 1 KiBFpuState(initialised from a clean image taken afterfninit+ldmxcsr 0x1F80);schedule()saves the outgoing (unless dead) and restores the incoming thread's state right beforekernel_switch_context. With XSAVE (M37): CR4.OSXSAVE, XCR0 = x87 | SSE | AVX (set byxsetbvon every CPU),xsave64/xrstor64with the XCR0 mask, area size from CPUID 0xD (832 bytes, must fit 1 KiB); without XSAVEfxsave64/fxrstor64. No lazy switching (CR0.TS stays clear), no AVX-512. - User programs and AVX: the user target stays at SSE2, so every program runs on any CPU; code that wants AVX checks
ulib::avx_enabled()(CPUID OSXSAVE + XCR0) and uses#[target_feature(enable = "avx")](fputest,sigtest). The signal trampoline saves withxsave64(header zeroed first) whenulib::XSAVE_ENABLED.
Time
time::ticks(100 Hz, boot CPU's LAPIC timer) for sleeping and timeouts;time::uptime_usfrom the TSC (frequency measured at boot against PIT channel 2) for precise time stamps. All CPUs' TSCs are assumed to run in step.
Network
- Driver (
drivers/e1000.rs): Intel 82540EM as emulated by QEMU, BAR0 MMIO (128 KiB, mapped viaensure_hhdm_mapped). RX ring 32 × 16-byte descriptors (one frame), TX ring 8; DMA buffers 2 KiB (two per frame). RCTL: broadcast accepted, CRC stripped; TCTL: pad short packets. TX descriptors start with DD set so "DD = slot free". Interrupts (M38): no MSI on this model, and the INTA# → I/O APIC wiring would need the ACPI_PRT(AML).net::probe_irqroutes each free PCI input (GSI 16-23, level-triggered, active low) in turn to vector 0x51 and makes the card raise "link status change" by software (ICS); the input where it arrives is kept. The handler readsICRthrough a register base saved at probe time (no NIC lock: the net thread holds it with interrupts on), which clears the causes and releases the level-triggered line, setsRX_PENDINGand wakes the net thread. Enabled causes: RXT0, RXO, RXDMT0, LSC. No interrupt found → polling. - Stack (
net/): configured by DHCP at boot (net/dhcp.rs), static fallback = QEMU's slirp defaults (10.0.2.15/24, gateway and host = 10.0.2.2, DNS 10.0.2.3). TCP (net/tcp.rs) is described in its module docs; packets to our own address go through a loopback queue handled by the net thread. DNS is a user-space library (ulib::dns). Thenetkernel thread runs a round when the card interrupts or a packet is looped back (RX_PENDING+task::wake), at the latest every 10 ms; each round ends withnotify(Wait::Net)– that doubles as the tick for timeouts of everyone waiting on the network and for TCP's retransmission timer. Ping to the gateway: ~0.5 ms (polled: 0-10 ms). - DHCP lease (
net/dhcp.rs): the "dhcp" thread renews at T1 (unicast REQUEST withciaddr), retries after half the remaining time (≥ 60 s), rebinds by broadcast from T2, falls back to the static configuration at the end. - TCP windows (M38): window scaling (RFC 7323, shift 3) when both SYNs carry the option; receive and send buffers
256 KiB, up to 128 segments in flight. ARP: cache learned from requests/replies addressed to us and from IPv4 packets of on-link hosts;
resolvesends up to 3 requests. IPv4: no options sent, fragments dropped, DF set. ICMP: echo requests answered, replies with our id recorded. UDP: ports map to bounded queues (64 datagrams); checksums sent and verified on receipt (a datagram with a wrong checksum is dropped; checksum 0 = "none computed" is accepted, as RFC 768 allows for IPv4). - Network faults (M58):
net::set_loopback_loss(n, phase)drops every n-th packet sent to ourselves (always compiled, off by default – an atomic load per loopback packet);tcp::set_max_retrieslowers the retry limit (default 8),tcp::retransmissionscounts expired retransmission timeouts.kernel/tests/netfault.rschecks with them: with every 10th packet lost (first loss = SYN, SYN-ACK or the first ACK) an echo of 8 KB comes back intact; a connect into silence fails withTimedOutafter its timeout; a peer that goes silent ends the connection after the retries (measured 3.0 s for 3 retries from a 200 ms timeout: 0.2 + 0.4 + 0.8 + 1.6 s). Without an RTT sample (only the handshake was acknowledged) the timeout starts at 1 s – with the default 8 retries a dead peer is noticed after about a minute. DNS (ulib::dns) is checked against a name server that misbehaves (E2E): NXDOMAIN, server failure, an answer without A record, a stray and a truncated reply before the real one, and silence (3 tries of 1.5 s, then "timed out"). - User API:
ping(one echo, waits ≤ timeout),udp_socket→Handle::Udp(Arc<UdpSocket>)(port released when the last descriptor closes),sendto/recvfrom(timeout, abortable by kill),net_info. Small state locks are taken with interrupts off; the NIC lock with interrupts on (it is never needed bywait_forconditions).
Kernel heap
mem::heap::LinkedListHeap: free blocks form a singly linked list sorted by address; each free block storessize+nextin its first 16 bytes.- First fit; a block is split into [front padding][allocation][rest], padding and rest go back to the list. Freeing inserts by address and merges neighbours.
- All addresses and sizes are multiples of 16, so leftovers are either 0 or big enough for a header (no lost bytes).
KernelHeapwraps it in a spin lock (interrupts disabled while held) and grows by mapping ≥64 KiB at the heap end when an allocation fails.- Allocation failure → null → Rust's default alloc error handler panics.
SMP (multiple cores)
arch::x86_64::smp::init(end ofkernel::init): every enabled MADT CPU except the BSP gets INIT, 10 ms, SIPI(s), one at a time. Trampoline: one frame below 1 MiB reserved bypmmat boot (pmm::low_frame), identity-mapped in the kernel PML4 only while APs start. It uses its own tiny GDT (code32/data32/code64/data64), sets PAE, CR3 = kernel PML4 (must be < 4 GiB), EFER.LME + NXE, CR0.PG + WP, and callsap_main(cpu)on a 64 KiB guarded stack.- CPU index:
smp::cpu_index()maps the local APIC ID to 0..MAX_CPUS-1 (BSP = 0; 0 before the LAPIC is set up). Used for the per-CPU TSS. (M26 will move this to a GS-based per-CPU block.) - APs (M25): own GDT/TSS (+ double fault IST stack), shared IDT, FPU/SSE, syscall MSRs, LAPIC (timer masked); they idle with
sti; hltand run jobs from a per-CPU mailbox (run_on, woken by an IPI onWAKE_VECTOR0xF0). Since M26 every AP also runs threads (its start-up context becomes its idle thread, its LAPIC timer preempts). Device IRQs (keyboard, COM1) stay on the BSP.
GDT / TSS
| Selector | Entry |
|---|---|
| 0x00 | null |
| 0x08 | kernel code (64-bit, DPL 0) |
| 0x10 | kernel data (DPL 0), also used for SS/DS/ES/FS/GS |
| 0x18 | user data (DPL 3), selector 0x1B with RPL 3 |
| 0x20 | user code (64-bit, DPL 3), selector 0x23 |
| 0x28 | TSS (16 bytes, occupies 2 slots) |
One GDT and TSS per CPU (gdt::init_cpu), same layout everywhere. The user data/code order is dictated by sysret (SS = STAR base + 8, CS = base + 16). IST1 (gdt::DOUBLE_FAULT_IST) =
20 KiB static stack for double faults. RSP0 = kernel stack of the running thread, rewritten on every context switch.
Interrupt vectors
| Vector | What |
|---|---|
| 0–31 | CPU exceptions (arch/x86_64/interrupts.rs), double fault (8) on IST1 |
| 32 | local APIC timer, periodic 100 Hz (drives time::tick) |
| 33 | ISA IRQ1 – PS/2 keyboard (I/O APIC GSI 1) |
| 36 | ISA IRQ4 – COM1 receive (I/O APIC GSI 4) |
| 39 / 47 | spurious IRQ 7 / 15 of the masked 8259 (ignored, no EOI) |
| 0x50 | AHCI command completion (MSI, M32) |
| 0x51 | e1000 (INTA# through the I/O APIC input found by net::probe_irq, level / active low, M38) |
| 0xF0 | wake-up IPI between CPUs (smp::WAKE_VECTOR) |
| 0xF1 | TLB shootdown IPI (smp::TLB_VECTOR, M41): reload CR3 if running the given address space |
| 0xFF | local APIC spurious vector (ignored, no EOI) |
- Interrupt controllers: local APIC + I/O APIC (since M12). Information comes from the ACPI MADT (
acpi.rs). ISA IRQnis delivered on vector32 + n; the GSI and polarity/trigger come from the MADT interrupt source overrides (QEMU: IRQ0 → GSI 2). All handlers acknowledge withlapic::eoi(). - The 8259 PICs are remapped to 32–47 and then fully masked (never deliver anything). PIT channel 0 is not used; PIT channel 2 (polled via port 0x61) only serves as the reference clock to calibrate the LAPIC timer at boot.
- LAPIC LINT0 is masked (no ExtINT from the 8259), LINT1 = NMI. Registers are reached through the HHDM after
ensure_hhdm_mapped(.., Flags::MMIO). kernel::init()enables interrupts withstiat the very end. Anything holding a lock that a handler also takes must usewithout_interrupts.- Handlers use
extern "x86-interrupt"(nightlyabi_x86_interrupt): the compiler saves registers and emitsiretq. The IDT structure and all gate descriptors are our own code. interrupts::install_exception_handlers(&mut Idt)is separate frominit(); tests build their own IDTs (seetests/page_fault.rs).- Address
0x0000_4000_0000_0000(lower half) is unmapped under Limine and is used by tests as a "guaranteed to fault" address.
Keyboard
- The IRQ1 handler only reads port 0x60 and pushes the byte into a
RingBuffer<128>; translation happens outside the interrupt indrivers::scancode::Decoder. - Scancode set 1 (the 8042 controller translates by default). Layout switchable (
keyboard::set_layout), default DE. QEMU forwards physical keys, so the kernel layout must match the user's real keyboard. keyboard::inject_scancode()feeds bytes without hardware (tests, later e.g. serial input).
Input and shell
- Two input sources, one API:
input::read_key()returnsKeyEvents from the PS/2 keyboard (scancode decoder) or from COM1 (TerminalDecoder: UTF-8, CR/LF, DEL, Ctrl+letter, ANSI arrows/Home/End/Delete). It sleeps race-free withsti; hlt. - The line editor only emits a terminal-compatible byte stream (
\x08= cursor left, characters overwrite,ESC[nA/B/Cfor up/down/right), so the same output works on the framebuffer console and on a serial terminal. Lines up to 4096 characters span several rows (M57): the editor knows the width (set_width: console columns,termsizein/bin/sh) and the prompt's visible width, maps every buffer position to (row, column) and moves across rows withESC[nA/ESC[nB\r+ESC[nC– a backspace never crosses a row. After a character in the last column, terminals keep the cursor there ("pending wrap"); output that ends at a row boundary is followed by" \r", which puts the cursor at the next row's start on every terminal. The unit tests run every edit on two simulated terminals (our console's and xterm's pending-wrap behaviour) and require the same picture. Limit: the width is the console's – a serial terminal narrower than 160 columns shows lines longer than its width wrongly.
- Commands are a static table (
shell::COMMANDS) offn(&mut Shell, &[String], &mut dyn Write) -> Result<(), String>; unit tests run them against aString. Errors are printed in red by the shell, not by the commands. poweroff: ACPI PM1a control port 0x604 (QEMU q35), fallback isa-debug-exit.reboot: 8042 reset line, fallback triple fault.
Output
serial_println!: COM1 only.println!: console and COM1. Both disable interrupts while holding their lock (without_interrupts).- The boot binary's panic handler (
kernel::panic_report) prints to serial and, ifCONSOLE.try_lock()succeeds, in red on the screen. - Console: keeps a
Vec<Cell>character grid (char + colours) for redrawing the cursor cell; cursor = inverted cell. ANSI subset:ESC[2J,ESC[H,ESC[row;colH,ESC[K,ESC[..m(0, 1, 22, 30–37, 39, 40–47, 49, 90–97). - Console: works on a
Surface(32 bpp, stride in pixels). Scrolling copies pixel rows inside the framebuffer (slow on real hardware, fine in QEMU). Font: Terminus 8×16 (PSF2) viainclude_bytes!; Latin-1 characters through the Unicode table, unknown characters become?.
Testing
- Crate layout:
src/lib.rscontains the whole kernel,src/main.rsonlykmain+ panic handler. Every test binary (lib unit tests,tests/*.rs) defines its ownkmain; the linker usesENTRY(kmain)for all of them. - Unit tests:
#[test_case]inside the module. Integration tests:kernel/tests/<name>.rswith their own harness setup (seetests/boot.rs). Tests that must panic or fault getharness = falseinCargo.toml(seetests/should_panic.rs). scripts/run-qemu.shis the cargo runner. A hash suffix in the ELF name means test binary → headless QEMU with a timeout.- Result via the
isa-debug-exitdevice on port 0xF4: value 0x10 → QEMU exit status 33 = PASS, 0x11 → 35 = FAIL. - All test output goes through COM1 (
serial_println!). scripts/e2e-shell.py(make e2e) boots the real kernel with stdin/stdout on COM1, types commands (incl. escape sequences) and checks the output between prompts; the finalpoweroffmust end QEMU.make check=make deps+make test+make e2e+make e2e-uefi.- Robustness (M41):
/bin/syscheckcalls every syscall with bad arguments and races user copies againstbrk;make soak(scripts/soak.py+rootfs/soak.sh) runs a mixed workload forSOAK_ROUNDSrounds;make stressruns the suiteSTRESS_Ntimes with 1/2/4 CPUs,qemu64and UEFI, then a soak run. - User memory is only touched in
copy_from_user/copy_to_user: check and copy under the process table lock, in pieces of ≤ 64 KiB (bug #14). Empty buffers are never dereferenced (bug #12).
Bug log
Format: number · date · title, then symptom → cause → fix → test.
#1 · 2026-10-24 · Passing test reported as failure
- Symptom:
make testprints "All tests passed.", but cargo reportsexit status: 33. - Cause:
run-qemu.shdetected test binaries by the path*/deps/*. Current cargo nightly (1.101) places them undertarget/<triple>/debug/build/<pkg>/<hash>/out/instead, so the runner used run mode and passed the raw exit status 33 through. - Fix: detect test mode by the hash suffix in the file name (
-[0-9a-f]{16}$), which works with both layouts. - Test:
make test→ 3× PASS, exit status 0. Counter-check with a deliberately wrong assert → FAIL, exit status 35.
#2 · 2026-10-24 · Timer interrupt never arrives (test hangs in sleep_ms)
- Symptom:
sleep_msnever returns, test timeout.-d intshows not a single vector 0x20 although RFLAGS.IF = 1. - Diagnosis: QEMU monitor
info pic→pic0: irr=01 imr=fe irq_base=20, so the PIC correctly has the IRQ pending.info lapic→LVT0 0x00018700 … masked ExtINT: Limine masks LINT0 of the local APIC, which is exactly where PIC interrupts enter. - Fix:
lapic::disable()clears bit 11 (global enable) in MSRIA32_APIC_BASE, so PIC interrupts go directly to the CPU's INTR pin. - Test:
irq::tests::local_apic_disabled_for_pic_mode,timer_ticks_advance,sleep_waits_roughly. Verified with BIOS and UEFI. - Update (M12): superseded – the kernel now uses the local APIC + I/O APIC and masks LINT0 on purpose; the 8259 is fully masked.
- Update (C6): the fix depends on the QEMU version – QEMU 8.2 drops PIC interrupts at the masked LINT0 even with the APIC disabled (bug #25).
- Remember: when interrupts do not arrive, look at
info pic/info lapicfirst:python3 -I scripts/qemu-monitor.py <elf> [s] -- "info pic" "info lapic".
#3 · 2026-10-24 · hexdump 0 shows IDENTIFY data instead of the boot sector
- Symptom: in the test run, reading sector 0 through the global disk returned the drive's IDENTIFY data ("QM0000 1" serial number).
- Cause: AHCI unit tests called
ahci::probe()again. Re-initializing port 0 pointed its command-list/FIS registers at the test's new frames; the globalAhciDiskkept filling its old (now ignored) command list, so the HBA executed stale commands and the data landed in another bounce buffer. - Fix:
probe()refuses to run twice (PROBEDflag); tests use the globaldrivers::DISK. - Test:
ahci::tests::probing_twice_is_refused,shell::tests::hexdump_shows_boot_signature. - Remember: hardware state is global – a device must have exactly one driver instance.
#4 · 2026-10-24 · Ctrl+C stops working in /bin/sh after spawntest
- Symptom: E2E step
fault spin+ Ctrl+C hung under/bin/sh– the spinner was never killed. - Cause: children of the foreground process inherited the foreground at spawn.
spawnteststarts an orphan (hello) that nobody waits for; it took the foreground, and when it ended the foreground fell back to its dead parent → 0. From then on nobody owned the console, sosh's children were not foreground either and Ctrl+C arrived as a plain byte. - Fix: the console is lent only while a foreground process waits for a child (
process::wait_child) and returned when the wait ends – like a real shell'stcsetpgrp.spawnnever changes the foreground. - Test: E2E
spawntestfollowed byfault spin<pause>^C,fault sleep<pause>^C,upper<pause>^C(all under/bin/sh). - Remember: "who owns the console" must follow who is waiting, not who was started.
#5 · 2026-10-24 · smp::run_on hangs once more threads exist
- Symptom: after the network thread was added, the unit test
jobs_run_on_their_cputimed out. - Cause:
run_onwaited for the job withyield_now()in a loop. If the waiting thread happened to run on the target CPU itself, it was always ready there, so that CPU's idle thread – the one that executes jobs – was never scheduled. On an otherwise idle system the thread rarely ended up there; more scheduling activity made it likely. - Fix: wait by blocking (
time::sleep_ms(1)), which lets the target CPU's idle thread run. - Test:
smp::tests::jobs_run_on_their_cpu(now stable with the net thread running). - Remember: a busy-yield loop is not waiting – a ready thread starves the idle thread of its CPU.
#6 · 2026-10-25 · run_on(0, …) hangs sometimes (about 1 in 15 test runs)
- Symptom:
jobs_run_on_their_cputimed out now and then; all CPUs were idle inhlt. - Cause: only the APs' idle loop ran jobs. Since M26 the calling thread may run on an AP, and a job for CPU 0 then waited
forever in the mailbox: the boot CPU's idle thread (
task::idle_loop) never looked into it. Found with a temporary scheduler dump after 25 s plusinfo registersof all CPUs through the QEMU monitor. - Fix: one
smp::idle_loop(cpu)for every CPU; running inline on the own CPU happens with interrupts off. - Test:
smp::tests::jobs_for_every_cpu_from_every_cpu(4 threads send jobs to all CPUs; hangs reliably with the old code). - Remember: with SMP every per-CPU duty must exist on every CPU, including the boot CPU.
#7 · 2026-10-25 · With one CPU, every disk command took 10 ms
- Symptom: after switching AHCI to MSI,
KERNEL_SMP=1 make testtimed out;time hellotook 0.38 s instead of 0.1 s. - Cause: the reading thread blocked, the CPU went to its idle thread and
hlt. The completion interrupt made the thread ready, but the CPU returned into the idle thread and only switched at the next timer tick. With more CPUsmake_readysends a wake-up IPI to another idle CPU, which hid the problem; nothing kicks the CPU that handles the interrupt itself. - Fix:
task::preempt_idle()at the end of interrupt handlers that wake threads (AHCI, keyboard, COM1): an idling CPU switches to the woken thread at once. - Test: the integration test with
KERNEL_SMP=1(timing oftime helloand the whole run under 30 s). - Remember: run the suite with one CPU after scheduler or interrupt changes – some paths only exist there.
#8 · 2026-10-25 · MSI test flaky: "only 12 interrupts for 16 commands"
- Symptom:
ahci::tests::commands_complete_by_msi_interruptfailed in about 1 of 10 runs withKERNEL_SMP=2. - Cause: the test's assumption was wrong, not the driver. QEMU often completes a command before the waiter blocks
(
wait_forchecks PxCI first), so the thread goes on without needing the interrupt. The MSI for it is still sent to the boot CPU; when that CPU runs with interrupts off for a moment, the next command's MSI arrives while the first one is still pending in the local APIC's IRR – both set the same bit and become one interrupt. - Fix: the test only requires that completion interrupts arrive at all (waiting up to 100 ms for the first).
- Test: the test itself (repeated runs with 2 CPUs).
- Remember: interrupts with the same vector coalesce while pending – never count interrupts to count events; the handler must look at the device's status registers (ours does).
#9 · 2026-10-25 · run_on test hung once with 2 CPUs
- Symptom:
smp::tests::jobs_for_every_cpu_from_every_cpuhung once inKERNEL_SMP=2 make test(not again in 160 hunted runs). - Cause (by analysis): a priority inversion. The idle thread ran jobs with interrupts enabled, so it could be
preempted while the job held the result lock (
*slot.lock() = ...). An idle thread only runs when nothing else is ready – but the thread waiting for the result spun on that very lock, stayed ready and occupied the CPU forever. The waiter could likewise be preempted holding the lock while the job spun on it. - Fix: jobs run with interrupts disabled; the waiter takes the result lock with interrupts disabled too. A spin lock that an idle thread shares with normal threads must never be held across a preemption point.
- Test:
jobs_for_every_cpu_from_every_cpuwithKERNEL_SMP=2and4(rare – the race needs a timer tick inside a few instructions). - Remember: idle threads have the lowest priority by construction; anything they hold can starve.
#10 · 2026-10-25 · stack_overflow test: #GP with error code 0x102 after -cpu max
- Symptom: after switching QEMU to
-cpu max,tests/stack_overflow.rsdied with a general protection fault (code 0x102) instead of the expected double fault. - Cause: error code 0x102 = "IDT entry 0x20": the timer interrupt. The test loads its own IDT with only exception handlers, but interrupts were still enabled; the recursion used to finish before the next tick, and with the slower emulated CPU model a tick arrived first.
- Fix: test kernels with their own IDT disable interrupts before loading it (
stack_overflow.rs,page_fault.rs). - Test: both tests, with
-cpu max. - Remember: a #GP with bit 1 of the error code set points at an IDT vector (index = code >> 3) – usually an interrupt without a handler.
#11 · 2026-10-26 · A syscall with a huge length freezes the system
- Symptom: found by
syscheck(M41):write(1, 0, 1 << 47)never returned, the whole machine stopped responding. - Cause: before checking a user buffer,
Process::populatewalked every page of[addr, addr + len)to map demand-paged heap/stack pages – 2^35 iterations here, under the process table lock with interrupts off. - Fix: the walk stops at the first page that is neither mapped for user mode nor demand-paged (the access check fails there anyway). A request now costs at most the size of the mapped area it touches.
- Test:
syscheckcalls every pointer-taking syscall with lengths up tou64::MAX(integration testuserspace, E2E). - Remember: every loop over a user-supplied range must be bounded by something the kernel owns, not by the user's length.
#12 · 2026-10-26 · Kernel panic from ring 3: empty buffer with a null pointer
- Symptom:
KERNEL PANIC: unsafe precondition(s) violated: slice::from_raw_parts requires the pointer to be aligned and non-nullincopy_from_user, triggered by the random phase ofsyscheck. - Cause: zero-length ranges are always "accessible" (see pitfalls: empty slices have dangling pointers), but
copy_from_user/copy_to_userstill built a slice / calledcopy_nonoverlappingwith that pointer. With a null pointer that is undefined behaviour, which the debug build checks – any program could panic the kernel. - Fix: both return immediately for empty buffers, without touching the pointer.
- Test:
syscheck:write/readwith length 0 and pointers 0, 1,u64::MAXmust return 0. - Remember: an "accessible" empty range is no licence to dereference its pointer.
#13 · 2026-10-26 · readdir with a bad buffer skipped a directory entry
- Symptom:
syschecksawreaddir(fd, bad pointer)return 0 (end of directory) after a few calls – the failed calls had used up the entries. - Cause:
sys_readdiradvanced the directory position before copying the entry out; the copy then failed with EFAULT. - Fix: the buffer is checked first; the position only moves when the entry can be delivered.
- Test:
syscheck:readdirinto null → EFAULT, then the first realreaddirreturns the same entry as on a fresh handle. - Remember: check, then change state – a syscall that fails should leave nothing behind.
#14 · 2026-10-26 · Kernel panic: user copy raced against brk in another thread
- Symptom:
syscheck racewithKERNEL_SMP=1:KERNEL PANIC ... EXCEPTION: PAGE FAULT at address 0x44b000within a second – a kernel-mode page fault on a user heap address. - Cause:
copy_from_user/copy_to_userchecked the buffer (under the process table lock) and copied it after releasing the lock. A timer interrupt between the two let another thread of the process shrink the heap; the copy then touched an unmapped page in ring 0, which is fatal. - Fix: check and copy happen together under the process table lock (
locked_user_copy), in pieces of at most 64 KiB to keep the time with interrupts off short.brkchanges the page tables under the same lock. - Test:
syscheck race 1000in the integration test (fails within a second on the old code with 1 CPU). - Remember: a check of user memory is only valid while nothing can change the mapping – hold the lock until the copy is done.
#15 · 2026-10-26 · TLB shootdown waited for idle CPUs (seconds, or forever)
- Symptom:
syscheck racewith 4 CPUs: only 4 heap shrinks in 5 s (~1 s perbrk). The new unit test with a spinning thread on every CPU never finished. - Cause:
paging::shoot_downsent the CR3 reload as ansmp::run_onjob to every CPU. Jobs run in a CPU's idle thread, which only gets the CPU when no other thread is ready – a busy CPU answered late or never. - Fix: own IPI vector
smp::TLB_VECTOR(0xF1): the handler reloads CR3 if that CPU runs the address space and counts down a pending counter the sender spins on (with interrupts on, so two shootdowns cannot deadlock). - Test:
smp::tests::tlb_shootdown_is_fast_while_all_cpus_are_busy(20 shootdowns < 50 ms with all CPUs busy; the old code hangs until the 30 s timeout). - Remember: work that must happen now on another CPU belongs in an interrupt handler, not in a job queue.
#16 · 2026-10-26 · One write could make the kernel heap grow by the whole buffer
- Symptom: found while sorting the open items (M42) and confirmed with
syscheck: a 16 MiBwriteinto a pipe without a reader grew the kernel heap by 16 388 KiB before failing with EPIPE. The kernel heap never shrinks, and a failed kernel allocation halts the system – two programs writing their 64 MiB heaps at once could take the machine down. - Cause:
sys_write(andsys_sendto) copied the whole user buffer into a kernelVecbefore doing anything. - Fix:
sys_writecopies and writes in pieces of at most 64 KiB (pieces end on a UTF-8 character boundary, the console prints each piece as text);sendtorefuses datagrams larger thanMAX_UDP_PAYLOADbefore copying (EMSGSIZE). Programs still see one complete write –ulibdoes not expect short writes. - Test:
syscheck: 16 MiB into a pipe without a reader → EPIPE with < 1 MiB heap growth;sendtoof 1 GiB → EMSGSIZE. - Remember: the size of a kernel allocation must never be chosen by a user program.
#17 · 2026-10-26 · Shootdown regression test too strict for CI runners
- Symptom: the first CI run (M47) failed on Ubuntu and Fedora alike:
tlb_shootdown_is_fast_while_all_cpus_are_busy– "20 shootdowns took 72610 us" (Fedora: 74845 us) against a limit of 50 000 us. Locally the test passed. - Cause: the limit was chosen from local runs. GitHub's shared runners emulate 4 CPUs with TCG on fewer real cores, so every IPI round trip takes longer. Not a kernel bug.
- Fix: limit raised to 1 s. The test still tells the two implementations apart: the old
run_onshootdown never finished with all CPUs busy (30 s timeout). - Test: the test itself, green in CI on Ubuntu and Fedora.
- Remember: a timing assertion must separate good from broken behaviour, not fast machine from slow machine –
pick the limit from the broken case, not from the local measurement (see
docs/HACKING.md, "Add a test").
#18 · 2026-10-26 · sleep_ms could end up to one tick early
- Symptom: one local E2E run:
time helloprintedreal 0.095377 sfor a program that sleeps 100 ms (and itself reported "Slept for 100 ms", measured in ticks). - Cause: the deadline was "now + ⌈ms / 10⌉ ticks". The tick that is already running counts fully, although part
of it is over – a sleep starting just before a tick ended almost a whole tick early;
sleep_ms(10)could return after a few microseconds. - Fix: one tick more (
sleep_ms_or_abort): a sleep now lasts at leastmsand at mostms+ 10 ms. - Test:
irq::tests::sleep_never_ends_early– 20 sleeps of 10 ms started at different points inside a tick, measured with the TSC clock; fails on the old code, passes on the new. - Remember: a tick counter tells which tick it is, not how far into it – deadlines must round up.
#19 · 2026-10-26 · A new process could miss its own table entry (SMP race)
- Symptom: CI on Fedora, E2E step
ls /bin | grep test | sort -r:sortkilled by a "page fault at 0x7fffffeefff8 (page not present, write, user mode)" incore::panicking::panic_nounwind_fmt– 8 bytes below the 1 MiB stack area. Not reproducible by running the pipeline 200 times locally. - Cause: two bugs in a chain. (1)
process::spawn_withmade the new thread runnable (task::spawn_user) before inserting the process into the table. Another CPU – woken by an IPI because a thread became ready – could start the program at once; its firstbrkfound no table entry and failed with EBADF, so the program's allocator could never get memory. (2) The allocation failure made Rust panic, andulib's panic handler formatted its message witheprintln!, which allocates – it panicked again, recursively, until the stack was used up. - Fix: (1)
spawn_withholds the process table lock while it creates the thread and inserts the entry – the orderspawn_threadalready used. (2) The panic handler formats into a 256-byte buffer on the stack and stops at a second panic ("panic while panicking"). - Test:
process::tests::first_syscall_of_a_new_process_finds_its_table_entry(240 processes whose first syscall isbrk; failed in 4 of 6 runs on the old code with "first brk returned -9", 0 of 7 on the new, also with 1 and 2 CPUs);fault oomfills the heap to the last byte and must still print "panic: memory allocation of 1048576 bytes failed" (old handler: the same page fault below the stack as in CI). - Remember: "interrupts off" protects against this CPU only – on SMP, anything a new thread may look at must exist before the thread becomes runnable.
#20 · 2026-10-27 · DESIGN.md said there was no block cache
- Symptom: an outside review of the docs found two contradicting statements: "Disk caching and interrupts" says the
root file system runs on a 1024-sector
BlockCache, "File system" said "No block cache: data clusters are read/written directly". - Cause: documentation only. The "File system" text was written at M15; M32 added
BlockCacheand updated its own section but not the older one. The code (fs::RootDisk = BlockCache<SystemDisk>) was right. - Fix: the "File system" section now describes the caches as they are and states the limit of the power-off guarantee (after a command, not during one).
- Test: none possible for prose;
scripts/check-doc-refs.pyonly checks that named symbols exist. - Remember: a milestone that changes a layer must search the docs for every statement about that layer, not only edit its own section.
#21 · 2026-10-27 · The heap could grow into the stack
- Symptom: none observed; found while placing the thread stack slots of M52 below the main stack.
- Cause:
USER_IMAGE_ENDonly kept the ELF segments 64 KiB below the stack area. The heap starts right after the image and may grow byHEAP_MAX(64 MiB) – a program whose image ended nearUSER_IMAGE_ENDcouldbrkits heap into the stack range, and both would demand-page the same addresses. Only the program itself was affected (memory isolation between processes held), but it broke the stack guard. - Fix:
USER_IMAGE_END = THREAD_STACKS_BOTTOM - STACK_GUARD - HEAP_MAX: the largest heap behind the highest allowed image ends below a guard gap. - Test:
process::tests::thread_stack_slots_have_guardsasserts the layout (fails with the old constant). - Remember: a limit on one region (the image) is only safe together with the limits of the regions that grow out of it (the heap).
#22 · 2026-10-27 · The TCP loss test needed almost the whole time limit of its test kernel
- Symptom:
make stress, pass 1 with 4 CPUs:netfaultkilled by the 30 s timeout ofrun-qemu.shwhileevery_fifth_packet_lost_the_data_still_arrivesran. With 1 and 2 CPUs, and in 6 single runs, it passed. - Cause: the test, not the kernel. 3 echoes of 20 KB with every 5th packet lost cost 36–49 retransmission timeouts of at least 200 ms each (go-back-N sends everything after a loss again, and every 5th of that is lost too) – 10–15 s of the 30 s limit. On a busy machine that was not enough. Runs with a 120 s limit never hung (6 of 6 passed in 18–22 s).
- Fix: 8 KB per echo and every 10th packet lost; the loss still hits the SYN, the SYN-ACK and the first ACK once each. The test prints its duration.
- Test: 6 runs with all 4 host cores busy: 2.7–6.1 s for the test, all passed; then the full
make stress. - Remember: a test that waits for timeouts must be sized against the time limit of the machine it runs on, with room to spare – the CI uses 120 s, a developer machine 30 s.
#23 · 2026-10-27 · The DNS timeout E2E step expected an exact duration
- Symptom:
make e2e-uefion the 1.0.0 commit:time host silent.yak.test …printedreal 5.152603 s, the step expectedreal 4.. - Cause: the test (M58). 3 tries of 1.5 s are at least 4.5 s; how much longer depends on the machine.
- Fix: the step now only forbids giving up too early (
real 0.…real 3.); the step's own timeout catches a hang. - Test:
make e2eandmake e2e-uefigreen. - Remember: the same lesson as #22 – assert a lower bound for timeouts, never an exact time.
#24 · 2026-10-29 · The hello sleep check in the userspace test allowed only one tick of delay
- Symptom:
make checkon a busy host:tests/userspace.rsfailed at its first assertion –helloprinted "Slept for 120 ms", the test accepted only 100 or 110 ms. Five runs right after it printed 110 ms and passed. - Cause: the test, not the kernel. A sleep of 100 ms lasts at least 100 ms (bug #18); when the woken thread runs again depends on the timer ticks arriving on time, and under TCG on a loaded host a tick can come late.
- Fix: the test reads the number and checks 100 ≤ ms ≤ 300 – the lower bound stays exact, the upper one only catches a sleep
that is far too long.
irq::tests::sleep_never_ends_earlystill checks bug #18 precisely with the TSC clock. - Test:
tests/userspace.rsgreen in five runs in a row. - Remember: the third time after #22 and #23 – an emulated machine gives lower bounds for time, never upper ones.
#25 · 2026-10-29 · Course chapter 6: no timer interrupt under QEMU 8.2
- Symptom: CI job
courseon PR #9:time::tests::sleep_never_ends_earlyhung until the 120 s limit. Locally (Fedora, QEMU 10.2) all 29 tests passed. Reproduced with the same kernel under Ubuntu 24.04's QEMU 8.2.2 in a container: the normal kernel stops after "Timer: IRQ 0 on vector 32". - Diagnosis: QEMU monitor under 8.2:
pic0: irr=01 imr=fe isr=00 irq_base=20– the PIC holds the tick, moved and unmasked – andLVT0 0x00018700 … masked ExtINT, RFLAGS.IF = 1, the CPU inhlt. The chapter switched the local APIC off throughIA32_APIC_BASEas the reference kernel did in M6 (bug #2), but QEMU 8.2 still sends the PIC's signal through LINT0, and Limine masked LINT0. QEMU 10.2 delivers it; where its code differs I did not find. - Fix: unmasking LINT0 ("virtual wire mode") needs the APIC registers – memory-mapped at
0xFEE0_0000, which Limine does not map (a read through the HHDM page-faults), or x2APIC MSRs, which QEMU 8.2's TCG does not offer. So from chapter 6 on the course starts QEMU with-cpu qemu64,-apic: no local APIC, the PIC goes straight to the CPU. TheIA32_APIC_BASEcode is gone from the chapter; the APIC returns in part IV. - Test:
pic::tests::the_cpu_has_no_local_apic; chapter 6'smake testgreen under QEMU 8.2.2 (container) and 10.2; with-apicremoved the kernel hangs again. The CI jobcourse(Ubuntu 24.04) runs it on every push. - Update (C12): chapter 12 uses the APIC; from there on
run-qemu.shstarts QEMU with-cpu qemu64again. - Remember: behaviour that depends on emulator details needs a run on the oldest supported version – CI runs Ubuntu's QEMU, a developer machine often a much newer one.
#26 · 2026-10-29 · translate was 4 KiB off inside the framebuffer's huge pages
- Symptom: found while writing course chapter 9, no visible effect in the kernel: the chapter's
translate, written after the kernel'stranslate_in, gave0xfd001000instead of0xfd000000for the framebuffer's HHDM address0xffff8000fd000000. The kernel's function computed it the same way. - Cause: Limine maps the framebuffer with 2 MiB pages and sets their PAT bit, which selects a caching type.
In a 2 MiB or 1 GiB page entry that bit is bit 12 (
0xfd0010eb), in a 4 KiB entry it is bit 7.translate_intook bits 12–51 as the address for every level and added the offset, so the PAT bit shifted the result by 4 KiB. Every caller in the kernel translates 4 KiB pages (user memory, the SMP trampoline check), which is why nothing broke. - Fix: for a huge page the address is rounded down to the page size before the offset is added.
- Test:
mem::paging::tests::translate_ignores_the_pat_bit_of_huge_pages(kernel) andpaging::tests::the_framebuffer_translates_exactly(course chapter 9). - Remember: an entry's bits mean different things on different levels – the Intel SDM's table per level, not one mask for all.
#27 · 2026-11-01 · Course chapter 12: the PIT ticked twice as fast through the I/O APIC
- Symptom: found while writing course chapter 12, before it was published. All tests were green and
sleep_ms(1000)reported 1010 ms – butsleep 5000in the shell returned after 2.7 s on the host clock (chapter 11: 5.2 s). Every test measured time in the same ticks that were wrong, so none could notice. - Cause: the chapter routes the PIT's IRQ 0 through the I/O APIC for a tenth of a second, to measure the local
APIC timer against it. The PIT ran in mode 3 (square wave), as since chapter 6, and through the I/O APIC that gave
two interrupts per period, 200 Hz: the calibration measured 312 274 APIC timer counts per tick instead of about
625 000 (QEMU's APIC timer runs at 1 GHz, divided by 16). The PIC of chapters 6–11 gave one per period. The same
under QEMU 8.2.2 and 10.2. In mode 2 (rate generator, one short pulse per period) the count is 624 593 and
sleep 5000takes 5.2 s. The reference kernel is not affected: it measures the APIC timer with PIT channel 2, polled, and never routes IRQ 0. - Fix: the chapter's
pit::inituses mode 2. - Test:
lapic::tests::the_timer_was_measured_against_a_100_hz_clock(course chapter 12): 600 000–650 000 counts per tick; with mode 3 it fails with311689 counts per tick. - Remember: a clock cannot be checked against itself. A test of time needs a second, independent clock – here the APIC timer's known rate under QEMU, or the host's clock.
#28 · 2026-11-01 · Course chapter 13: the boot hung now and then in task::init
- Symptom: found while testing chapter 14: the boot check
fault=overflowfailed 2 times in 20, and chapter 13 (already merged) hung 1 time in 20 at the same place – after theKeyboard:line, beforeThreads:. Its seven test-kernel runs had all been green: the tests start the scheduler too, but the window is small. - Diagnosis: booted in a loop until it hung, then
info registersthrough the QEMU monitor: RIP in the idle thread'shlt(task.rs:208), interrupts on, RSP on the idle thread's stack – andmainin no queue. - Cause:
task::initset up the scheduler in steps with interrupts on: first a scheduler whoseidlefield was 0 – thread 0 ismain– thenspawn("idle"), then the real idle id. A tick between the steps found a ready thread and calledyield_now, which never queues the idle thread – and tookmainfor it.mainwas never queued again, and the CPU halted in the idle thread for good. The reference kernel is not affected: itstask::initruns entirely with interrupts off; the course chapter lost that while being made smaller. - Fix:
initbuilds both threads first (new_thread, the idle thread never queued) and installs the finished scheduler in one step with interrupts off. In chapters 13 and 14. - Test:
task::tests::the_idle_thread_is_thread_1_and_never_queued; 40 boots of chapter 13 without a hang (before: 3 of 40). - Remember: a structure that an interrupt handler reads must never be visible half built – build it aside, then publish it in one step with interrupts off.
#29 · 2026-11-06 · Course chapters 12–15: the timer calibration test failed on a busy host
- Symptom: while chapter 15 ran 6 times with all 4 host cores busy (to imitate a CI runner):
the_timer_was_measured_against_a_100_hz_clockfailed twice with 597 649 and 596 420 counts per tick. - Cause: the test, not the kernel. The local APIC timer is measured against the PIT's interrupts; on a loaded host QEMU delivers them a little late, so the 10 ticks take a little longer and the count per tick comes out about 4 % low. The window 600 000–650 000 around the expected 625 000 left too little room.
- Fix: 550 000–700 000 in chapters 12 to 15. Bug #27 halved the value (about 312 000) and is still caught.
- Test: chapter 15's unit tests 4 times with the host fully loaded, all passed.
- Remember: like #22 and #23: a test that measures time needs room for a slow machine – here on both sides.
#30 · 2026-11-06 · Course chapter 15: join returned while the ended thread was still on its CPU
- Symptom: chapter 15's unit tests, run 8 times, 4 of them with all host cores busy:
ended_threads_give_their_ stack_backfailed twice – once 8 frames (one thread stack) were missing after all threads were joined. - Cause:
exitwoke the joiners as soon as the thread was marked dead – but it was still on its CPU until the switch away from it had finished, soreaphad to leave its stack alone.joinreturned, and the stack was freed only by a laterspawnorjoin. On one CPU that gap was invisible: the joiner could only run after the switch. - Fix: the joiners are woken in
finish_switch, once the dead thread is off its CPU, andjoinwaits for "dead and not on a CPU". The test's threads also wait for a signal, so that none ends before the frames are counted. - Test:
ended_threads_give_their_stack_back, 6 runs, 4 with the host loaded: all passed. - Remember: on SMP, "the thread ended" and "the thread's stack is free" are two moments, not one.
#31 · 2026-11-06 · Course chapters 15–20: a GDT test asked whichever CPU the test thread was on
- Symptom:
make coursefor release 1.1.0: chapter 20'sgdt::tests::gdtr_points_to_our_tablefailed once – the GDTR held a heap address, the test expected the boot CPU's static GDT. CI and all earlier runs had passed. - Cause: the test, not the kernel. Since chapter 15 every CPU runs threads, so the test thread
mainmay have moved to an AP – and each AP loads a GDT of its own (chapter 14).sgdtanswered for the CPU the test ran on. - Fix: the test asks every CPU itself with
smp::run_on: CPU 0 has the static GDT, every CPU the right size, no two CPUs the same table. Changed in chapters 15–20 (chapter 14's threads stay on the BSP). - Test: the fixed test, 3 runs of chapter 20 and one of each of chapters 15–19: all passed.
- Remember: "the CPU I run on" is a moving target once threads migrate – a per-CPU question has to be asked on that CPU (as chapter 15 learned for the double fault stack).
Known pitfalls (not bugs, but worth remembering)
- The Limine host utility (
limine bios-install) needs a C compiler (gcc). It is not required for booting the ISO in QEMU with-cdrom; it is only needed to make the ISO bootable as a hard disk / USB image. sudodoes not work through!in Claude Code because there is no TTY for the password prompt. I run installs in a separate terminal.cargo fmt -- <file>formats the whole crate, not just the file. Format deliberately withmake fmt, and commit pure formatting separately from functional changes.- Limine sets the USER bit on its upper-half page tables (PML4/PDPT/PD entries; the leaf entries are supervisor-only).
Harmless while the leaves are right, but
paging::initclears USER in all upper-half PML4 entries so ring 3 can never reach kernel memory by accident (found by the testkernel_half_is_fully_populated). x86_64-unknown-nonedefaults tocode-model=kernel(addresses in the top 2 GiB). User programs linked at 0x40_0000 need-C code-model=small, otherwise GNU ld fails with "relocation truncated to fit".- LLVM may delete an unused allocation and assume it succeeded.
alloc(huge).is_null()was optimized tofalseinheaptest, so the "allocation must fail" check failed although the kernel refused the memory. Pass the pointer throughcore::hint::black_boxwhen testing allocation failure. - Empty slices from Rust come with dangling pointers (e.g.
0x1for an emptyVec<u8>). The syscall pointer check rejectedspawn(path, [])withEFAULTbecause page 0 is unmapped; zero-length ranges are now always accepted. - The serial console sends
\r\nfor every\n. E2E expectations spanning several lines must contain\r\n. - rustc no longer accepts
+sse/-soft-floatonx86_64-unknown-none("must be disabled to ensure that the ABI of the current target can be implemented correctly", soon a hard error). Hard-float user programs need their own target JSON and-Zbuild-std; build scripts ofcore's dependencies then need a host C toolchain (gcc, glibc headers/crt files). - LLVM's assembler rejects label differences inside memory operands in
global_asm!(Intel syntax):mov eax, [ebx + (a - b)]→ "cannot use more than one symbol in memory operand". Encode such instructions with.byteand put the difference into a.word/.long(see the SMP trampoline). - The page allocator hands out the lowest frames first, so memory below 1 MiB is gone after early boot. Hardware that
needs low memory (the SMP trampoline) must reserve it at
pmm::inittime. spin0.12'sMutexhas noas_mut_ptr. To use the data of a lock you own without a guard (the scheduler lock is released by the next thread after a switch), keep the address of the data from a guard taken at init (task::SCHEDULER_DATA) and callforce_unlockafterwards.- Limine's stack has no guard page – a stack overflow silently corrupts memory instead of faulting (until M9 gives us our own stack).
Project goals
Status: I (FreakySneaky787, the author of YAK) decided the direction on 2026-10-26 (learning platform, see "Direction" and
docs/ROADMAP.md); I released 1.0.0 on 2026-10-27 against the criteria below (the outside reader of "Understanding" was not yet found – I decided not to wait for it; it stays open for 1.0.x). 1.1.0 (2026-11-06) adds the course chapters 1–20; the kernel itself is the one of 1.0.0. Changes to this file need my agreement.
Name
YAK – Yet Another Kernel. (My decision of 2026-10-26, replacing the earlier working name KernelTry; it matches
the repository name yak-kernel.)
Purpose
YAK is a self-contained operating system for studying how a modern operating system kernel is built and works, hands-on, and for developing it further. It runs in QEMU (BIOS and UEFI).
Audience
Primarily self-learners and hobby kernel developers (my decision of 2026-10-26); computer science students and anyone interested in operating system architecture are welcome too.
Direction (1–2 years)
YAK becomes a learning platform: an English course on its own website in which learners rebuild the
kernel chapter by chapter, each chapter a runnable, tested state on its own branch. The kernel in main stays the
reference implementation. New kernel features are added only when they carry a chapter. Details: docs/ROADMAP.md.
What makes it different
- Understandable documentation – every subsystem is explained (
docs/LEARN.md), every design decision has a reason (docs/DESIGN.md), every bug has a story (docs/BUGS.md). - Traceable kernel paths – walkthroughs that follow one action (a key press, a syscall, a page fault, a pipe) through the code, with file references.
- Reproducible tests – one command (
make check) runs unit tests, test kernels and end-to-end shell sessions under BIOS and UEFI; the suite also runs with 1–4 CPUs and without modern CPU features. - Room to experiment – guided experiments ("change X, expect Y") and short guides for extending the system (a new syscall, a new program, a new test).
Honest scope: YAK implements the concepts of modern kernels (x86-64 long mode, SMP, APIC, UEFI, SMEP/SMAP,
XSAVE, TCP) in simplified form. It is not POSIX-compatible and has no fork/exec, mmap or virtual file system.
First release (1.0)
A reliable, text-based x86-64 operating system with
- a shell (
/bin/sh: pipes, redirection, scripts, control flow, jobs), - a persistent file system (FAT32 on a SATA disk),
- isolated user programs (ring 3, one address space per process),
- multitasking (preemptive SMP scheduler, threads, signals),
- networking (e1000, IPv4, UDP, TCP, DHCP, DNS, HTTP client and server).
All of these exist as of stage 7 (M38). Release 1.0 is therefore about reliability, documentation and the
experience of a first-time reader, not about new features. Stage 8 in docs/PROGRESS.md turns this into milestones.
Release criteria (definition of done)
| Area | Criterion |
|---|---|
| Entry point | README.md explains what YAK is, shows a screenshot, lists host packages and gets a new reader from clone to a running shell |
| Legal | LICENSE (GNU GPL v3 or later, chosen by me on 2026-10-26, replacing ECPL v1.2) applies to the whole repository except third-party assets |
| Reproducibility | the Rust toolchain is pinned; a dependency check names missing host tools; make check passes on a fresh Fedora and Ubuntu host (checked by CI on every push, M47) |
| Reliability | make check passes N times in a row (N agreed in stage 8) with 1, 2 and 4 CPUs and with KERNEL_CPU=qemu64; a soak test runs for a fixed time without failure; every syscall rejects invalid arguments without crashing the kernel |
| Known limits | every open item is either fixed or listed as a documented limitation |
| Understanding | at least three end-to-end walkthroughs with file references |
| Experimenting | at least three guided experiments with an expected result, and guides for adding a syscall, a program and a test |
Not goals of the first version
- replacing Linux or being POSIX-compatible,
- a full desktop / graphical user interface,
- supporting as much real hardware as possible (QEMU is the reference machine),
- performance competitive with production kernels,
- becoming the base of a desktop operating system – YAK is a kernel to learn from; features that do not carry a chapter of the course are not added.
Working rules that follow from the goals
- New features must come with a test and a
LEARN.mdsection – an unexplained feature does not serve the purpose. - Prefer clear code over clever code; when a simplification is made, say so in
DESIGN.md. - Third-party crates stay limited to
limineandspin(from scratch is part of the point).
Roadmap – from kernel to learning platform
Decided by me (FreakySneaky787, the author of YAK) on 2026-10-26. Phases are worked off as stages in
docs/PROGRESS.md.
Context
YAK 0.8.0 was published as a pre-release: a working x86-64 kernel (M1–M46) with tests, walkthroughs and experiments. I decided the direction for the next 1–2 years:
- What: a learning platform (not a feature-race hobby OS, not a lab).
- For whom: self-learners and hobby kernel developers.
- How: learners rebuild the kernel chapter by chapter (like blog_os), each chapter a runnable, tested state.
- Language: English. Where: an own website (GitHub Pages), built by CI.
- Roles: I steer, Claude builds.
The existing kernel stays the reference implementation; the course is a second, cleanly ordered path to (almost) the same result.
Target picture
main branch
├── kernel/, user/ … reference kernel (as today)
├── book/ mdBook source of the course + existing docs (walkthroughs, experiments, …)
└── .github/workflows/ CI: make check, book build + deploy, chapter checks
course/NN-<slug> branches one per chapter, each = previous chapter + the chapter's code, own `make check`
website https://<user>.github.io/<repo>/ – course, reference docs, links to chapter branches
Each chapter page = goal · background (from docs/LEARN.md) · step-by-step code with explanation · "run it" ·
tests that prove it · experiments · "what can go wrong" (from docs/BUGS.md) · link to the chapter branch and the
diff to the previous one.
Roadmap
Phase A – finish 1.0 of the reference kernel (short) – done, 1.0.0 on 2026-10-27
- CI (
.github/workflows/check.yml):make checkon Ubuntu and in a Fedora container under QEMU TCG – this also closes the open release criterion "fresh Fedora host". Reusemake depsfor package names. - I confirm
docs/GOALS.md(rewritten for the learning-platform direction, see Phase B). - First external reader tries README → walkthrough 01 → one experiment (I organise this); fix what they report.
- Release 1.0.0 (M47): version, CHANGELOG,
make stress, I create the tag + GitHub release (tags cannot be pushed from the sandbox).
Phase B – course infrastructure (no chapter content yet)
- Website: mdBook (host tool, installed via
cargo installin CI – not a kernel crate) inbook/; GitHub Pages deploy workflow. Existing docs (walkthroughs, EXPERIMENTS, HACKING, LEARN, BUGS) move/link into the book;scripts/check-doc-refs.pykeeps checking them. - Chapter format: template page + rules (one concept per chapter, every code block appears in the chapter
branch, every claim backed by a test or a recorded run – same honesty rule as
docs/EXPERIMENTS.md). - Chapter branches: naming
course/NN-slug; a script that checks a chapter branch builds and passes its tests and that the book's code excerpts match the branch (extension ofcheck-doc-refs.py); CI runs it for all chapters. - Update
docs/GOALS.md(layout, workflow for chapters).
Phase C – pilot: Part I (chapters 1–4), then feedback
Write chapters 1–4 fresh as a clean linear history (not cut out of today's mixed commits): 1 Boot with Limine + serial output · 2 Testing without an OS · 3 Text on the screen · 4 GDT and TSS. → I and at least one outside reader go through them; adjust format before writing more.
Phase D – the remaining course (parts, following the M1–M38 order, which already teaches evolution) – chapters 5–20 written, released as 1.1.0
| Part | Chapters (from milestones) |
|---|---|
| I Bare metal | boot+serial, tests, framebuffer console, GDT/TSS, interrupts/exceptions, PIC+timer, keyboard (M1–M7) |
| II Memory | frame allocator, paging + guard pages, heap (M8–M10) |
| III A first shell | kernel shell (M11) |
| IV Concurrency | APIC/ACPI, threads + scheduler, SMP start, SMP scheduler (M12, M13, M25, M26) |
| V Storage | PCI + AHCI, FAT32, caching + MSI (M14, M15, M32) |
| VI User space | ring 3 + syscalls + ELF, files, user heap, FPU state, processes, shell as program, pipes, signals, threads/futexes (M16–M22, M24, M34, M36) |
| VII Networking | e1000 + IPv4/UDP, TCP, DHCP/DNS/HTTP (M27–M30, M38) |
| VIII Hardening | SMEP/SMAP + XSAVE, memory reclaim/demand paging, testing how a kernel fails (M33, M37, M41) |
Roughly 30 chapters; one chapter ≈ one milestone of work. Order of writing = order of reading. I moved the FPU state (M24) from part IV to part VI on 2026-11-01: the course kernel is built without SSE, so the registers only need saving once user programs use floating point.
The final sprint (my decision, 2026-11-06): the course goes to the end of part VIII, chapter by chapter as before, then phase E (exercises, diagrams + glossary) and release 1.1.0. The plan for the chapters after 14: 15 one scheduler for all CPUs · 16 PCI + AHCI · 17 FAT32 read · 18 FAT32 write · 19 block cache + disk interrupts · 20 ring 3 and the first system call · 21 address spaces + ELF · 22 files for programs · 23 user heap + demand paging · 24 FPU/SSE state · 25 processes · 26 the shell as a program · 27 pipes · 28 signals · 29 threads + futexes · 30 e1000, Ethernet, ARP, IPv4, ping · 31 UDP + sockets · 32 TCP · 33 DHCP, DNS, HTTP · 34 SMEP/SMAP + XSAVE · 35 memory reclaim + guard pages for threads · 36 testing how a kernel fails. A chapter may be split or merged when it grows too large; this list changes with it.
Changed the same day (my decision, 2026-11-06): for now the chapters are written only up to chapter 20 – part V complete with chapter 19, and chapter 20 (ring 3 and the first system call) as the start of part VI. Chapters 21–36 stay planned as listed above, but nothing is written for them until I decide again; phase E and release 1.1.0 wait for that decision too. Release 1.1.0 (2026-11-06) is the course up to chapter 20.
Phase E – polish and growth
- Exercises per chapter with tests learners can run (
make checkon their branch); solutions = next chapter branch. - Diagrams (memory layout, interrupt path, scheduler states), glossary, search (mdBook built-in).
- Kernel features only when they carry a chapter (e.g. VFS +
/proc,fork/exec, mmap) – feature freeze otherwise. - Community basics once the pilot works: CONTRIBUTING.md, issue templates for "I got stuck in chapter N".
Rules that follow from the direction
- The reference kernel and the course must not drift silently: a bug fix in
maingets a note in the affected chapter ("what can go wrong") and, if the chapter code has the bug, a fix in that chapter branch and all later ones. - Every chapter branch stays green in CI with the pinned toolchain; toolchain updates are done for all branches at once.
- Learners must be able to start any chapter from its branch without reading the reference kernel.
Risks (honest)
- Effort: ~30 chapters is the largest piece of work so far; the pilot (Phase C) exists to find out before committing to all of it.
- Maintenance: later changes ripple through many branches – keep chapter branches frozen once published, fix only real bugs.
- AI-written teaching text can sound right and be wrong: every claim needs a test or a recorded run, and outside readers are irreplaceable – Claude cannot test "is this understandable?".
- Nightly Rust breaks over time: the pinned toolchain must keep working; CI shows when it stops.
Decisions I still have to make (later, not now)
- Repository rename (
yak-kernel→ YAK) – before the website URL is published. - Website address (GitHub Pages default vs. own domain).
How progress is checked
- Phase A: CI green on Ubuntu and Fedora; 1.0.0 released.
- Phase B: website deployed by CI; a sample chapter branch passes the chapter check.
- Phase C: four pilot chapters online, each branch green, feedback from at least one outside reader recorded in
docs/PROGRESS.md. - Phases D/E: the same checks per chapter; the course is complete when the last chapter branch reaches the feature set of 1.0.
Progress
Legend: ✅ done · 🔨 in progress · ⬜ open
Stage 1: shell inside the kernel
| # | Milestone | Status | Tests |
|---|---|---|---|
| 0 | Setup: toolchain, Limine, git, GitHub | ✅ | – |
| 1 | Limine boot, serial output, framebuffer test pattern, panic handler | ✅ | manual: BIOS + UEFI |
| 2 | Test framework + make test | ✅ | 7 tests: lib, boot, should_panic + manual failing-test check |
| 3 | Framebuffer text console (bitmap font), println! | ✅ | 9 unit tests (font, console) + screenshot |
| 4 | GDT + TSS (double fault stack) | ✅ | 3 tests: CS/TR/GDTR, IST stack |
| 5 | IDT + exception handlers | ✅ | 3 unit tests + integration tests page_fault, stack_overflow |
| 6 | PIC remap + PIT timer | ✅ | 4 tests: ticks, sleep_ms, PIC mask, APIC off |
| 7 | PS/2 keyboard | ✅ | 13 unit tests + E2E via sendkey (QWERTZ, umlauts, AltGr, Caps) |
| 8 | Physical frame allocator from the Limine memory map | ✅ | 9 tests: fake memory maps, real alloc/free, zeroing |
| 9 | Paging: map/unmap, kernel stack with guard page | ✅ | 8 unit tests + real recursion overflow test |
| 10 | Kernel heap → alloc | ✅ | 9 tests: allocator core on a fixed arena + Box/Vec/String/BTreeMap, growth, reuse |
| 11 | Shell | ✅ | 37 unit tests (console, input, parser, line editor, commands) + 19-step E2E over serial |
Stage 2: multitasking, files, user space (decided 2026-10-24)
| # | Milestone | Status | Tests |
|---|---|---|---|
| 12 | APIC: ACPI/MADT, local APIC + timer, I/O APIC, 8259 masked | ✅ | 10 tests + E2E on BIOS and UEFI, timer vs. wall clock checked |
| 13 | Multitasking: kernel threads, context switch, scheduler | ✅ | 7 scheduler tests + shell tests + E2E (ps, demo), 3× stable |
| 14 | Storage: PCI enumeration, AHCI SATA driver, block device layer | ✅ | 11 tests + E2E (lspci, disk, hexdump) |
| 15 | FAT32 file system (read/write, long names), persistent across reboots | ✅ | 30 tests + fsck.fat/mtools check of all test disks + 45-step E2E incl. reboot (BIOS + UEFI) |
| 16 | User space: ring 3, syscalls, ELF loader | ✅ | 26 new unit tests (hand-assembled programs) + integration test userspace (real programs from disk) + 7 E2E steps |
Stage 3: a real user space (decided 2026-10-24)
| # | Milestone | Status | Tests |
|---|---|---|---|
| 17 | Files for programs: fd table, open/close/readdir/stat/getcwd/unlink/mkdir, cat/ls/cp as programs | ✅ | read_at unit test, fstest (25 syscall checks incl. errors), integration test, mtools check of a cp copy, 6 E2E steps |
| 18 | User heap: brk-style syscall + allocator in ulib (alloc in programs) | ✅ | 4 unit tests (grow/shrink, limits, release, rollback), heaptest (11 checks), sort in integration test, 6 E2E steps |
| 19 | Processes from processes: spawn/wait/kill syscalls, Ctrl+C | ✅ | Ctrl+C unit tests (foreground, ignore, raw scancode tracker), spawntest (17 checks incl. orphans), 6 E2E steps (Ctrl+C over serial), PS/2 Ctrl+C checked via sendkey |
| 20 | Shell as a user program (/bin/sh started as init, kernel shell as fallback) | ✅ | builtins_for_user_space, scripted /bin/sh session in the integration test (injected serial input), whole E2E suite (72 steps) now against /bin/sh + exit fallback |
Stage 4: a usable system (decided 2026-10-24)
| # | Milestone | Status | Tests |
|---|---|---|---|
| 21 | Pipes and redirection (a | b, >, >>, <) | ✅ | 4 pipe unit tests (EOF, EPIPE, full pipe with a writer thread, abort), pipetest (17 checks incl. 200 KB from a child), scripted sh pipeline session, 8 E2E steps |
| 22 | System information as syscalls (replace kshell), ps/mem/... as programs, rename + seek | ✅ | write_at unit test, fstest +17 checks (seek, gaps, APPEND, rename, ESPIPE), integration test for all 10 programs, 5 E2E steps |
| 23 | Full-screen text editor as a user program | ✅ | edit --selftest (19 buffer checks), console SGR 7 test, 3 scripted editor sessions in the integration test, 5 E2E steps, screenshot |
Stage 5: hardware (decided 2026-10-24)
| # | Milestone | Status | Tests |
|---|---|---|---|
| 24 | FPU/SSE state per thread; user programs built with SSE2 hardware floating point | ✅ | 3 FPU unit tests (CR0/CR4, initial state, save/restore), fputest (4 preempted workers checking XMM0–15 + MXCSR, pi with f64) in integration + E2E; verified that it fails without the switch |
| 25 | SMP part 1: start the other cores ourselves (trampoline, INIT/SIPI), per-CPU GDT/TSS/LAPIC, jobs on APs | ✅ | 4 SMP unit tests (all MADT CPUs online, jobs run on the right CPU with its own TSS, FPU + heap on APs, trampoline page), E2E cpu shows 4 CPUs, BIOS + UEFI, 3 stable runs |
| 26 | SMP part 2: scheduler on all cores (per-CPU current/idle thread, lock held across switches, no lost wake-ups, swapgs in the syscall stub) | ✅ | new test: spinning threads seen on ≥ 2 CPUs; whole suite green with KERNEL_SMP=1, 2 and 4; demo 4: 760 ms on 1 core → 200 ms on 4 |
| 27 | Network: e1000 driver, Ethernet/ARP/IPv4/ICMP/UDP, ping, netinfo, udpecho | ✅ | 4 packet unit tests (checksum, IPv4/ARP/ICMP/UDP round trips), 4 network tests (config, ARP + ping to the gateway, UDP ports, receive path), integration test (ping/netinfo/unreachable), E2E: ping + UDP echo through a host server |
Stage 6: a complete small system (decided 2026-10-24: "all of it")
| # | Milestone | Status | Tests |
|---|---|---|---|
| 28 | Microsecond clock from the TSC, time program, ping in µs | ✅ | 2 TSC unit tests (calibration, agreement with the tick clock), time hello in integration test + E2E |
| 29 | TCP: connect/listen/accept, retransmission, flow control; client and server programs | ✅ | TCP packet test, refused + 100 KB loopback echo in the kernel, nc/echod between processes, E2E: host echo, 100 KB from the host, host → guest 50 KB via hostfwd |
| 30 | DHCP and a DNS client; HTTP client (wget) and server (httpd) | ✅ | DHCP packet test, card_is_configured checks the DHCP lease, host --selftest (7 DNS checks), httpd + wget over loopback (200/404), E2E: fake DNS on the host, wget from a host HTTP server, the host fetches from httpd via hostfwd |
| 31 | Shell: scripts, environment variables, 2>, background jobs (&, jobs, wait) | ✅ | scripted sh session (expansion, inheritance, $?, 2>, job + wait, #! script) and a set -e script in the integration test, 8 E2E steps |
| 32 | Storage speed: sector cache for FAT32, AHCI completion interrupts (MSI) | ✅ | BlockCache unit test (hits, runs, write-through, eviction), lookup-cache invalidation test, MSI test (≥ 1 interrupt per command), benchmark line in the integration test; suite green with 1 and 4 CPUs |
| 33 | Memory: reclaim bootloader memory, demand paging for user heaps | ✅ | tests/reclaim.rs (≥ 1 MiB gained, former bootloader frames are handed out and survive being overwritten, threads + a program afterwards), demand-paging unit test (32 MiB heap, 3 touched pages, < 100 frames), existing brk/heaptest checks; suite green with 1 and 4 CPUs |
Stage 7: a more Unix-like system (decided 2026-10-25: "all of it")
| # | Milestone | Status | Tests |
|---|---|---|---|
| 34 | Signals: handlers in user space, kill -SIG, Ctrl+C as SIGINT, interrupted blocking calls | ✅ | 2 signal unit tests (dispositions, pending order, blocking during a handler, reasons ↔ numbers), sigtest (23 checks incl. all GPRs + XMM0–15 kept when a handler interrupts a loop without syscalls, EINTR from sleep, no nesting, SIG_IGN inherited), sh kill session, E2E: Ctrl+C caught by a handler, kill -USR1 %1 |
| 35 | Shell programming: if/while/until/for, functions, &&/||, ;, test, $((...)), read, wildcards, multi-line input, Ctrl+C stops loops | ✅ | /m35.sh in the integration test (39 output lines compared exactly: all constructs, break/continue n, functions + recursion, read from pipes and files, globbing, set -e), interactive session (continuation prompt, syntax error, exit in a function), stack growth unit test, 6 E2E steps incl. Ctrl+C ending a loop |
| 36 | Threads in user processes (spawn/join, futex-style wait/wake) and a sleeping mutex in the kernel | ✅ | 2 sync::Mutex unit tests (exclusion, a waiter blocks on Wait::Lock), threadtest (17 checks: shared counter, join codes, futex mutex + heap from 4 threads, futex EAGAIN/timeout/wake, ESRCH, exit / fault / main return / SIGTERM with running threads), no threads left over in the integration test, E2E; suite green with 1–4 CPUs |
| 37 | CPU protection and AVX: SMEP/SMAP, XSAVE with AVX state per thread | ✅ | tests/smap.rs (user_access works, kernel read and kernel jump into a user page fault), CR4/XCR0 unit tests, YMM save/restore unit test, fputest with YMM0–15 in 4 preempted workers, sigtest YMM kept across a handler, E2E cpu shows SMEP/SMAP/AVX on; suite also green with KERNEL_CPU=qemu64 and 1 CPU |
| 38 | Network polish: e1000 interrupts, TCP window scaling, DHCP lease renewal | ✅ | interrupt test (GSI found, median ping < 3 ms – about 0.5 ms now), 1 MB loopback transfer with a scaled window > 64 KiB, WS option round trip, lease phase/retry unit test, renew + rebind against QEMU's DHCP server, renewal message test; suite green with 1, 2, 4 CPUs and qemu64 |
Stage 8: release 1.0 – reliable and understandable (proposed 2026-10-26, see docs/GOALS.md)
No new kernel features: this stage makes the existing system meet the release criteria in docs/GOALS.md.
| # | Milestone | Status | Tests |
|---|---|---|---|
| 39 | Front door: README.md with screenshot and host packages, docs/GOALS.md, OVMF path found on Fedora and Debian/Ubuntu | ✅ | make check green on Ubuntu 24.04 with the detected OVMF path |
| 40 | Reproducible setup: toolchain pinned (rust-toolchain.toml, nightly-2026-10-26), make deps checks host tools and prints the dnf/apt command, make check runs it first; LICENSE (ECPL v1.2) | ✅ | check-deps.sh --selftest (hidden tool reported, exit 1) in make check; manual run with a reduced PATH; make check green with the pinned toolchain on Ubuntu 24.04 |
| 40b | Optional CI (GitHub Actions running make check under TCG) – only if I want it | ⬜ | a green run on a push |
| 41 | Reliability gate: /bin/syscheck (bad pointers/lengths/fds/numbers for every syscall, 20 000 seeded random calls, race mode), make soak (rootfs/soak.sh via scripts/soak.py), make stress (suite N× with 1/2/4 CPUs, qemu64, UEFI, then soak); TLB shootdown by IPI | ✅ | syscheck + syscheck race in integration test, syscheck E2E step, shootdown unit test (old code: hangs), soak negative check (an injected failure is reported); bugs #11–#15 found and fixed |
| 42 | Known limits: "Open items" sorted into documented limitations (no open release blocker); found and fixed on the way: #16 (one write grew the kernel heap by its whole buffer) | ✅ | syscheck: 16 MiB into a pipe without reader → EPIPE with < 1 MiB heap growth (old kernel: +16 388 KiB), oversized sendto → EMSGSIZE |
| 43 | Walkthroughs (docs/walkthrough/): boot to /bin/sh, a key press, cat | wc, a page fault – with links to the functions | ✅ | scripts/check-doc-refs.py (make docs-check, part of make check, with self-test): every [symbol](file) link must name a symbol in an existing file; "things to try" checked in the running system |
| 44 | Experiments (docs/EXPERIMENTS.md): more cores, no FPU save, the bug #14 fix undone, a 16-byte pipe – no build switches, each a small hand edit | ✅ | each experiment run once, results recorded (590 → 250 ms; 4 workers corrupted; panic 2/2; 1.40 → 5.41 s) |
| 45 | Extending guides (docs/HACKING.md): syscall, user program, test, shell built-in | ✅ | the syscall + program guide followed once: syscall 52 uname + /bin/uname (integration test, E2E step, syscheck bad pointers, SYSCALL_COUNT) |
| 46 | Pre-release 0.8.0: GPL-3.0-or-later (LICENSE = FSF text, SHA-256 3972dc97…), version in both manifests and the boot banner, CHANGELOG.md, new screenshot | ✅ | make check green; uname shows YAK 0.8.0 x86_64 |
Decided 2026-10-26: name KernelTry, renamed the same evening to YAK – Yet Another Kernel (my decision); license first ECPL v1.2, then (same day) GNU GPL v3 or later (copyright
FreakySneaky787 and contributors); 1.0 is preceded by the pre-release 0.8.0 (my decision, first prepared as 1.0.0-rc.1).
Still open: N for make stress (proposal: 5), whether CI is wanted (M40b), whether experiments may add build switches to the kernel (M44).
Stage 9: CI and release 1.0 (roadmap phase A, agreed 2026-10-26)
| # | Milestone | Status | Tests |
|---|---|---|---|
| 47 | CI: .github/workflows/check.yml runs make check on ubuntu-24.04 and in a fedora:latest container (QEMU TCG, pinned toolchain, 120 s per test kernel, build/ uploaded on failure); CI badge in the README | ✅ | first run red on both (bug #17: shootdown test limit too strict for CI runners), then green on both: all kernel tests, all test disks fsck-clean, 127/127 E2E steps BIOS + UEFI |
| 48 | Release 1.0.0: version in both manifests, CHANGELOG.md section 1.0.0, release checklist docs/RELEASING.md followed; I decided not to wait for the outside reader (stays open) | ✅ | make check, make course, make book, make release (yak-1.0.0.* booted BIOS + UEFI), make stress; uname shows YAK 1.0.0 x86_64 |
Stage 10: course infrastructure (roadmap phase B)
| # | Milestone | Status | Tests |
|---|---|---|---|
| 49 | Website: mdBook over docs/ (book.toml, docs/SUMMARY.md, home page docs/index.md), make book via scripts/build-book.py (links to files outside docs/ point at GitHub; build fails on broken links), CI builds it, .github/workflows/pages.yml deploys main to GitHub Pages | ✅ | build-book.py --selftest; 17 pages, 0 broken links; rendered pages checked in a headless browser; CI step "Website builds without broken links" |
| 50 | Chapter infrastructure: chapters are folders course/NN-slug/ in main (my decision of 2026-10-26, instead of branches), pages docs/course/, scripts/check-course.py (folder/page pairs, numbering, toolchain copy, every file= code block must match the folder; --build runs each chapter's make test), make course, CI job course, authoring rules in docs/HACKING.md | ✅ | check-course.py --selftest; static check in make docs-check; make course green |
| C1 | Pilot chapter 1 – Booting with Limine (serial output) | ✅ | make test: serial output matches expected.txt; fails when the greeting is removed |
| C2 | Pilot chapter 2 – Testing without an operating system (custom test framework, isa-debug-exit, cargo runner) | ✅ | 3 in-kernel tests; a broken assertion makes make test fail with QEMU status 35 |
| C3 | Pilot chapter 3 – Text on the screen (PSF2 font, framebuffer console, println!) | ✅ | 12 in-kernel tests incl. drawing into an in-memory screen with stride ≠ width; screenshot on the page |
| C4 | Pilot chapter 4 – GDT and TSS (own GDT, TSS with an IST stack for double faults, far return to reload CS) | ✅ | 4 new in-kernel tests (segments, GDTR, TSS descriptor bits, IST1); without gdt::init() the GDTR test fails |
Then: phase C (pilot chapters 1–4 + feedback), phases D/E – see docs/ROADMAP.md.
Stage 11: follow-up of an outside review (agreed 2026-10-27)
An outside review of the docs listed risks and one contradiction; I chose what to do before 1.0: fix the docs, verify UDP checksums, guard pages for thread stacks, tests with a failing disk. Everything else it named stays a documented limitation.
| # | Milestone | Status | Tests |
|---|---|---|---|
| 51 | Docs: "File system" in docs/DESIGN.md contradicted the block cache (bug #20), the power-off guarantee is stated precisely, GOALS says YAK is not the base of a desktop OS; UDP checksums are verified on receipt (0 = none, accepted) | ✅ | packet::tests::udp_checksums_are_verified_on_receipt (wrong IP address, flipped bit, zero checksum, Ethernet padding); E2E UDP echo, DHCP and DNS still work |
| 52 | Guard pages for thread stacks: 64 kernel stack slots [64 KiB guard][256 KiB stack] below the main stack, thread_spawn with stack 0, slots freed after the thread ended; USER_IMAGE_END lowered so the heap cannot reach the stacks (bug #21) | ✅ | thread_stack_slots_have_guards (layout, guards, bug #21); fault thread-stack killed with "stack overflow in a thread" in the page below slot 0; threadtest: 200 KiB on a thread stack, 100 threads in a row, 70 unjoined threads then one more; make test with 1, 2 and 4 CPUs |
| 53 | Disk fault tests: FaultyDisk fails I/O number n (transient, or power loss with a torn write); a volume checker (lost clusters, cross-links, broken chains, chain vs. size, FAT copies); results written down in docs/DESIGN.md "File system" | ✅ | fault_tests::every_failing_io_is_reported_and_leaves_a_mountable_volume (7 operations × every I/O × 2 failure kinds: error reported, volume mounts, untouched files intact, target old or new, only fsck-repairable damage), the_volume_stays_usable_after_a_failed_operation, the_checker_sees_damage |
Stage 12: what 1.0 still needs (decided 2026-10-27)
An outside recommendation for 1.0, checked against the repository: most of it exists. I decided to add the gaps it names before 1.0 – the supported environment written down, the missing shell constructs, long input lines, network fault tests and a downloadable release. 1.0.0 itself still waits for the outside reader (M48).
| # | Milestone | Status | Tests |
|---|---|---|---|
| 54 | Supported environment: README section (QEMU q35/TCG, BIOS + UEFI, 1–4 cores, max/qemu64, devices, hosts), measured RAM limits, KERNEL_MEM in run-qemu.sh | ✅ | make e2e 127/127 at 24, 32, 48, 64, 96, 128 MiB, fails at 16 MiB; make e2e-uefi 127/127 at 160 MiB, fails at 64/96/128 MiB (bootloader out of memory under OVMF – the CPU never leaves firmware code, -d int log) |
| 55 | Shell: $(...) (runs in the shell with subshell semantics, a thread drains the pipe) and "$@"/"$*"/$@; an assignment that does not fit the environment is an error instead of silently lost | ✅ | /m55.sh in the userspace integration test (fields, nesting, quotes inside, multi-line output, restored state, exit + $?, "$@" with spaces and without arguments, 1000 lines ≈ 81 KB through one substitution, too long a value); E2E step at the prompt |
| 56 | Shell: case … in … ;; esac (alternatives, wildcards, quoted patterns literal) and local (dynamic scope, restored on return) | ✅ | /m56.sh in the userspace integration test (8 subjects incl. empty, (pattern) form, no match → status 0, nested functions, local without value, outside a function → error); E2E step case $(uname) in … |
| 57 | Line editor: lines up to 4096 characters over several rows (row/column per position, ESC[nA/B/C across rows, pending-wrap safe), console understands ESC[nA/B/C/D | ✅ | 4 new editor tests on two simulated terminals (wrap, edit across rows, shorter line clears rows, Enter below a long line) – fail without the pending-wrap step; console::tests::ansi_cursor_moves; E2E: a 185-character line edited at its start; screenshot checked |
| 58 | Network fault tests: loss injection on the loopback path (net::set_loopback_loss), TCP retry limit settable, retransmission counter; misbehaving fake name server in the E2E test | ✅ | kernel/tests/netfault.rs: 3 echoes of 8 KB with every 10th packet lost (5–14 retransmission timeouts, 2.7–6.1 s under full CPU load, data intact; first version with 20 KB / every 5th packet: bug #22), connect into silence → TimedOut after 1.5 s, silent peer → TimedOut after 3.0 s with 3 retries; E2E: NXDOMAIN, SERVFAIL, CNAME only, stray + truncated replies, silence (4.5 s, "timed out"); host --selftest +4 malformed-answer checks. No bug found |
| 59 | Release files: make release (scripts/release.sh) builds yak-<version>.iso (scripts/mkiso.sh, shared with run-qemu.sh), the disk image with /bin (gzip), run-yak.sh and SHA256SUMS and boots them once (scripts/check-release.py); .github/workflows/release.yml attaches them to a published GitHub release; README "Try it without building"; checklist docs/RELEASING.md | ✅ | make release: BIOS and UEFI boot of the files with run-yak.sh (shell, uname = version, /bin ≥ 30 programs, $(...), poweroff); negative check: a disk without /bin fails; make check green after moving the ISO build into mkiso.sh |
Stage 13: the course after 1.0 (roadmap phases C and D, decided 2026-10-29)
I decided to prepare the pilot for its first outside reader – so that a report can arrive in a usable form – and to continue with chapter 5 meanwhile instead of waiting.
| # | Milestone | Status | Tests |
|---|---|---|---|
| 60 | First-reader pass over chapters 1–4: every folder built on its own outside the repository (own Limine clone); the pages compared line by line with the folders – chapters 3 and 4 never showed how the new code is wired into kmain, chapter 3 counted one test twice, chapter 1 claimed a reset loop that -no-reboot prevents; QEMU's "terminating on signal 15" moved into build/qemu.log; a "What changed" diff line per page; issue forms "I got stuck in a course chapter" / "Feedback on the course"; CONTRIBUTING.md | ✅ | make test in copies of all four folders without LIMINE_DIR; check-course.py also checks the course table, the issue form's chapter list and the diff line (--selftest with all three failures) |
| C5 | Chapter 5 – Interrupts and exceptions: own IDT (idt.rs, 16-byte gates, lidt), x86-interrupt handlers for vectors 0, 3, 6, 8, 13, 14 (interrupts.rs), double fault on IST1, faults on purpose via the kernel command line (fault=page, fault=stack; run-qemu.sh gets KERNEL_CMDLINE/EXPECTED and notices when QEMU ends by itself) | ✅ | 22 in-kernel tests (6 new: gate bits, IDTR, breakpoints return, IST1 gate, exactly six gates present, page fault error text); 3 boot checks – normal, page fault at 0xdeadbeef, double fault on its own stack; without .set_ist(…) the double fault check fails in 1 s (triple fault), without interrupts::init() the IDTR test fails |
| C6 | Chapter 6 – Hardware interrupts and the timer: port.rs shared by serial/PIC/PIT, 8259 PIC moved to vectors 32–47 with EOI and spurious IRQ 7/15 handling, a CPU without local APIC in run-qemu.sh (-cpu qemu64,-apic: Limine masks LINT0, and switching the APIC off is not enough under QEMU 8.2 – bug #25), PIT at 100 Hz, time.rs (ticks, uptime_ms, sleep_ms in hlt, deadline rounded up + 1 as after bug #18) | ✅ | 29 in-kernel tests (7 new: no APIC (CPUID), masks, vectors, divisor, ticks in hlt, deadline rounding, sleep lower bound); normal boot needs sleep_ms(1000) ≥ 1000 ms (measured 1010); green under QEMU 8.2.2 (Ubuntu 24.04, container) and 10.2. Counter-checks: with an APIC the kernel hangs after sti; without EOI exactly one tick; without the PIC remap IRQ 0 hits the double fault handler with a frame one place off; without the timer gate #GP 0x102 |
| C7 | Chapter 7 – The keyboard (end of part I): ringbuf.rs (fixed-size byte ring buffer), scancode.rs (set 1 decoder, US layout as one table row per keyboard row, Shift, Caps Lock, E0/E1 prefixes skipped), keyboard.rs (IRQ 1 handler stores the byte, controller drained before unmasking, read_key with the lock taken only under cli and sti; hlt against the lost wake-up), echo loop in kmain, \x08 in the console; run-qemu.sh types with QEMU sendkey through a monitor FIFO (KEYS, KEYS_AFTER) | ✅ | 36 in-kernel tests (7 new: ring buffer, four decoder tests, buffer → read_key, backspace on the console); the normal boot check types "Hi YAK!" with Shift and Caps Lock and waits for the echo; green under QEMU 8.2.2 (container) and 10.2. Counter-checks: without the inb or without the EOI only the first key arrives; with the lock held across hlt everything stops at the first key; without the prefix rule prefixed_keys_are_skipped fails |
| C8 | Chapter 8 – Physical memory (start of part II): HHDM and memory map requests, mem.rs (PhysAddr whose only way to a pointer is the HHDM, alignment helpers), pmm.rs (bitmap frame allocator over the usable ranges only – Limine's reclaimable memory holds the live page tables, the stack and the responses; the bitmap lives in the first usable range that fits and reserves itself; next_word search, free refuses nonsense), kmain prints the memory map and round-trips a frame | ✅ | 45 in-kernel tests (9 new: helpers, four on a fake 256-frame machine, usable amount, every frame taken and chained through memory – each in usable RAM, none the bitmap – and freed again, zeroed frame). Counter-checks: without reserve the first frame is the bitmap and free_frame panics with NotAllocated; a physical address as pointer page-faults at 0x62000; bootloader memory counted as usable boots fine but the every-frame test page-faults in the HHDM |
| C9 | Chapter 9 – Paging: paging.rs (entries and tables through the HHDM, translate with huge pages, flags, map creating zeroed intermediate tables, unmap with invlpg), stack.rs (stacks in PML4 slot 510 with an unmapped guard page), fault=overflow – a real recursion on a guarded stack that ends in the double fault handler; executable address request. Found bug #26 (PAT bit of huge pages shifted translate by 4 KiB), fixed in the kernel too | ✅ | 52 in-kernel tests (7 new: indices, kernel address against Limine's, HHDM and empty lower half, map/unmap round trip costing exactly three tables, framebuffer translation (bug #26), no 4 KiB page inside a huge one, guard page unmapped); a fourth boot check for the overflow; green under QEMU 8.2.2 and 10.2. Counter-checks: guard page mapped – the overflow runs one page past the stack; without invlpg the unmapped page still reads 0xbeef; intermediate tables without WRITABLE – protection violation on write |
| C10 | Chapter 10 – The heap (end of part II): heap.rs – a free list sorted by address whose 16-byte headers live in the gaps, blocks rounded to 16, first fit with alignment padding given back, merging with both neighbours on free; #[global_allocator] behind a spin lock, an empty area in PML4 slot 507 that maps at least 64 KiB more with paging::map when a request does not fit, 16 MiB limit; extern crate alloc with Box/Vec/String/format! in kmain; fault=heap – a Vec over the limit ends in Rust's memory allocation of … bytes failed panic | ✅ | 61 in-kernel tests (9 new: four on a free list over a 16 KiB array – merging, alignment, full list, first fit; five on the kernel heap – Box/String/format in the heap area, growth, 10 000 boxes leave it unchanged, BTreeMap, over the limit is null without mapping); a fifth boot check for fault=heap; green under QEMU 8.2.2 and 10.2. Counter-checks: no merge with the following gap – 3 gaps instead of 1; alignment ignored – a 4096-aligned block 16 bytes off; sizes not rounded to 16 – misaligned pointer dereference; area not mapped – page fault at 0xfffffd8000000000 |
| C11 | Chapter 11 – A first shell (part III): words.rs (a line split into words in one pass, "…"/'…' keep spaces, empty words, UnclosedQuote), shell.rs (LineEditor – characters, Backspace that never eats the prompt, Enter, 72-character limit; a static table of six commands help, echo, clear, uptime, sleep, mem behind execute; every piece writes to a core::fmt::Write); kmain ends in shell::run() instead of chapter 7's echo loop | ✅ | 71 in-kernel tests (10 new: three on the splitter, two on the line editor, five on commands through execute into a String); the boot check types echo Hi YAK!, a Backspace-corrected echo shell, nope and mem with sendkey; green under QEMU 8.2.2 and 10.2. Counter-checks: Backspace without the guard eats the prompt (screenshot: yak), every space ending a word gives empty words, no line limit – 77 characters |
| C12 | Chapter 12 – ACPI and the APIC (part IV): acpi.rs (RSDP → RSDT/XSDT with checksums → MADT: CPUs, local and I/O APIC addresses, ISA overrides; parser over a byte slice), paging::map_device with a NO_CACHE flag for device registers at their HHDM address, lapic.rs (software enable, EOI, timer measured over 10 PIT ticks, then periodic on vector 32), ioapic.rs (SELECT/WINDOW, redirection entries, all masked, route/mask), PIC only remapped and masked; interrupts::start after memory; QEMU with -cpu qemu64 again. Found bug #27 (PIT mode 3 through the I/O APIC = 200 Hz), fixed with mode 2 | ✅ | 82 in-kernel tests (12 new: checksum, hand-made MADT, MADT without I/O APIC, QEMU's tables; local APIC present, mapped uncached, enabled, ID, timer periodic, timer ≈ 625 000 counts per tick (bug #27); 24 inputs, only the keyboard routed; two PIC tests became every_line_is_masked); boot checks unchanged; green under QEMU 8.2.2 and 10.2. Counter-checks: no EOI, override ignored, APIC not enabled – all hang after the heap lines; PIT not masked – sleep 5000 takes 2.7 s on the host clock |
| C13 | Chapter 13 – Threads and a scheduler: task.rs (threads in a BTreeMap of boxes, guarded 32 KiB stacks, switch_context in global_asm! saving rbx/rbp/r12–r15, a hand-made first stack returning into a trampoline, round-robin queue, idle thread, kmain as thread 0; preemption from the timer handler after the EOI; wait_for(wait, ready) checks and blocks with interrupts off – used by sleep_ms, read_key and join; reap frees dead threads' stacks in spawn/join, never in the interrupt), stack::free, without_interrupts, a heap whose lock is taken with interrupts off (the timer handler allocates now), shell command threads | ✅ | 91 in-kernel tests (9 new: first stack word by word, spawn/join/reap, yield turns, preemption of a loop without yield, a sleeper blocked until its tick, 160 stack frames returned, the timer allocating while a thread holds the heap, only main and idle left, threads in the shell); the boot check types threads; 7 runs under QEMU 10.2 and 3 under 8.2.2 green; sleep 5000 5.2 s on the host clock. Counter-checks: EOI after on_tick and no sti in new threads – boot stops after the first thread line; heap lock with interrupts on – 6 runs green without the new test, 3 of 3 hang with it |
| C14 | Chapter 14 – The other CPUs: smp.rs (a frame below 1 MiB reserved right after mem::init, the real → protected → long mode trampoline with hand-encoded loads, copied and filled in, identity-mapped for the start with Flags::CODE; INIT, 10 ms, STARTUP, second STARTUP; ap_main with its own GDT/TSS/double fault stack, shared IDT, local APIC on; a mailbox per CPU, run_on, wake-up IPI on vector 0xF0), IPIs in lapic.rs, gdt::init_other_cpu, the MADT's APIC ID list, QEMU with -smp ${KERNEL_SMP:-4}; the scheduler stays on the BSP. Found bug #28 in chapter 13 | ✅ | 96 in-kernel tests (4 new: all MADT CPUs online, a job runs on its CPU with its own TSS and GDT, the heap on every CPU, trampoline below 1 MiB and unmapped again); green with KERNEL_SMP=1/2/4 under QEMU 10.2 and 8.2.2; 30 boots without a hang. Counter-checks: no identity mapping – #PF on the instruction fetch after paging on, triple fault; the BSP's GDT on an AP – #GP 0x18 on ltr, triple fault; AP's APIC off – run_on waits for ever |
| C15 | Chapter 15 – One scheduler for all CPUs: task.rs with per-CPU current/idle, on_cpu per thread, the scheduler lock held through switch_context and released by the next thread (finish_switch, SCHEDULER_DATA + force_unlock), wait_for announces the block before it checks, wake_one cancels the block of a thread still on a CPU, kick_idle_cpu IPIs; a timer per CPU (only the BSP counts time), the APs' start code becomes their idle thread (join_cpu), run_on jobs run in the wake-up interrupt handler; gdt::on_double_fault_stack per CPU; joiners woken once the dead thread is off its CPU (bug #30); timer calibration window of chapters 12–15 widened (bug #29). Ends part IV | ✅ | 100 in-kernel tests (new: idle thread per CPU, a timer per CPU, threads on every CPU, 2000-round ping-pong across CPUs, lock free after switches); make test 3× in a row, unit tests with KERNEL_SMP=1/2/4. unit tests 6× more, 4 of them with the host fully loaded. Counter-checks (3× each): "check, then block" – ping-pong hangs; lock released before the switch – hangs |
| C16 | Chapter 16 – PCI and a SATA disk: pci.rs (configuration space through ports 0xCF8/0xCFC behind a lock – two CPUs must not interleave address and data –, brute-force enumerate, find, memory_bar, enable_dma), block.rs (BlockDevice, check_request), ahci.rs (controller in AHCI mode, ports by SATA status and signature, command list + received FIS + command table in one frame, IDENTIFY, READ DMA EXT through a 4 KiB bounce buffer, polling with a 1 s timeout, init once only), outl/inl; mkdisk.py makes a 1 MiB test disk whose sectors name themselves; shell commands disk and read <sector> (hex dump). Starts part V | ✅ | 111 in-kernel tests (new: host bridge and SATA controller found, empty slots, DMA on, IDENTIFY, first and last sector, 20-sector read over three commands, bad requests, init once, hex dump); make test types disk and read 5. Counter-check: bus mastering cleared → IDENTIFY times out; left out of enable_dma → no change, the firmware had set it (command register 0x107) |
| C17 | Chapter 17 – Reading FAT32: fat32.rs (FatFs<D: BlockDevice>: mount checks the BPB against itself and the disk; FAT entries with the 28-bit mask; chain refuses chains that leave the volume or run in a circle; directory entries with NT lower-case flags and VFAT long names with checksum; case-insensitive lookup, read_dir, read_file), fs.rs (SystemDisk locks ahci::DISK per access, fs::FS, mount); test disk by mkdisk.sh (mkfs.fat + mtools, 64 MiB, long names, a 196-cluster file, a directory over several clusters); shell ls, cat; CI course job installs dosfstools + mtools | ✅ | 122 in-kernel tests (new: BPB, names short/long/lower case, case-insensitive lookup, LFN checksum = mtools', files three levels deep and empty, 100 000-byte file checked byte by byte, 40-entry directory over several clusters, path errors; a zeroed boot sector and a FAT loop injected through a sector overlay give NotFat32 and Corrupt, not a hang); make test types ls and cat docs/notes.txt |
| C18 | Chapter 18 – Writing FAT32: AHCI WRITE DMA EXT (header bit W) and FLUSH CACHE EXT, BlockDevice::write/flush; fat32.rs: free clusters counted at mount (FSInfo only written), set in every FAT copy, allocate (refuses before writing, chain complete before it is hung on), free_chain, entries remember their slots and 8.3 name, free_slot grows a full directory, 8.3 names with case flags only (BadName otherwise, the alias of a long name is taken), write_file/append/create_dir/remove in a crash-tolerant order, sync = FSInfo + flush; shell write, append, mkdir, rm; check-disk.sh runs fsck.fat -n and mtools on the image after QEMU | ✅ | 132 in-kernel tests (new: write/read back, replace frees clusters, append over a cluster boundary, directories growing, removal incl. long-name pieces, name/path errors, full volume refused, free count exact); fsck.fat clean and mtools byte-exact after the unit tests and after the boot check. Counter-checks (once each, all caught by fsck.fat): one FAT copy only – "FATs differ"; long name pieces left – "Orphaned long file name part"; tests with their own mounts – "Free cluster summary wrong" |
| C19 | Chapter 19 – A block cache, and the disk's interrupt: BlockCache<D> (write-through, runs of misses as one read, least-recently-used replacement, hit/miss counters) under the file system (fs::Disk, 2048 sectors); PCI capability list + enable_msi; AHCI: GHC.IE, PxIE, handle_interrupt (errors kept in FAILED_PORTS, task::wake(Wait::Event(0x50))), commands wait in task::wait_for (polling without MSI or with interrupts off); boot counts disk commands for /big.bin: 394 without the cache, 196 through it, 0 the second time; shell disk shows commands, interrupts, cache. Ends part V | ✅ | 137 in-kernel tests (new: cache reads once / runs, write-through, LRU order, MSI capability, commands end by interrupt; the IDT test caught the new vector); fsck.fat + mtools still clean on top of the cache. Counter-check: no task::wake in the handler – the test kernel hangs at IDENTIFY (2 of 2 runs) |
| C20 | Chapter 20 – Ring 3 and the first system call: user data/code descriptors (DPL 3, selectors 0x2B/0x33); a TSS per CPU in an UnsafeCell, RSP0 set by the scheduler at every switch to a thread's own kernel stack (gdt::set_kernel_stack); USER bit propagated to every table level in paging::map; user.rs: code/data/stack pages at 0x40_0000/0x40_1000/below 0x80_0000 (mapped once – no TLB shootdowns), iretq into ring 3 with cleared registers, int 0x80 through a DPL 3 gate and an assembly entry (write with address checks: lower half, every page USER; exit; −14/−38 like Linux), faults with CS in ring 3 end the program (#GP, #PF, #UD, #DE); int 0x80 instead of syscall (no stack switch to build) – my choice for the chapter, syscall is what the reference kernel uses. Starts part VI; the last chapter for now | ✅ | 145 in-kernel tests (new: user segments DPL 3, hello + exit 42, stack, cli → #GP, kernel read and own code write → #PF, bad pointer → −14, unknown call → −38, user_bytes edges, timer preempts ring 3 (also with KERNEL_SMP=1), RSP0 = running thread's stack). Counter-checks (once each): gate without DPL 3 – every int 0x80 is a #GP; USER only on the page – #PF at the first instruction; no RSP0 – double fault (push to −8) |
| M61 | YAK 1.1.0 – the course release: version 1.1.0 in both manifests, CHANGELOG section 1.1.0 (chapters 1–20; the kernel is 1.0.0's with two test fixes), README/GOALS/ROADMAP status; I create the tag v1.1.0 and the GitHub release | ✅ | make check green (E2E: uname → "YAK 1.1.0 x86_64"); make stress green (5 passes with 1/2/4 CPUs, qemu64, UEFI, soak 10 rounds, 0 failures; 40 min); make course 20/20 – after bug #31, which the first run found (a GDT test in chapters 15–20 asked whichever CPU the test thread was on); make release: yak-1.1.0 ISO and disk image boot with BIOS and UEFI, SHA256SUMS OK; make book 0 broken links |
Log
-
2026-10-24 – Setup: Rust nightly 1.101 (rustup), target
x86_64-unknown-none, Limine v11.x-binary. M1: kernel boots via BIOS and UEFI, prints "Hello from KernelTry!" on serial, colour bars on the framebuffer (1280×800×32). -
2026-10-24 – M2: kernel split into library + binary. Custom test framework in
kernel/src/testing.rs. Integration teststests/boot.rs(Limine responses) andtests/should_panic.rs. Bug #1 found and fixed (runner did not detect test mode). -
2026-10-24 – I decided that Claude implements everything itself (no exercises for me).
-
2026-10-24 – M3: own PSF2 parser (
font.rs, Terminus 8×16, OFL) and text console (console.rs) with wrapping, tab, backspace, scrolling.print!/println!write to screen and serial.without_interruptsprepared. Addedscripts/screenshot.pyfor visual checks. -
2026-10-24 – M4: own GDT (null, kernel code 0x08, kernel data 0x10, TSS 0x18) and TSS with IST1 = 20 KiB double fault stack. CS reloaded via
retfq. -
2026-10-24 – M5: own IDT (
idt.rs), handlers for all exceptions 0–21 (interrupts.rs), readable page fault error codes. Double fault runs on IST1 (verified by a test). Limitation: real stack overflows do not fault yet because the Limine stack has no guard page (fixed with M9). -
2026-10-24 – M6: 8259 PIC remapped to 32–47, PIT at 100 Hz,
time.rs(ticks,uptime_ms,sleep_ms), spurious IRQ 7/15 handling. Bug #2: Limine masks LAPIC LINT0, so no PIC interrupt arrived → local APIC is now disabled via MSR. Works with BIOS and UEFI. -
2026-10-24 – M7: PS/2 keyboard on IRQ1. Ring buffer in the handler,
scancode::Decoder(set 1, Shift, Caps, Ctrl, Alt, AltGr, E0/E1). Layouts DE (default) and US.keyboard::read_key()sleeps race-free withsti; hlt.main.rshas an echo mode until the shell exists. New:scripts/qemu-monitor.pyfor QEMU monitor queries. -
2026-10-24 – Repository translated to English (my request). Kernel now linked with GNU ld (
ld.bfd) instead of rust-lld; added binutils make targets (disasm,symbols,sections,addr2line). -
2026-10-24 – M8:
mem/module withPhysAddr/VirtAddr, HHDM offset, bitmap frame allocator (mem/pmm.rs). Bitmap logic is independent of Limine and unit-tested with fake memory maps. 253 MiB usable with-m 256M. Base revision check moved to the very start ofkernel::init(). -
2026-10-24 – M9: own 4-level paging code (
mem/paging.rs: translate incl. huge pages, map/unmap,map_fresh,map_mmio). Kernel stacks with guard pages in PML4 slot 510 (mem/stack.rs);kmainswitches to a 64 KiB guarded stack right after init.tests/stack_overflow.rsnow overflows for real via endless recursion and checks CR2 is inside the guard page. Observed: Limine sets EFER.NXE and CR0.WP; its HHDM maps RAM + framebuffer only, no MMIO (LAPIC needsmap_mmio). -
2026-10-24 – M10: own linked-list allocator (
mem/heap.rs: first fit, splitting, address-ordered free list with coalescing) as#[global_allocator]. Heap in PML4 slot 508, 1 MiB initially, grows on demand up to 1 GiB.alloccrate enabled. -
2026-10-24 – M11: shell. Console got a character grid, inverted cursor, non-destructive
\x08and an ANSI subset (clear, home, erase line, colours). Serial input via IRQ4 +input::TerminalDecoder(UTF-8, ANSI arrows, Ctrl keys);input::read_key()merges keyboard and serial.shell/: parser with quotes/escapes, line editor (cursor movement, history, tab completion, Ctrl+C/L/U/A/E), 16 commands incl.mem,memmap,cpu,reboot,poweroff. Panics are now also shown on screen.scripts/e2e-shell.pydrives the real kernel over the serial port (make e2e,make check). Stage 1 complete: 99 in-kernel tests + 19 E2E steps green. -
2026-10-24 – I confirmed stage 2 in the proposed order (M12–M15) and asked to be consulted on open questions.
-
2026-10-24 – M12: ACPI parser (
acpi.rs: RSDP → XSDT/RSDT → MADT with CPUs, I/O APICs, overrides).paging::ensure_hhdm_mappedmaps ACPI tables / MMIO missing from Limine's HHDM. Local APIC enabled (lapic.rs), its timer calibrated against PIT channel 2 (polled, no IRQ) and running periodic at 100 Hz on vector 32. I/O APIC (ioapic.rs) routes keyboard (GSI 1) and COM1 (GSI 4); 8259 remapped + fully masked; PIT channel 0 unused. New shell commandacpi.make checknow also runs the E2E test under UEFI. Timer accuracy: 6.00 s kernel vs. 6.00 s wall clock (BIOS), 5.99 s (UEFI). -
2026-10-24 – M13: preemptive round-robin scheduler (
task/): context switch inglobal_asm!(callee-saved regs + RSP), new threads start via a trampoline, each with an 8-page guarded stack that is freed after exit. Blocking waits:Until(tick),Input(woken by keyboard/COM1 IRQs),Join(tid). Idle thread halts.sleep_ms,input::read_key,keyboard::read_keyblock instead of spinning. Timer handler sends EOI before callingtask::on_tick(which may switch threads). Shell:psanddemo [n](parallel prime-counting workers). -
2026-10-24 – I decided: the file system must be a real persistent disk (not a RAM fs). Roadmap changed: M14 = storage driver, M15 = FAT32, M16 = user space.
-
2026-10-24 – Code base formatted with rustfmt (
kernel/rustfmt.toml, max_width 120) in a separate commit. -
2026-10-24 – M14: PCI config space enumeration (
drivers/pci.rs), AHCI driver (drivers/ahci.rs: port init, IDENTIFY, READ/WRITE DMA EXT, FLUSH, polled, 4 KiB bounce frame → max 8 sectors per command),BlockDevicetrait +RamDisk(drivers/block.rs). Globaldrivers::DISKprobed once at boot. QEMU gets a SATA disk on AHCI port 0: persistentbuild/disk.imgin run mode, a fresh image per test binary, a scratch image for E2E.scripts/mkdisk.shbuilds FAT32 images fromrootfs/. Shell:lspci,disk,hexdump. Bug #3 (double probe) found and fixed. -
2026-10-24 – M15: FAT32 (
fs/fat32.rs): mount (superfloppy or first FAT32 MBR partition), FAT cluster chains with a one-sector FAT cache written through to all FAT copies, directories with 8.3 + long file names (LFN, UTF-16, checksum), read/write/append/truncate, mkdir, rm (empty dirs only), rename/move, FSInfo free-count hints,formatfor RAM-disk tests. Timestamps from the new CMOS clock driver (drivers/rtc.rs).fs::ROOTis mounted at boot. Shell: current directory in the prompt (kernel:/path>),ls cd pwd cat write append touch mkdir rm mv stat df date.make testnow validates every test disk withfsck.fat -nand mtools (scripts/check-test-disks.sh); the E2E test boots twice on the same disk to prove persistence. Session was interrupted once before the commit;make checkre-run green on resume. Thepoweroffexit-status-33 observation from before the cut did not reproduce (4/4 sessions exited with 0). -
2026-10-24 – M16: user space. GDT gets user data/code (DPL 3, order fixed by
sysret), TSS moves to 0x28, RSP0 is set on every context switch.syscall/sysretvia STAR/LSTAR/FMASK with an assembly stub (arch/x86_64/syscall.rs). Per-process address spaces (mem/address_space.rs): own PML4, kernel half shared –paging::initpre-creates all upper-half PML4 entries so they never change. ELF64 loader (process/elf.rs), process table with spawn/wait/kill and exit statuses (process/mod.rs), 7 syscalls (process/syscall.rs: exit, write, read, sleep_ms, getpid, uptime_ms, yield) with page-table checks of every user buffer. Exceptions from ring 3 kill only the process. User programs in Rust inuser/(runtimeulib+hello,upper,fault), linked at 0x40_0000 with GNU ld, installed into/binon every disk. Shell:run <path>, or just the program name for/bin(also in tab completion). Found: Limine sets USER on its upper-half intermediate page tables – cleared inpaging::init(BUGS.md pitfalls). Stage 2 complete: 156 in-kernel tests + 6 test kernels + 52 E2E steps green (BIOS and UEFI). -
2026-10-24 – I agreed to stage 3 (M17–M19) as proposed.
-
2026-10-24 – M17: per-process file descriptor table (
process::Handle: stdin, stdout, file with offset, directory snapshot; max 32) and current directory (inherited from the shell). New syscalls 7–13:open(READ/WRITE/CREATE/TRUNCATE, writes append),close,readdir,stat,getcwd,unlink,mkdir;read/writework on files.FatFs::read_atreads at an offset. The process table lock is never held during disk I/O. Argument block is now NUL-separated (ulib::Args), so quoted arguments with spaces survive.ulib::fs(File,Dir,stat,cwd); new programscat,ls,cp,fstest. The kernel shell's built-inls/catare gone –/bin/lsand/bin/catreplace them. Shell tests capture program output. -
2026-10-24 – M18: user heap. Syscall 14
brk(new_end): heap right after the ELF image, max 64 MiB, pages mapped zeroed when growing and freed when shrinking (address space borrowed out of the process table so the lock is not held while zeroing).AddressSpace::map_freshnow rolls back on failure, newAddressSpace::unmap.ulib::heap: first-fit allocator with an address-ordered free list and coalescing as#[global_allocator]– programs can useVec,String,BTreeMap,format!. New programssort(files or typed lines,-r) andheaptest. -
2026-10-24 – M19 was split: M19 = process syscalls + Ctrl+C, M20 = the shell in user space.
-
2026-10-24 – M19: syscalls 15–17
spawn(path, args)(child inherits cwd + output),wait(pid, *WaitStatus)(children only, 128-byte status with kill reason),kill(pid)(children only). Parents, orphans (removed from the table when they end) and a foreground process (inherited by children of the foreground process, given back to the parent at exit). Ctrl+C is detected in the interrupt handlers – serial byte 0x03, PS/2 via a tiny Ctrl tracker on the raw scancodes – and kills the foreground process unless it ignores interrupts (then the key is delivered as 0x03).task::wake+ interruptibleread/wait(input::read_key_or_abort,task::join_or_abort) so a blocked process dies at once.process::Options/spawn_with.ulib::process(spawn,wait,kill,run), new programspawntest,fault spin|sleep. Found: empty user buffers come with dangling pointers (0x1) – zero-length ranges are now always accessible. -
2026-10-24 – M20:
/bin/shin user space (user/src/bin/sh/). It compiles the kernel shell'sline_editor.rsandparser.rsvia#[path](shared code,shell/keys.rsprovides the key types on both sides) and decodes the terminal bytes ofread(which now delivers arrows/Home/End/Delete as VT100 sequences) with its ownkeys::Decoder. Built-ins cd (new syscall 18chdir), pwd, echo, run, history, help, exit; kernel built-ins through the transitional syscalls 19kshell/ 20kcommands; programs viaspawn/wait. The kernel starts/bin/shas init (process::run_init: foreground, ignores Ctrl+C) and falls back to the kernel shell when it is missing or exits. Bug #4 (foreground stolen by an orphan) found by the E2E test and fixed: the console is lent to a child only while its parent waits for it. Stage 3 complete: 163 in-kernel tests + 6 test kernels + 72 E2E steps green (BIOS and UEFI), init is /bin/sh. -
2026-10-24 – I agreed to stage 4 (M21–M23) as proposed.
-
2026-10-24 – M21: pipes (
process/pipe.rs: 64 KiB queue, reader/writer counts kept by cloning/droppingPipeEnds, blocking withWait::Pipe(id)+task::notify, EOF and EPIPE). Syscalls 21–24pipe,dup,dup2,isatty; children inherit fds 0–2 atspawn;kshelloutput follows fd 1./bin/sh:a | b | c,>,>>,<viadup2around each stage, errors to stderr, Ctrl+C in a pipeline kills the rest of it.ulib::io::read_linereturnsNoneat EOF / Ctrl+D and only echoes on the console;read_all,read_stdin,read_input.cat/sortread stdin, newwc,grep,pipetest. -
2026-10-24 – M22: syscalls 25–28
sysinfo(176-byte struct: uptime, memory, kernel heap, file system, CPU count/vendor/ brand, CMOS date),proclist(64-byte entries: tid, parent, state, user/kernel, CPU ticks, name),rename,seek. File descriptors now have one position for reads and writes (FatFs::write_at: overwrite, extend, zero-filled gaps); newopenflag APPEND (used by>>). New programsps,mem,uptime,df,date,mkdir,rm,touch,stat,mv; these names are no longer offered throughkshell(the kernel shell keeps its built-ins as fallback). -
2026-10-24 – M23:
/bin/edit(user/src/bin/edit/):buffer.rs(lines of chars, cursor with remembered column, insert/newline/backspace/delete joining lines; checked byedit --selftest) and a VT100 screen with horizontal and vertical scrolling, inverted status bar, partial redraw of the cursor line. ^S saves, ^Q quits (twice with unsaved changes). Kernel: syscalls 29termsizeand 30ignore_interrupt(the editor takes Ctrl+C itself), console SGR 7/27 (inverse video). Stage 4 complete: 169 in-kernel tests + 6 test kernels + 90 E2E steps green (BIOS and UEFI), 26 programs in /bin. -
2026-10-24 – I agreed to stage 5 (M24–M26) and installed
gcc(needed as host linker for-Zbuild-std). -
2026-10-24 – M24:
arch/x86_64/fpu.rsenables x87/SSE (CR0.EM/TS off, MP/NE on, CR4.OSFXSR/OSXMMEXCPT) and records a clean initial FXSAVE image. Every thread owns a 512-byteFxState;schedule()doesfxsave64for the outgoing andfxrstor64for the incoming thread (eager). The kernel stays soft-float. User programs now use their own targetuser/x86_64-kerneltry-user.json(SSE2, hard-float ABI, static, small code model, red zone allowed) with-Zbuild-std=core,alloc. New programfputest. Check: with the save/restore removed, all 4 workers report corrupted XMM. -
2026-10-24 – I chose our own INIT/SIPI start (not Limine's MP feature). M25 was split: M25 = starting the cores, M26 = scheduling on them, M27 = network.
-
2026-10-24 – M25:
arch/x86_64/smp.rs.pmmreserves one frame below 1 MiB before anything else; the trampoline (global_asm!, 16 → 32 → 64 bit, data accesses hand-encoded because the assembler rejects label differences in memory operands) is copied there, patched with its physical addresses, the kernel PML4 and a per-AP stack, and temporarily identity-mapped. INIT, 10 ms, SIPI (twice if needed) per AP via new LAPIC IPI functions.ap_main: own GDT/TSS (now arrays per CPU) with its own double fault stack, shared IDT, FPU/SSE, syscall MSRs, local APIC, thenhltuntil aWAKE_VECTORIPI brings a job (smp::run_on). QEMU runs with-smp 4;cpulists the online CPUs. -
2026-10-24 – M26: the scheduler runs on every core. Per CPU: current thread, idle thread (APs turn their start-up context into it), LAPIC timer (calibrated once on the BSP; only CPU 0 advances
time::ticks). Shared ready queue;schedule()keeps the scheduler lock across the context switch and the next thread releases it (finish_switch), so a thread that is still being switched out (on_cpu) can never be picked by another CPU.block_currentreplaced bywait_for(reason, ready): mark blocked first, then check – no lost wake-ups across CPUs; wakers on a thread stillon_cpujust set it running. Idle CPUs get a wake-up IPI when a thread becomes ready. Syscall stub: per-CPU slots throughswapgs/IA32_KERNEL_GS_BASE, swapped back before interrupts are enabled.psshows the CPU a thread runs on.KERNEL_SMP=<n>selects the core count. -
2026-10-24 – M27:
drivers/e1000.rs(82540EM: reset, MAC from RAL/EEPROM, 32 RX / 8 TX descriptors with 2 KiB DMA buffers, polled) andnet/(packet.rs: Ethernet II, ARP, IPv4 with checksum, ICMP echo, UDP with pseudo-header checksum;mod.rs: static config for QEMU user networking 10.0.2.15/24 via 10.0.2.2, ARP cache + resolution, net thread polling every 10 ms, answers ARP and pings, ping replies, UDP sockets with receive queues; waits useWait::Net). Syscalls 31–35net_info,ping,udp_socket,sendto,recvfrom(5th argument in R8);Handle::Udp. Programsping,netinfo,udpecho. QEMU gets-netdev user -device e1000(KERNEL_NETDEV_OPTSfor extras). Bug #5 (run_oncould starve the target CPU's idle thread) fixed. Stage 5 complete: 185 in-kernel tests + 6 test kernels + 94 E2E steps (BIOS + UEFI). -
2026-10-24 – I want all of the stage 6 ideas; order M28–M33 chosen by dependencies.
-
2026-10-24 – M28:
arch/x86_64/tsc.rscalibrates the time stamp counter against PIT channel 2 (50 ms, after the LAPIC calibration);time::uptime_us. Syscall 36clock_us. Ping replies are time-stamped in µs (pingprints ms with three decimals – the receive time is still when the net thread polls, i.e. up to 10 ms late). New programtime <program>. -
2026-10-25 – M29:
net/tcp.rs(state machine, go-back-N retransmission with RTT-based RTO, windows, loopback for our own address), syscalls 37–40tcp_connect/tcp_listen/tcp_accept/shutdown,read/write/closeon connections, programsncandechod, kernel commandnetstat. Bug #6 fixed: the boot CPU's idle thread did not runsmp::run_onjobs (hang when a thread on another CPU sent a job to CPU 0); one idle loop for all CPUs now, regression test added. IPIs are sent with interrupts off; SMP-robust leak tests (pmm::frames_lost). -
2026-10-25 – M30:
net/dhcp.rs(DISCOVER/OFFER/REQUEST/ACK with the broadcast flag;net::initwaits up to 3 s per step, static fallback otherwise); the network config is now mutable (dns,dhcpflag) and accepts all packets to our MAC while unconfigured. DNS client in user space (ulib::dns: query building, compressed-name parsing, retries; server fromnet_info, which now reports DNS and DHCP). Programshost,wget(HTTP/1.0,-O file),httpd(files below the cwd, directory listings, 403/404/405). -
2026-10-25 – M31: per-process environment in the kernel (inherited at
spawn, init getsPATH=/bin,HOME=/), syscalls 41–43setenv/getenv/environ,waitflag WNOHANG./bin/shrewritten around it:$NAME/${NAME}/$?/$$/$#/$0..$9expansion (not in '...',\$escapes),#comments,NAME=value/export/unset,$PATHlookup,2>/2>>/2>&1, background jobs (&,jobs,wait,fg, "Done" before the prompt), scripts (sh file args,sh -c,source/.,#!files run throughsh,set -e),true/false,exitdefaults to$?. New programenv. Found: lines of concurrent programs were mixed mid-line becauseprintln!wrote every format piece separately – theulibprint macros now format first and write once. -
2026-10-25 – M32: measured first (300 KB through
wc: 0.12 s;read_atin 4 KiB steps: 94 ms – the disk itself needs only ~3 ms, the time went into walking the FAT chain and the directory on every call). Now:BlockCache(write- through sector cache, 512 KiB, LRU by eighths) under the root file system,read_atreads contiguous clusters with one request, FatFs caches the last cluster chain and the last path lookup (both dropped on any write). Result:read_at94 → 5 ms,wcof 300 KB 0.12 → 0.038 s. AHCI completes commands by MSI (PCI capability list,Device::enable_msi): the waiting thread blocks onWait::Diskinstead of spinning (single commands get slower, ~2×, but the CPU is free); polling remains for early boot. Bug #7 (an idle CPU only noticed threads woken by its own interrupts at the next tick) found withKERNEL_SMP=1and fixed (task::preempt_idleat the end of waking interrupt handlers). -
2026-10-25 – M33:
mem::reclaim_bootloader_memory(first thing inkernel_main, on our own stack): copies every page table that lives in bootloader memory (paging::copy_kernel_tables, the mappings stay identical), points every thread (task::retarget_cr3) and every CPU (smp::run_on+ CR3 reload) at the new PML4, then frees the regions (pmm::release_region; the bitmap now covers them from the start). The memory map is copied at boot (pmm::boot_memmap) because Limine's lives in that memory. QEMU with 256 MiB: ~11.7 MiB gained. Demand paging:brkonly moves the heap end; a not-present user fault inside the heap maps a zeroed page and retries (process::handle_page_fault), syscalls populate heap pages before checking user buffers. Stage 6 is complete. -
2026-10-25 – M34: signals (
process/signal.rs): dispositions, pending mask,kill(pid, sig),sigaction,sigreturn; delivery when returning to ring 3 after a syscall or a timer/wake interrupt. Handlers run through a trampoline inulibthat saves all registers itself – the kernel only pushessig, handler, rflags, rip(so the user target now hasdisable-redzone). Ctrl+C sends SIGINT (raw 0x03 only forignore_interruptprograms without a handler);sleepis interruptible;$?of a signalled child is 128 + signal; sh built-inkill [-SIG] pid|%job,kill -l. Bug #8 (MSI test assumed one interrupt per command – MSIs coalesce in the APIC) found while running with 2 CPUs. -
2026-10-25 – M35:
/bin/shbecame a small POSIX-like language: tokenizer + recursive-descent parser (syntax.rs) into lists / and-or / pipelines / compound commands / functions, executed with aFlowresult;$((...))(arith.rs),test/[(testcmd.rs),read,shift,:, wildcards (glob.rs), continuation prompt, compound commands with redirections and in pipelines (cat f | while read l; do ...; done), background compound commands viash -c. Ctrl+C stops loops (SIGINT handler + children killed by SIGINT). Kernel: file offsets are now shared betweendup-ed descriptors (the shell's fd save/restore re-read the same line forever otherwise), user stacks grow on demand up to 1 MiB (4 pages mapped at start). Bug #9 (run_onpriority inversion between idle thread and waiter) fixed. -
2026-10-25 – M36: threads.
thread_spawn/thread_exit/thread_join/gettid, every user thread has anowner(the pid) in the scheduler; process end with running threads viaexiting(the main thread joins the others before freeing the address space); futexes (process/futex.rs) andulib::sync::Mutex, thread-safe user heap,ulib::thread::spawn. TLB shootdown forbrkshrinking with threads. Kernel: sleepingsync::Mutexfor the disk and the root file system (found while writing its test:bool::then_somebuilt the guard eagerly, so a failedtry_lockunlocked somebody else's lock -thenis lazy). -
2026-10-25 – M37: QEMU now runs
-cpu max(TCG;KERNEL_CPUoverrides). SMEP + SMAP on every CPU that has them, user memory only insidecpu::user_access(stac/clac);read_stdinnow copies withcopy_to_userafter its wait. XSAVE with XCR0 = x87 | SSE | AVX, 1 KiBFpuStateper thread; the signal trampoline usesxsave64. User programs stay SSE2 and detect AVX at run time. Bug #10 (test IDTs without IRQ vectors, exposed by the slower CPU model) fixed. -
2026-10-25 – M38: QEMU's e1000 has no MSI, so
net::probe_irqfinds its I/O APIC input by trying GSI 16-23 with a software-raised interrupt (ICS); the net thread now sleeps until the card interrupts (ping to the gateway 2–10 ms → ~0.5 ms; loopback packets wake it too). TCP window scaling (shift 3, 256 KiB buffers, 128 segments in flight); DHCP lease renewal thread (T1 renew, T2 rebind, static fallback at the end). Stage 7 is complete. -
2026-10-26 – User wrote a project definition ("KernelTry – Understand the Kernel"): recorded as a proposal in
docs/GOALS.md. Stage 8 (M39–M46) planned around its release criteria. M39:README.md(overview, screenshotdocs/images/shell.png, host packages, quick start, documentation map), Makefile finds OVMF on Fedora and Debian/Ubuntu (OVMF ?=, override withmake OVMF=<file>). Found while setting up a fresh Ubuntu container: no toolchain pin (stable rustc fails on the user target), hard-coded Fedora OVMF path – both feed M40. -
2026-10-26 – I chose the license (ECPL v1.2, my own text) and the name KernelTry. M40:
rust-toolchain.tomlpins nightly-2026-10-26 (rustc 1.101.0-nightly 76456a688) with rust-src, rustfmt and thex86_64-unknown-nonetarget;scripts/check-deps.sh/make deps(Fedora/Debian package names, OVMF, rustup) is the first step ofmake check.license-fileset in both Cargo manifests. -
2026-10-26 – M41:
syscheckfound five kernel bugs on its first runs – #11 a huge length froze the machine (populatewalked every page), #12 an empty buffer with a null pointer panicked the kernel, #13readdirlost an entry on EFAULT, #14 a user copy raced withbrkin another thread (kernel page fault → panic), #15 TLB shootdowns waited for idle CPUs (seconds, or forever with busy CPUs). Fixes: boundedpopulate, empty copies never touch the pointer, check-before-advance inreaddir, check + copy under the process table lock in ≤ 64 KiB pieces, aTLB_VECTORIPI.make soak(10 rounds ≈ 1–2 min) andmake stressadded.syscheck racewith 4 CPUs: 4 → ~3500 heap shrinks in 5 s. DESIGN.md listed the wake-up IPI as 0x60; it is 0xF0 (fixed). -
2026-10-26 –
make stress(5 passes) of the M41 commit: green – 20 × E2E 126/126 with 1/2/4 CPUs andqemu64/UEFI, everymake testgreen, soak 10 rounds, 26 min in total. M42: #16 fixed (sys_writein 64 KiB pieces,sendtosize check before the copy); the open items became "Known limitations of release 1.0". M43–M45: walkthroughs, experiments (all four run and measured), HACKING.md with syscall 52unameas the worked example,CHANGELOG.md,make docs-check. -
2026-10-26 – User switched the license to the GNU GPL v3 (taken as
GPL-3.0-or-later, the FSF's recommended wording) and wants a pre-release before 1.0. M46:LICENSEfrom Ubuntu'sbase-files(/usr/share/common-licenses/GPL-3, identical to the FSF'sgpl-3.0.txt– gnu.org itself is blocked by the sandbox proxy), dependency licenses checked (limine, lock_api, scopeguard: MIT OR Apache-2.0; spin: MIT; Limine bootloader: BSD-2-Clause – all GPLv3-compatible), version 1.0.0-rc.1 – renamed to 0.8.0 at my request (0.x = not yet stable, as SemVer intends). -
2026-10-26 – Stage 8 merged into
main(FreakySneaky787/yak-kernel#1, merge commita75812b). I published the GitHub pre-release v0.8.0 on that commit (tag pushes are not possible from Claude's sandbox). -
2026-10-26 – I decided the direction for the next 1–2 years: a learning platform for self-learners and hobby kernel developers; an English course in which learners rebuild the kernel chapter by chapter (one branch per chapter), published as a website; I steer, Claude builds. Written down in
docs/ROADMAP.md;docs/GOALS.mdupdated; stages 9 (CI, 1.0) and 10 (course infrastructure) planned. -
2026-10-26 – M47: CI on GitHub Actions (FreakySneaky787/yak-kernel#2). Fedora was tested for the first time (its mirrors are blocked in the sandbox):
make deps, the OVMF path (/usr/share/edk2/ovmf/OVMF_CODE.fd) and the whole suite work there unchanged. The only failure was the TLB shootdown test's 50 ms limit (~75 ms on the runners, bug #17), now 1 s. A Ubuntu job takes ~3.5 min, Fedora ~4 min. -
2026-10-26 – CI paid off at once: besides #17 it showed a Fedora-only failure (
sortkilled below its stack). Root cause, reproduced locally with a new test: an SMP race inprocess::spawn_with– a new program could run its first syscall before its process table entry existed (#19), plus a panic handler that needed the heap. A local E2E repetition also showedsleep_msending up to a tick early (#18). All three fixed with regression tests that fail on the old code;make checkandmake stress STRESS_N=1green. -
2026-10-26 – M47 merged (FreakySneaky787/yak-kernel#2,
7f8f5b2). M49: the website is mdBook overdocs/(no copy of the docs); mdBook 0.4.52 is a host tool (cargo install), not a kernel dependency. GitHub Pages must be switched to "GitHub Actions" by me before the first deploy. -
2026-10-26 – M50 + pilot chapters 1–3. Chapters live as folders in
main(the sandbox cannot push other branches; I chose folders). Every code block on a chapter page that names a file is checked against the chapter folder, so the text cannot drift from the code. Found while writing chapter 3: a dash (U+2013) is drawn as?by a Latin-1 font table – kept as a "what can go wrong" note. -
2026-10-26 – The project is called YAK – Yet Another Kernel (my decision; "KernelTry" was the working name). Renamed everywhere except in this log: boot banner,
uname, disk labelYAK, user targetuser/x86_64-yak-user.json, the course chapters, website and docs. -
2026-10-27 – Stage 11 after an outside review of the docs. Checked every point against the code: the block-cache contradiction was real (bug #20), "the purpose is undecided" was not (GOALS fixes it). M52 found bug #21 while laying out the thread stacks. M53's fault tests found no bug, but two kinds of damage beyond lost clusters (chain longer than size, two names after rename) – both inherent to FAT32 without a journal, now documented.
-
2026-10-27 – Stage 12 (M54–M59).
make stress(5 passes) on the M59 commit: first red – the new TCP loss test ran into the 30 s limit of its test kernel with 4 CPUs (bug #22, the test's size, not a hang); after the fix green: 20 × E2E 135/135 with 1/2/4 CPUs andqemu64/UEFI, everymake testgreen (TCP loss test ≤ 5.0 s), soak 10 rounds, about 33 min in total. -
2026-10-27 – M48: version 1.0.0. I decided to release without waiting for the outside reader.
-
2026-10-29 – M60: a first-reader pass before handing the pilot to somebody else. The code was fine – every chapter folder builds alone – but a reader typing along from the pages would have got stuck at the end of chapters 3 and 4: the lines in
kmainthat call the new code were only in the folders. A coverage script showed it; the pages now show those lines, anddocs/HACKING.mdsays every change a learner has to make appears on the page.make checkbefore the commit found bug #24 (a test, not the kernel). -
2026-10-29 – C5: chapter 5, interrupts and exceptions. A handler for a crash is only proven by a crash, so the chapter's kernel takes
fault=page/fault=stackon its command line andmake testboots it three times. The double fault comes without guard pages (those are part II): the stack pointer is pointed at unmapped memory and pushed to. Every claim on the page that says what happens was checked by a run –-d intshows the chainv=0e,v=08, triple fault when the IST index is missing. -
2026-10-29 – C6: chapter 6, PIC and timer. Bug #2 (Limine masks LINT0, so PIC interrupts never arrive with the local APIC on) is still true with Limine 11. The chapter first switched the APIC off like M6 did – green locally, red in CI: QEMU 8.2 drops the interrupts anyway (bug #25). The chapter now runs on a CPU without APIC. The counter-check without the PIC remap is the best example for chapter 5's "one place off" warning: the timer IRQ lands on vector 8, and the double fault handler prints the interrupted RIP as its error code.
docs/LEARN.mdnamed a PIT divisor of 11932; the code has always computed 11931. -
2026-10-29 – C7: chapter 7, the keyboard – part I is complete. A keyboard test needs somebody to type, so
run-qemu.shfeeds QEMU's monitor through a FIFO and types withsendkeyonce the kernel says it is ready (only bash and QEMU, no new host tool). I kept the layout to US: it is one table of five strings, and QEMU's key names are US positions; a German layout is experiment 1. The page says honestly that with a 100 Hz timer the lost wake-up costs at most one tick –sti; hltmatters once nothing else wakes the CPU. Chapters 5–7 also lost a compiler warning (a function cast straight to an integer in a test). -
2026-10-29 – C8: chapter 8, physical memory – part II begins. I kept the chapter to the bitmap allocator and left out what the reference kernel added later (taking back Limine's memory, a frame below 1 MiB for the other CPUs). The strongest test takes every frame there is and chains them through memory; it is also the only thing that catches the most dangerous mistake, counting Limine's memory as usable – the kernel itself boots fine with it.
-
2026-10-29 – C9: chapter 9, paging. My test that
maprefuses a page inside a huge page first assumed the HHDM was built from 1 GiB pages; a diagnostic walk showed 2 MiB pages, with 4 KiB pages at the edges of the ranges. The same walk over the framebuffer showed bug #26: its 2 MiB entries carry the PAT bit, andtranslate– mine and the reference kernel's – read it as an address bit. Fixed in both, with a test in both. -
2026-11-01 – C10: chapter 10, the heap – part II is complete. The heap starts with nothing mapped; the first
Boxmaps its first 64 KiB, so the chapter needs noinitand shows that a heap is just frames andmap. I kept the spin lock with interrupts on and wrote on the page why that holds only while no handler allocates (the reference kernel turns them off). The counter-check with unrounded sizes did not corrupt memory silently: Rust's debug checks stopped it at the first misaligned gap pointer. -
2026-11-01 – C11: chapter 11, a first shell – part III. I kept it to the keyboard: serial input, escape sequences, history and completion are named on the page as what the reference shell has besides. The decision that carries the chapter is that every piece writes to a
core::fmt::Write, so the tests compare the exact bytes a command prints – including the\x08 \x08of the line editor. -
2026-11-01 – C12: chapter 12, ACPI and the APIC – part IV begins, and the course's QEMU has a local APIC again. All tests were green and
sleep_ms(1000)said 1010 ms when I timedsleep 5000in the shell on the host clock: 2.7 s. The PIT in mode 3 gave two interrupts per period through the I/O APIC, so the APIC timer was calibrated to 5 ms (bug #27). Mode 2 fixed it, and a test now checks the calibration against QEMU's known APIC rate – a clock cannot be tested against itself. -
2026-11-01 – C13: chapter 13, threads and a scheduler. Chapter 10 had said the heap's lock may stay with interrupts on as long as no handler allocates; this chapter's timer handler does, so the heap now locks with interrupts off. Removing that again passed six test runs – the race is rare – so I wrote a test that provokes it: a thread allocating in a loop while main wakes up twenty times; without the fix it hangs every time.
-
2026-11-01 – Bug #28 in chapter 13, found while testing chapter 14: the boot hung about once in 20 because
task::initbuilt the scheduler in steps with interrupts on. I booted in a loop until it hung and read RIP through the QEMU monitor – the idle thread'shlt, withmainlost. Fixed in chapters 13 and 14. -
2026-11-01 – I decided to move the FPU chapter (M24) from part IV to part VI: the course kernel has no SSE and no user programs yet, so there is nothing to save. C14: chapter 14, the other CPUs. The trampoline is the reference kernel's, explained; the APs only run jobs, the scheduler stays on the BSP. Every mistake I tried in the start path ended in a triple fault of the whole machine, so the page shows how to read QEMU's
-d intlog. -
2026-11-06 – C15–C20 in one day, one PR each. I first decided to finish the course to part VIII, then the same day to stop at chapter 20 for now, and to release the course as 1.1.0 (M61). CI found one timing assumption in C15, load runs two more (bugs #29, #30); a GitHub runner hung for 11 minutes in
apt-getonce (re-run, green). In C18fsck.fatcaught my own first version of the write tests (two mounts of one disk, a wrong free count). M61, release 1.1.0:make check,make stressandmake releasegreen at the first run;make coursefound bug #31 (a test, not the kernel) – fixed in chapters 15–20, then 20/20.
Known limitations of releases 1.0 and 1.1 (sorted in M42, checked for 1.1 in M61)
Release blockers were defined as "a program can crash, hang or exhaust the kernel" (docs/GOALS.md: isolated
programs, reliability). All of those found so far are fixed (bugs #11–#16). The rest are documented limitations:
they make YAK smaller than a production system, but they do not break the promises of release 1.0.
Security model
- Single user, no permissions: every program may signal any process (
kill), read and write every file, and use the kernel-command bridgekshell– includingreboot,poweroff,panicandint3, which exist for teaching. Isolation means memory isolation: a program cannot read or corrupt another program's or the kernel's memory. - The kernel heap grows on demand but never shrinks.
User space
- No AVX-512; the ELF image is mapped eagerly (heap and stack on demand); no thread-local storage; thread stacks are fixed at 256 KiB (64 slots); no SIGCHLD/SIGSTOP/alarm, no signal masks; a CPU exception cannot be caught as a signal.
/bin/sh: no here-documents, no[...]character classes in patterns; variables hold up to 4096 bytes (256 of them);&&/||/|/&must be separate words; functions are not inherited bysh -cbackground shells; built-ins, functions and loops inside a pipeline must fit their output into one pipe (64 KiB) – more blocks until Ctrl+C; background jobs share the keyboard with the shell.- Input lines up to 4096 characters; on a serial terminal they wrap correctly only if it is at least as wide as the console (160 columns).
kshell/kcommandsbridge the commands that are still kernel built-ins: cpu, acpi, lspci, disk, hexdump, memmap, layout, demo, colors, version, int3, panic, reboot, poweroff, write, append, echo, sleep, clear, help. Without/binon the disk, the kernel shell has nols/cat.
Files and network
- FAT32 without a journal: a power loss or disk error in the middle of a command can leave lost clusters, a chain
longer than its file or (rename) two names for one file –
fsck.fatrepairs it, nothing runs it at boot (M53). - FAT32 only;
read/write_atre-walk the cluster chain per call; directory handles are snapshots; no truncate-to-length. - IPv4 only: no fragmentation, no SACK / persist timer, DNS A records only; the e1000 interrupt line is found by probing (no AML interpreter).
Hardware and tools
- QEMU is the reference machine (q35, e1000, AHCI, PS/2, COM1); real hardware is not a goal of 1.0.
make limine-tool(bios-install for USB/HDD images) exists but has not been tried.psCPU percentages only cover threads that still exist (dead threads are reaped with their counters).- Under TCG (no KVM)
make checktakes about 2 minutes on a warm build,make stress(5 passes) about 30 minutes.
Course (1.1)
- The course ends at chapter 20 (my decision of 2026-11-06): ring 3 with one address space and two system calls. Own address spaces, programs from the disk, processes, the network and hardening are in the reference kernel and its walkthroughs, not yet in the course. No exercises, diagrams or glossary yet (phase E).
- The pilot (chapters 1–4) still waits for its first outside reader.
Open after 1.0
- A first reader: somebody who did not build YAK follows README → the course → one experiment and reports where they got stuck. That is the real test of the "understandable" goal.
- Optional: license headers (
SPDX-License-Identifier: GPL-3.0-or-later) in every source file – the GPL's "How to Apply" recommends a notice per file.
Next step
1.1.0 is prepared (M61): version, CHANGELOG, status texts; the course has chapters 1–20 (part IV ended with one
scheduler for all CPUs, part V goes from PCI and a SATA disk to FAT32, a block cache and disk interrupts, chapter 20
runs code in ring 3). Next: I create the tag v1.1.0 on the merge commit and publish the GitHub release
(docs/RELEASING.md, steps 6–8); the release workflow attaches the files. After that nothing is planned until I
decide again – chapters 21–36 (plan in docs/ROADMAP.md) and phase E wait for that decision; an outside reader for
the course is still open.
Making a release
A release is a version number, a git tag and files anybody can run with nothing but QEMU. This page is the checklist; every step names the command that proves it. Claude prepares everything up to the pull request; I create the tag and the GitHub release (tags cannot be pushed from Claude's sandbox).
Before the release
- Version in
kernel/Cargo.tomlanduser/Cargo.toml(both the same;scripts/release.shrefuses otherwise). The boot banner andunameshow it. CHANGELOG.md: the "Unreleased" section becomes## <version> – <date>.- Tests, on the commit that becomes the release:
make check– unit and integration tests, end-to-end shell sessions under BIOS and UEFI;make stress– the suite 5 times with 1, 2 and 4 CPUs,qemu64, UEFI, then the soak test (about 30 minutes under TCG); the result goes into the log indocs/PROGRESS.md;make course– every course chapter builds and passes its test;make book– the website builds without broken links;make release– the release files are built and booted once (BIOS and UEFI).
- Known limitations in
docs/PROGRESS.mdare current: everything that does not work is listed there. - Pull request; CI must be green on Ubuntu and Fedora; merge.
The release
- On GitHub: Releases → Draft a new release, tag
v<version>on the merge commit ofmain, titleYAK <version>, text from theCHANGELOG.mdsection; for a version before 1.0 tick "Set as a pre-release". Publish. - The workflow release (
.github/workflows/release.yml) starts by itself: it checks out the tag, runsmake release(which refuses a tag that does not match the version) and attachesyak-<version>.iso,yak-<version>-disk.img.gz,run-yak.shandSHA256SUMSto the release. If it fails, nothing is attached; it can be run again by hand (Actions → release → Run workflow, with the tag). - Check the download: the release page shows the four files; on a machine with QEMU,
sha256sum -c SHA256SUMSand./run-yak.sh(README, "Try it without building").
What a release promises
What make check tests, on the machines in README "Supported environment" – nothing more. Everything else is either
a documented limitation (docs/PROGRESS.md) or a bug (docs/BUGS.md).